
SWE-Git-Bench: A Worktree-Level Benchmark for Real Merge Conflict Resolution
Abstract
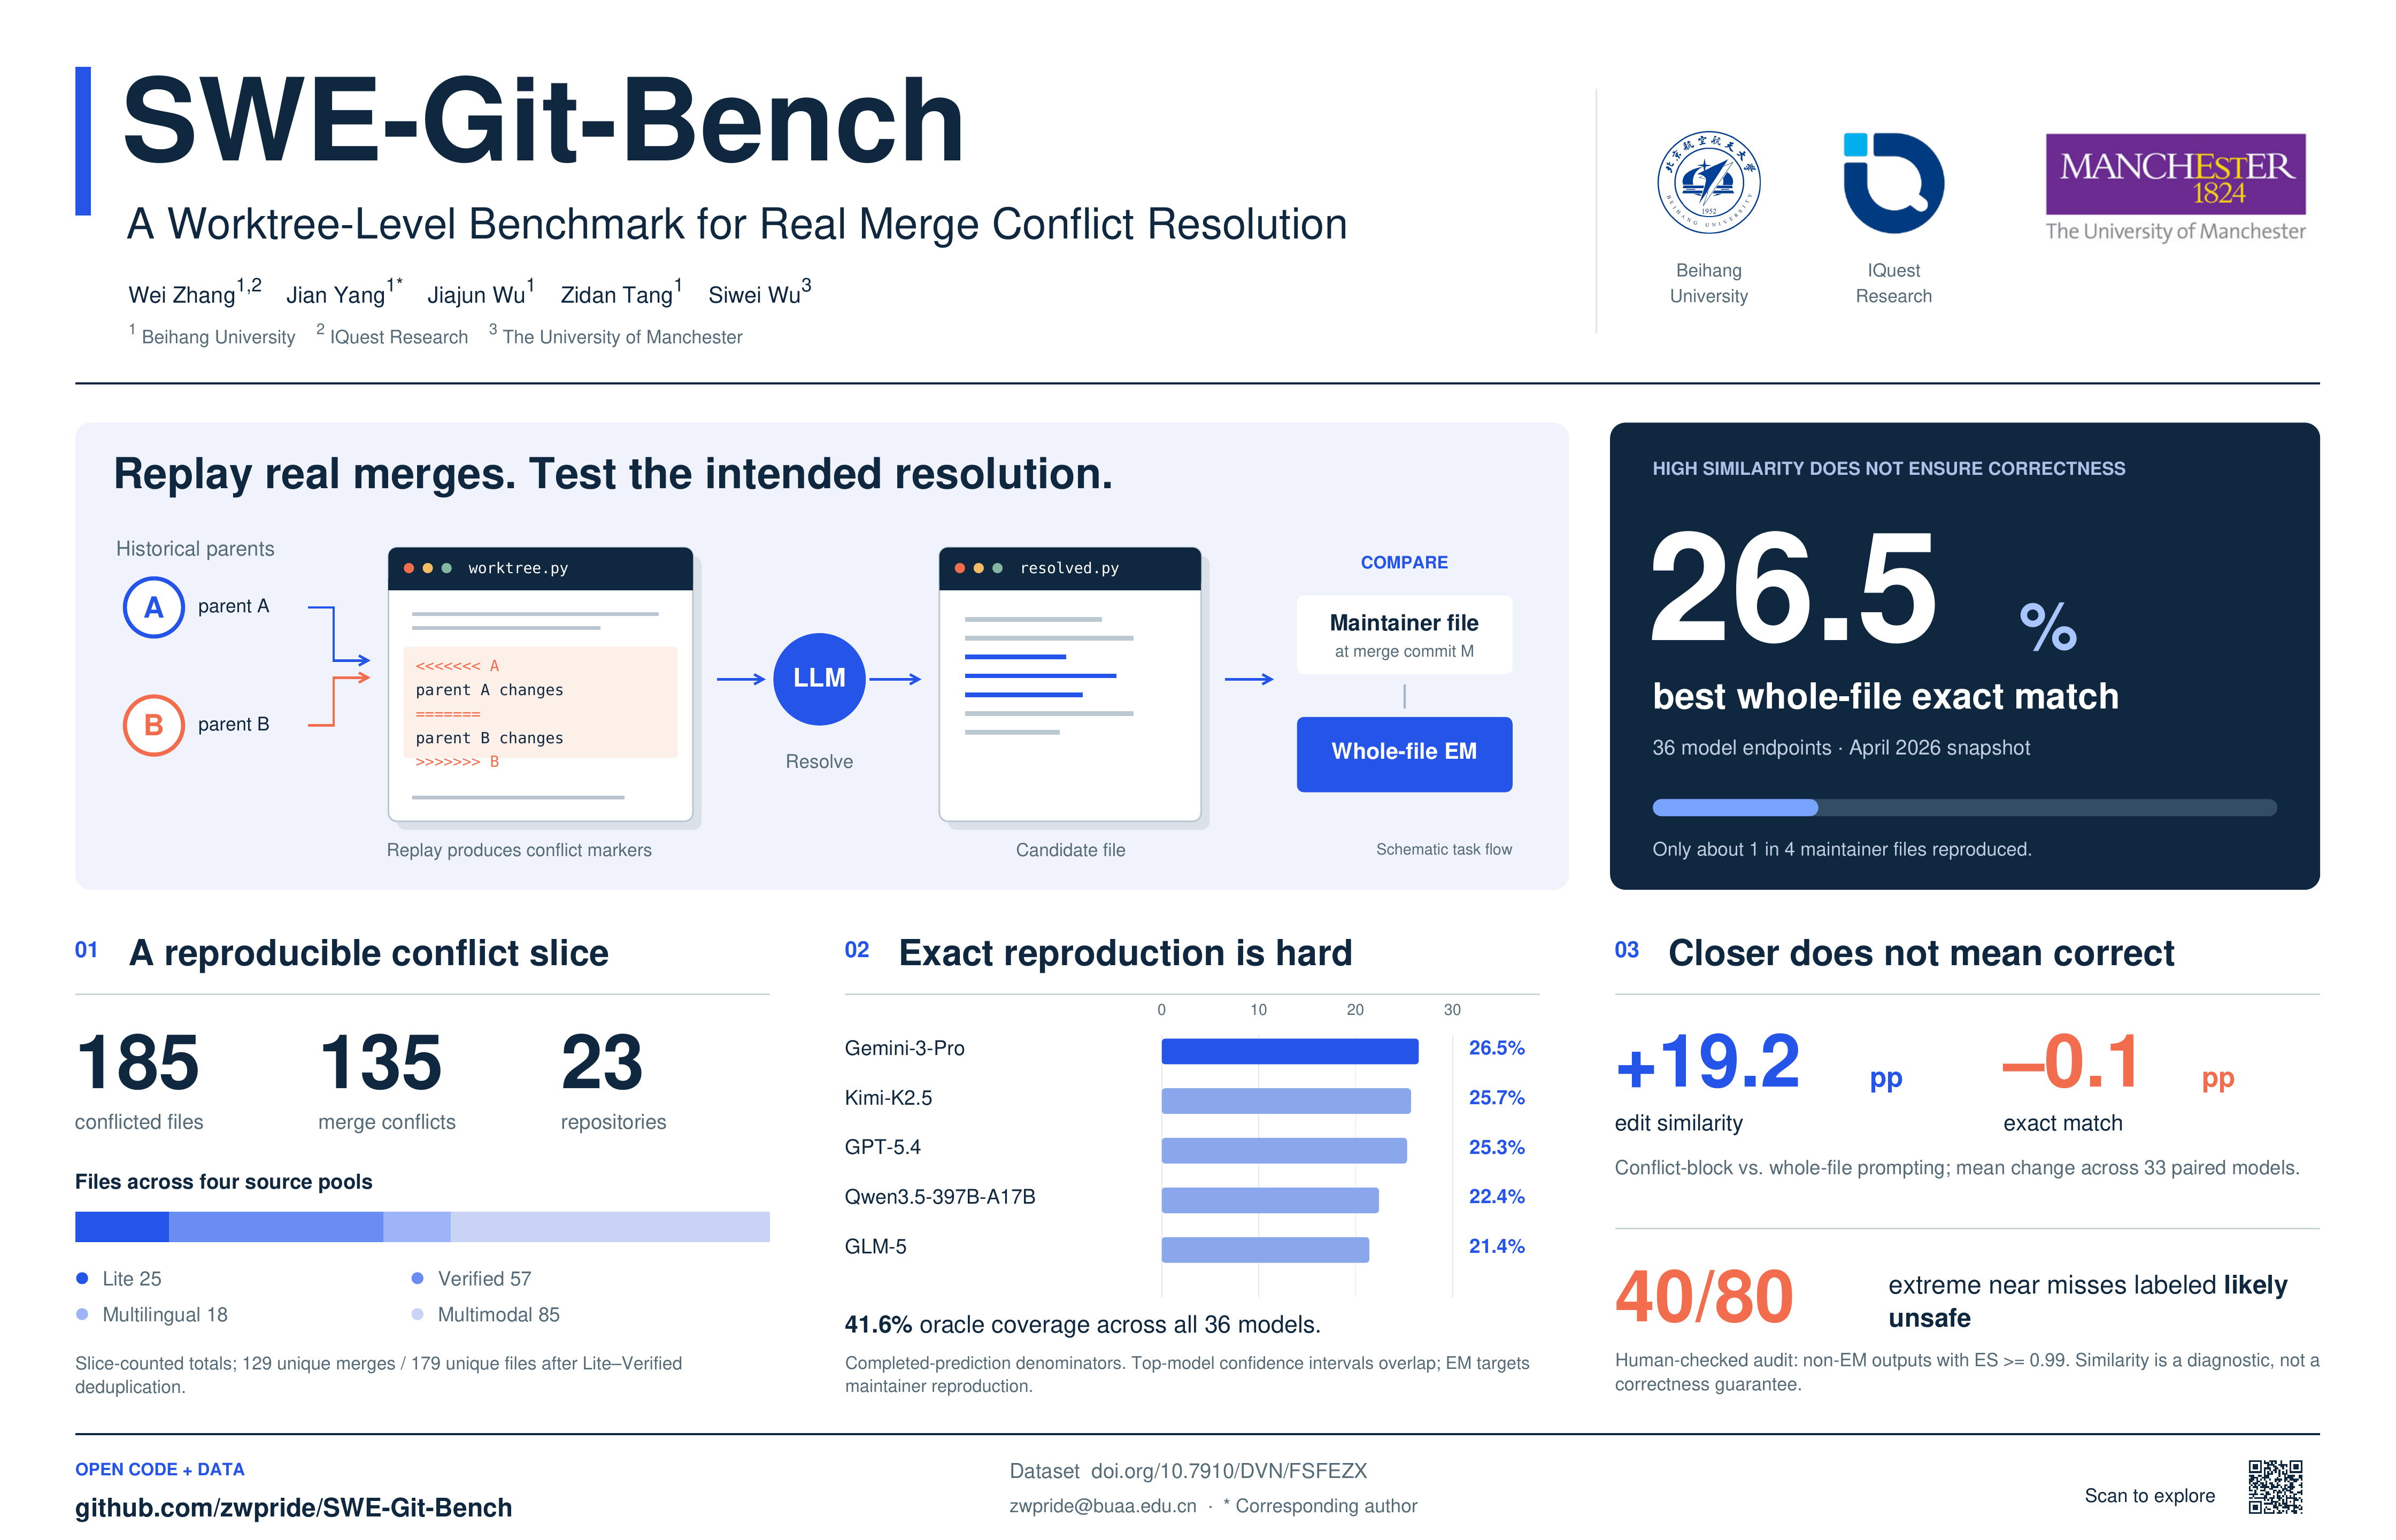
Large-language-model code benchmarks mostly measure issue repair or fresh synthesis, but they do not isolate a common commit-gating operation: after git emits conflict markers, a resolver must leave the worktree file ready to commit. SWE-Git-Bench turns this operation into a reproducible benchmark. We replay real two-parent merges from SWE-bench-family source pools, retain files where replay produces conflict markers, and use the maintainer-committed merge file as the reference. The release contains 135 slice-counted conflicts and 185 conflicted-file examples from 23 repositories; after collapsing Lite/Verified overlap, these correspond to 129 unique merge commits and 179 unique conflicted files. In an April 19–22, 2026 snapshot of 36 LLM endpoints, the best whole-file exact match is only 26.5%, and an oracle union across all models covers 41.6% of files. Conflict-block prompting raises edit similarity by +19.2 pp but changes exact match by only -0.1 pp, showing that an easier output interface does not by itself recover merge intent. A human-checked audit of 80 whole-file non-EM outputs with ES ≥ 0.99 labels 40/80 likely unsafe. We release public code and data, canonical JSONL artifacts, Core Croissant plus Responsible-AI metadata, scoring harnesses, model predictions, difficulty bands, and failure analyses.