
LocCa: Visual Pretraining with Location-aware Captioners
Abstract
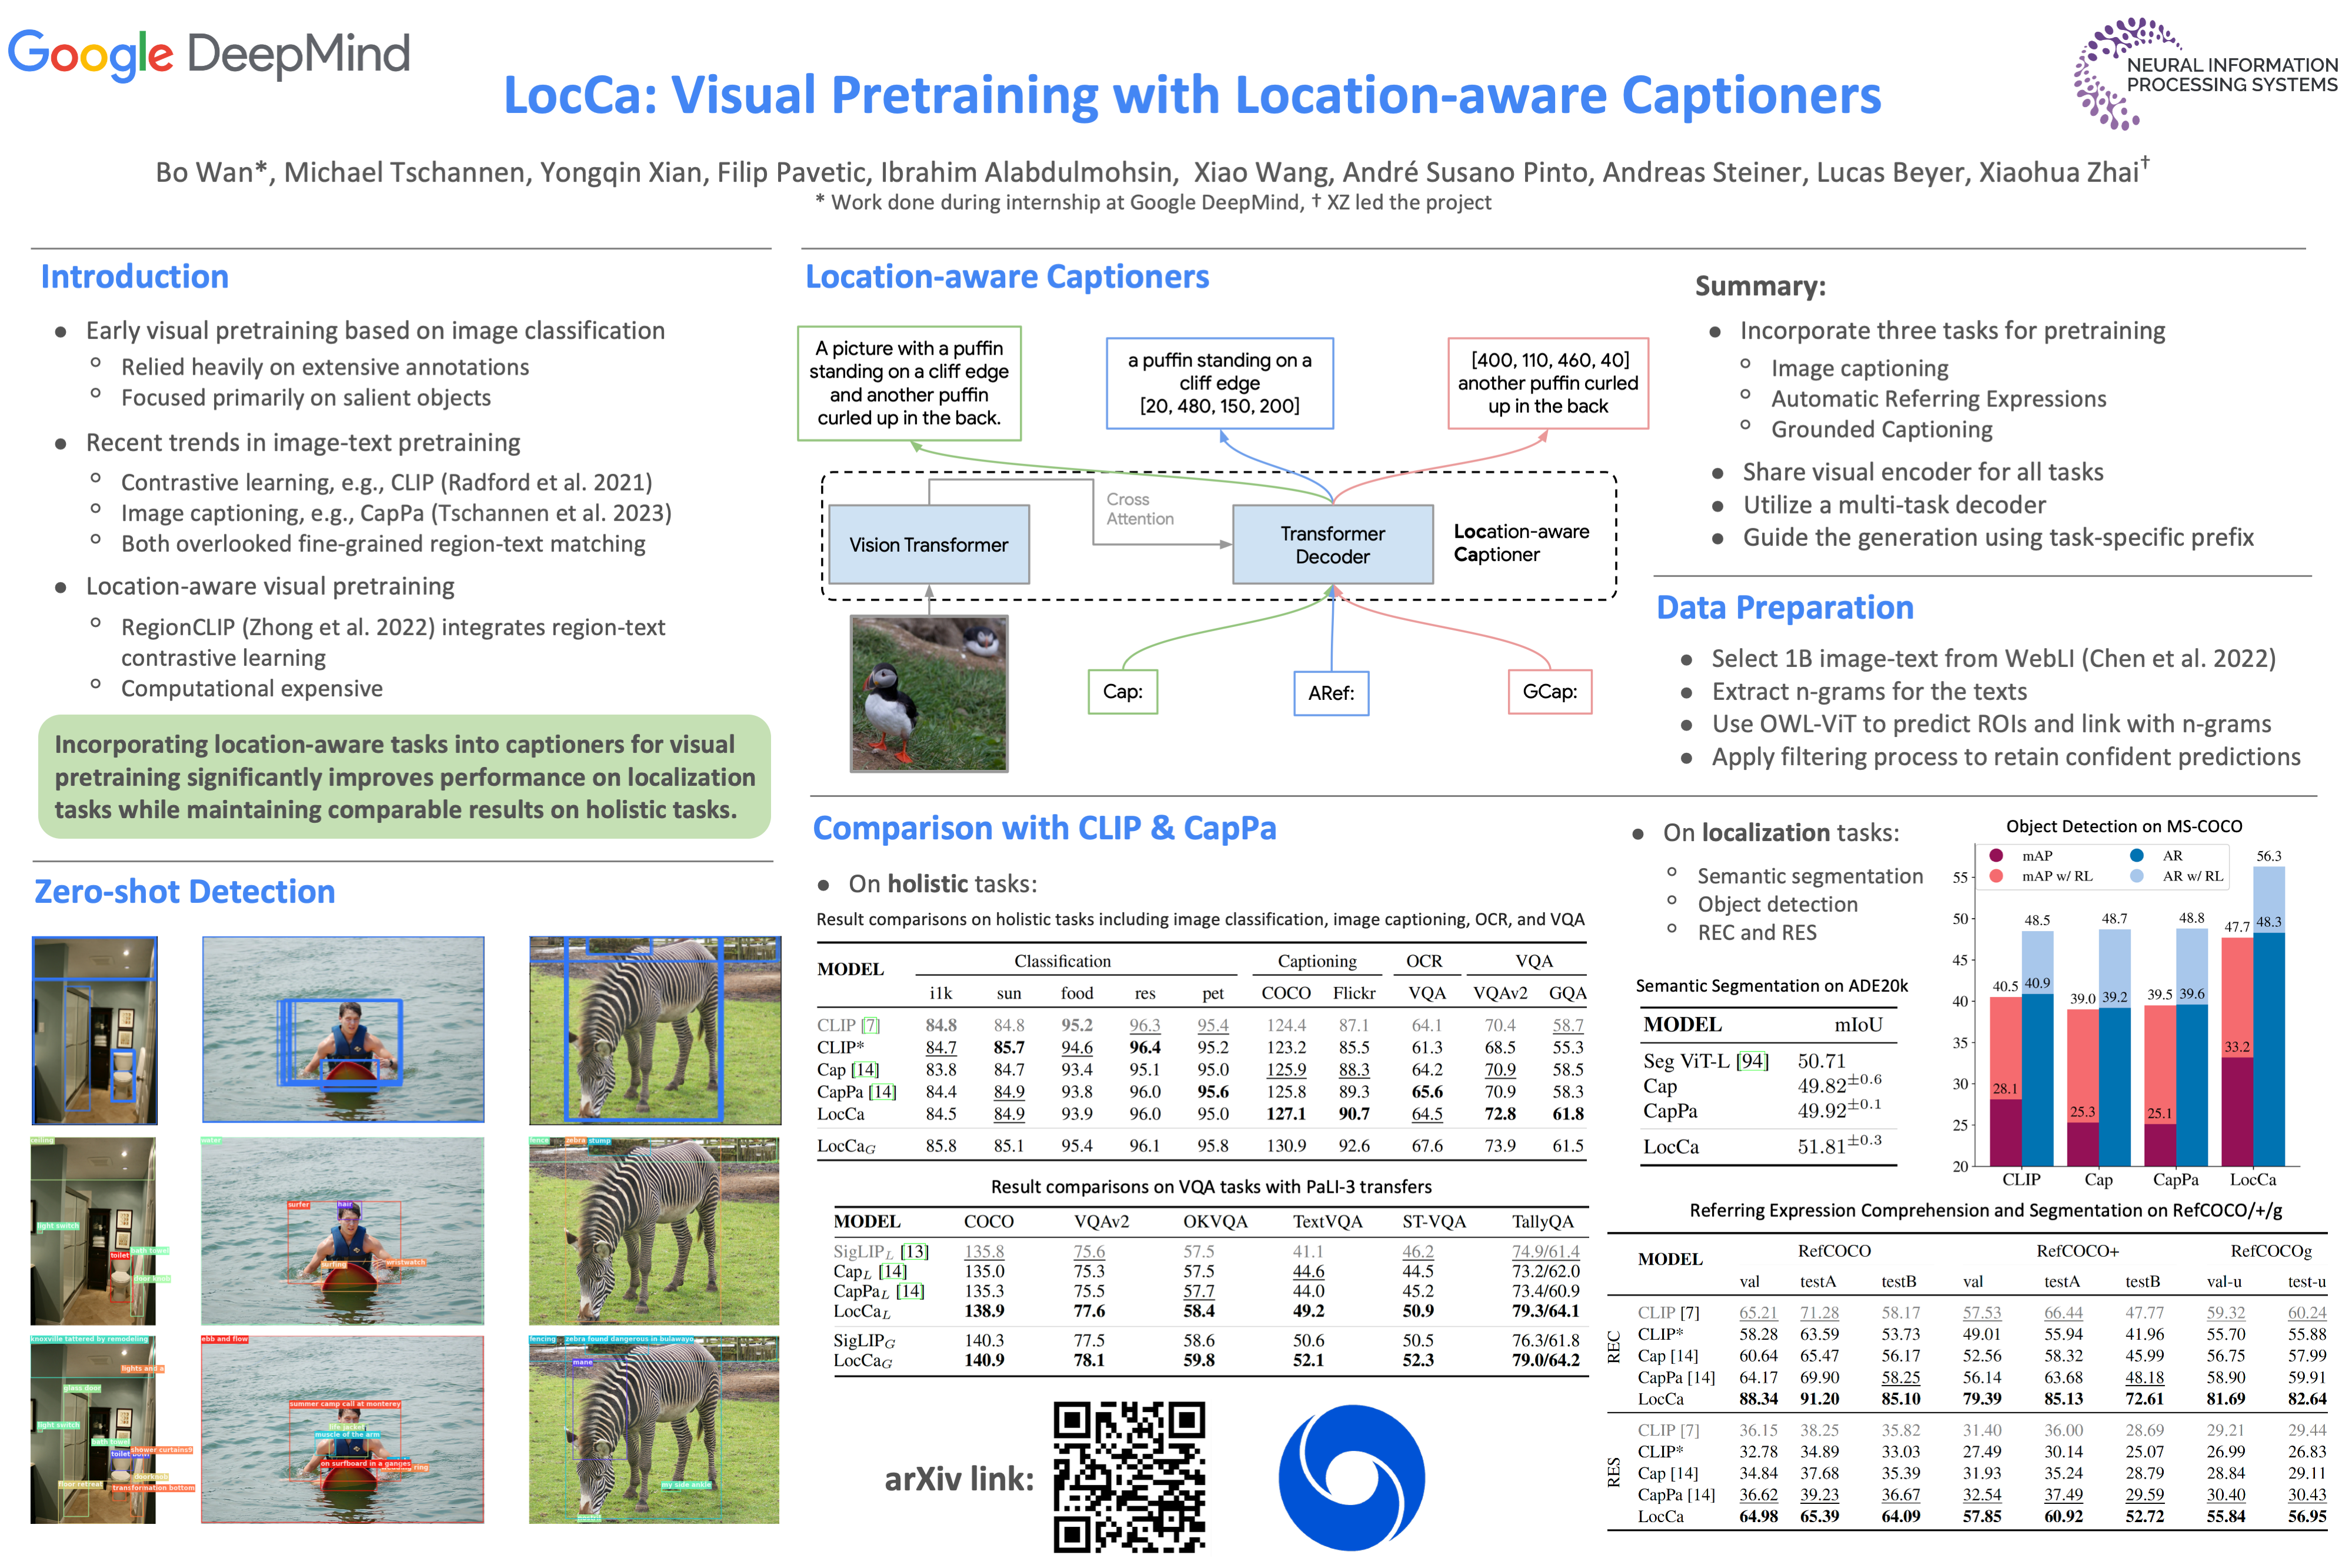
Image captioning was recently found to be an effective pretraining method similar to contrastive pretraining. This opens up the largely-unexplored potential of using natural language as a flexible and powerful interface for handling diverse pretraining tasks. In this paper, we demonstrate this with a novel visual pretraining paradigm, LocCa, that incorporates location-aware tasks into captioners to teach models to extract rich information from images. Specifically, LocCa employs two tasks, bounding box prediction and location-dependent captioning, conditioned on the image pixel input. Thanks to the multitask capabilities of an encoder-decoder architecture, we show that an image captioner can effortlessly handle multiple tasks during pretraining. LocCa significantly outperforms standard captioners on downstream localization tasks, achieving state-of-the-art results on RefCOCO/+/g, while maintaining comparable performance on holistic tasks. Our work paves the way for further exploration of natural language interfaces in visual pretraining.