
Session
Atlanta Poster Session 2
Hall C1
3D-PLOT-LLM: Part-Level Object Tokens for 3D Large Language Models
Jintang Xue ⋅ Xinyu Wang ⋅ Yixing Wu ⋅ Jingwen Chen ⋅ C.-C. J Kuo
3D multimodal large language models (3D MLLMs) describe a 3D object as a whole but cannot address, name, or reason about its parts. Prior part-aware attempts add segmentation decoders, heavier 3D encoders, or bounding-box grammars at substantial parameter cost. We take a fundamentally different path: we reorganize the input token stream so that parts become directly addressable through the LLM’s own vocabulary. Our model, 3D-PLOT-LLM, partitions the frozen point encoder’s patches into K locally coherent regions and inserts, before each region’s patch tokens, a learnable per-region marker and a reserved vocabulary token \; a Marker-Space Refinement (MSR) module then conditions each marker on its region’s spatial statistics and adjacency neighbors. The model thus cites parts in its output and follows prompts that refer to parts by token, a capability absent from prior object-level 3D MLLMs. To probe this interface, we construct PartVerse-QA, a vocabulary-level part-QA benchmark adapted from PartVerse mesh annotations (77K training pairs and 588 held-out queries on disjoint object splits), on which 3D-PLOT-LLM reaches caption-to-slots Jaccard 0.459 and Exact-match 13.78% (+64% relative over the strongest non-MSR variant), with a slot-to-caption GPT-4o judge of 44.68. On the 3DCoMPaT-GrIn part-aware grounded description benchmark, 3D-PLOT-LLM outperforms PointLLM, Kestrel, PARIS3D, and SegPoint on every text-output metric, and ShapeLLM on 3 of 4, with up to +3.03 GPT-4o judge over PointLLM. On Objaverse whole-object captioning, adding PartVerse-QA at Stage 2 yields +0.65 SBERT and +1.85 GPT-4o over PointLLM, and tops PointLLM-PiSA on 4 of 5 traditional metrics (SBERT, SimCSE, BLEU-1, METEOR) despite targeting a different (part-grounded) objective. All with under 1M new trainable parameters on a frozen point encoder, an order of magnitude below prior part-aware 3D MLLMs, and no segmentation decoder or bounding-box head.
AbFlowNet: Optimizing Antibody-Antigen Binding Energy via Diffusion-GFlowNet Fusion
Abrar Rahman Abir ⋅ Haz Sameen Shahgir ⋅ Rownok Z Ratul ⋅ Toki Tahmid ⋅ Greg Ver Steeg ⋅ Yue Dong
Complementarity Determining Regions (CDRs) are critical segments of an antibody that facilitate binding to specific antigens. Current computational methods for CDR design rely on reconstruction losses and do not jointly optimize binding energy, a crucial metric of antibody efficacy. Rather, binding energy optimization is performed via computationally expensive Online Reinforcement Learning (RL) pipelines that rely heavily on unreliable binding-energy estimators. In this paper, we propose AbFlowNet, a novel generative framework that integrates GFlowNet with Diffusion models. By framing each diffusion step as a state in the GFlowNet framework, AbFlowNet jointly optimizes standard diffusion losses and binding energy by directly incorporating energy signals into the training process, thereby unifying diffusion and reward optimization in a single procedure. Experimental results show that AbFlowNet outperforms the base diffusion model by 3.06% in amino acid recovery, 20.40% in geometric reconstruction (RMSD), and 3.60% in binding energy improvement ratio. ABFlowNet also decreases Top-1 total energy and binding energy errors by 24.8% and 38.1%, which is competitive with AbDPO's expensive online RL optimization without pseudo-labeling the test dataset or requiring computationally expensive synthetic CDR sampling.
We investigate data filtering for large model pretraining via new scaling studies that target the high compute, data-scarce regime. In spite of an apparently common belief that filtering data to include only high-quality information is essential, our experiments suggest that with enough compute, the best data filter is no data filter. We find that sufficiently trained large parameter models not only tolerate low-quality and distractor data, but in fact, including nominally 'poor' data improves model performance.
ACED-Bench: Evaluating How LLM Agents Acquire and Act on Causal Evidence
Yiwei Chen ⋅ Amila Weerasinghe ⋅ Siddharth Biswal ⋅ Utkrisht Rajkumar ⋅ Olcay Boz ⋅ Taylor Berg-Kirkpatrick ⋅ Rose Yu
Large language models are increasingly used as scientific assistants, yet we still lack reliable ways to evaluate whether they can investigate a system rather than merely answer a prompt. A useful evaluation must let agents choose experiments, interpret finite evidence, and make causal decisions, while keeping the environment coherent across repeated observations and interventions and preserving objective ground truth. We introduce ACED-BENCH (Active Causal Evidence and Decision Benchmark), a neuro-symbolic benchmark built around this requirement. The key idea is to separate the readable scientific surface from the formal causal world: LLMs generate natural-language scenarios and task text, while hidden probabilistic graphical models define the causal graph, data-generating process, intervention semantics, validation checks, and oracle answers. This yields scientific worlds that are natural for agents to investigate but exact enough for scalable, programmatic evaluation. The main leaderboard ACED-CORE contains 180 tasks: 60 set-valued causal ancestry/descendancy questions and 120 constrained causal-decision tasks. We also report ACED-QUAL, a 150-question yes/no qualification check using the same hidden-PGM interface. We evaluate seven contemporary LLMs and two earlier-generation models across three active agent designs. ACED-QUAL checks whether agents can use the interface to draw conclusions from evidence, while ACED-CORE tests whether they can decide what evidence to collect and when to commit to an answer. Evidence-ledger analysis localizes failures within the investigation: agents test the wrong intervention, lose relevant evidence, or continue after sufficient evidence has appeared. These results suggest that reliable AI co-scientists need explicit support for experiment design, evidence retention, answer commitment, and stopping.
A Constrained Bi-level Optimization Framework for Constrained Preference-Based Reinforcement Learning
Yue Mao ⋅ Siyuan Xu ⋅ Shicheng Liu ⋅ Minghui Zhu
This paper studies the problem of jointly learning a reward function, a cost function, and a policy from an expert's preferences. We formulate the problem as a constrained bi-level optimization problem, where the upper level infers the reward and cost functions from preferences, while the lower level optimizes a policy to best align with those preferences. To solve this problem, we propose a double-loop algorithm, Constrained Bi-level Optimization for Preference-Based Reinforcement Learning (CB-PbRL), which solves the lower-level optimization problem in the inner loop and the upper-level optimization problem in the outer loop. We establish a theoretical guarantee that CB-PbRL converges at a rate of $\mathcal{O}(1/\sqrt{K})$, and we demonstrate its effectiveness across multiple simulation environments.
Actionable Hallucination Detection: Translating Latent Uncertainty into Agentic Critique
Sanidhya Vijayvargiya ⋅ Rahul Lokesh
Large Language Models (LLMs) deployed as AI agents frequently exhibit a task-completion bias, executing hallucinated, undesired actions to force a resolution rather than expressing uncertainty. Existing detection methods fail to provide actionable, real-time correction as they either do not localize the hallucinations or incur prohibitive inference latency. We introduce the Latent Critic, a lightweight low-rank adapter (LoRA) that operates concurrently with a frozen base LLM's generation to actively restructure the transformer's residual stream---amplifying epistemic uncertainty signals and translating them into localized, natural language feedback within a single sequence. By refining the base model's native uncertainty signals, this manipulation of the latent space enables highly reliable, granular detection without the overhead of secondary inference loops. Mechanistic analysis via activation patching and layer-wise probing shows that this rank-invariant behavior restructures pre-existing uncertainty geometry into a linearly separable representation. Using tool-calling as an instantiation of granular hallucinations, we validate the detection and downstream improvements enabled by the Latent Critic architecture across Qwen and Llama-based models. Demonstrating superior real-time efficacy, our approach significantly outperforms equivalent-scale external detectors and internal probes in isolating hallucinations (0.870 vs. 0.695 F1), achieving >80% accuracy in localization (e.g., ungrounded: date). When deployed in a closed-loop ReAct environment, the Critic acts as a zero-latency guardrail, intercepting hallucinations before execution to prevent undesired actions while simultaneously enabling efficient agent self-correction.
Action Images: End-to-End Policy Learning via Multiview Video Generation
Haoyu Zhen ⋅ Zixian Gao ⋅ Qiao Sun ⋅ yilin zhao ⋅ Yuncong Yang ⋅ Yilun Du ⋅ Pengsheng Guo ⋅ Tsun-Hsuan Johnson Wang ⋅ Yi-Ling Qiao ⋅ Chuang Gan
World action models (WAMs) have emerged as a promising direction for robot policy learning, as they can leverage powerful video backbones to model the future states. However, existing approaches often rely on separate action modules, or use action representations that are not pixel-grounded, making it difficult to fully exploit the pretrained knowledge of video models and limiting transfer across viewpoints and environments. In this work, we present Action Images, a unified world action model that formulates policy learning as multiview video generation. Instead of encoding control as low-dimensional tokens, we translate 7-DoF robot actions into interpretable action images: multi-view action videos that are grounded in 2D pixels and explicitly track robot-arm motion. This pixel-grounded action representation allows the video backbone itself to act as a zero-shot policy, without a separate policy head or action module. Beyond control, the same unified model supports video-action joint generation, action-conditioned video generation, and action labeling under a shared representation. On RLBench and real-world evaluations, our model achieves the strongest zero-shot success rates and improves video–action joint generation quality over prior video-space world models, suggesting that interpretable action images are a promising route to policy learning.
Activation Functions Shape Token Synchronization in Stochastic Transformer Dynamics
Nikita Karagodin
We study how the MLP activation function shapes the long-time geometry of token representations in a deep transformer. We work in the stochastic transformer dynamics of [Agazzi et.al. 2026], in which tokens evolve as interacting particles on the sphere under deterministic attention and a common MLP noise whose covariance is the activation's NNGP kernel. For each of ReLU, ReLU², ReLU³, GELU, SiLU, and tanh, we identify the dimensions at which common noise stops driving tokens to full synchronization and sustains non-degenerate spread. We further prove that, even in the presence of attention, ReLU noise admits dispersion ceilings close to consensus, while ReLU$^2$ noise prevents complete token collapse under an explicit attention strength condition.
ActWorld: From Explorable to Interactive World Model via Action-Aware Memory
Zhexiao Xiong ⋅ Yizhi Song ⋅ Hao Kang ⋅ Qing Yan ⋅ Liming Jiang ⋅ Jenson Yang ⋅ ZHOUJIE FU ⋅ Stathi Fotiadis ⋅ Zichuan Liu ⋅ Bo Liu ⋅ Yiding Yang ⋅ Xin Lu ⋅ Nathan Jacobs
Interactive world models aim to simulate environment dynamics under real-time user actions. However, their action vocabulary is largely confined to navigation: most actions correspond to motion (e.g., walk, turn, look around), while interaction with objects in the scene (e.g., pick up plates, open doors, or trigger physical responses) is either absent, restricted to game domains, or relegated to prompt-to-full-video scenarios. The resulting worlds are visually explorable but not truly actionable. In this work, we present ActWorld, an interactive world model that extends prior navigation-centric generators to support mid-rollout object interaction within a chunk-autoregressive framework. We argue that the navigation--interaction gap stems from two bottlenecks. First, a data bottleneck: the lack of human--object interaction data with accurate, dense labels. Second, a memory bottleneck: recency-biased history compression in existing world models discards the event-transition frames that causally determine subsequent object states, leading to an action-forgetting pathology. On the data side, we construct a 100K interaction video dataset, each annotated with per-chunk captions via chain-of-thought reasoning. On the model side, we introduce a hierarchical action-aware memory design that routes history compression by interaction importance, complemented by a persistent memory bank that maintains event-update and object-identity tokens across long rollouts. Experiments show that ActWorld supports both flexible navigation and rich object interaction within a single model, substantially improving interaction fidelity over navigation-only baselines without sacrificing viewpoint control.
Long-context autoregressive reasoning in large language models is severely bottlenecked by key-value (KV) cache memory, making decoding-time compression essential. Existing methods typically rely on global or per-head token-wise selection. Under tight memory budgets and repeated compression events, however, these policies tend to over-focus on local attention spikes, causing Region Wipe-out: the severe depletion of contiguous spans of intermediate reasoning from the cache. This fragmentation disrupts reasoning, leading to Problem Drifting and Repetition Collapse. To address this, we propose Adaptive Mass-Segmented (AMS), a scorer-agnostic KV compression framework based on an "allocate-then-score" paradigm. By decoupling budget allocation from token scoring, AMS acts as a plug-in that shifts attention from a strictly micro-level retention metric to a macro-level spatial partitioning tool. Specifically, AMS derives an attention-based quality-mass distribution to partition each head's cache into adaptive segments, enforcing region-wise quotas with minimum-keep guarantees. Furthermore, an exponential moving average (EMA) credit mechanism makes this allocation history-aware, smoothing cache evolution across repeated recompressions. Experiments on MATH500, AIME24, AIME25, and GSM8K using 7B and 32B backbones show AMS improves pass@1 accuracy by up to 20.0 points over corresponding base scorers. AMS demonstrates generalization across diverse long-context workloads, including code completion, open-domain QA, and sparse retrieval. AMS seamlessly integrates with token-level scorers, consistently improves their performance, sometimes surpasses uncompressed full-KV decoding, and incurs negligible practical decoding-time overhead.
Adaptive Power Iteration Method for Differentially Private PCA
Ta Duy Nguyen ⋅ Alina Ene ⋅ Huy Nguyen
We study $\left(\epsilon,\delta\right)$-differentially private algorithms for the problem of approximately computing the top singular vector of a matrix $A\in\mathbb{R}^{n\times d}$ where each row of $A$ is a datapoint in $\mathbb{R}^{d}$. Following Dwork-Talwar-Thakurta-Zhang (STOC 2014), we consider the privacy model where neighboring inputs differ by one single row. We give a novel algorithm that achieves beyond-worst-case guarantees for input matrices with low coherence, which is a structural property of matrices in many applications, including but not limited to i.i.d. data. Our algorithm contributes to the extensive literature on private power iteration methods, where we introduce a new filtering technique which adapts to this coherence parameter. Our work departs from and complements the work by Hardt-Roth (STOC 2013) which achieves beyond-worst-case guarantees for the more restrictive privacy model where neighboring inputs differ in one single entry by at most 1.
AdERA: Adaptive Exponent Reuse for Lossless Allgather in Sharded MoE Training
Ali Zafar Sadiq ⋅ Haiying Shen ⋅ Masahiro Tanaka
In training Mixture-of-Experts models, sharded data parallelism splits each expert’s parameters across GPUs. Before each layer runs, GPUs must use Allgather to rebuild the full weight matrix. This communication can take a large part of each training iteration. Prior work reduces this cost with lossy compression, but lossy methods can affect accuracy. We propose Adaptive Exponent Reuse Allgather, or AdERA, a lossless Allgather compression method for sharded MoE training. Our key observation is that, after a short warmup phase, most weight exponents stay the same across iterations. AdERA stores these exponents locally and sends only the sign and mantissa when the exponent has not changed. The receiver then rebuilds the exact original weight by combining the cached exponent with the received sign and mantissa. Because parameter matrices have different shapes across layers, AdERA compresses only when compression saves time. It also overlaps compression with Allgather communication and computation. Our real experiments and large-scale trace-driven simulator show that, compared with the lossless baseline, AdERA achieves a 3.70× speedup on 16 GPUs and is projected to reach 4.28× on 128 GPUs, while preserving bitwise-exact parameter reconstruction. Compared with the lossy baseline, AdERA achieves a 3.93× speedup on 8 GPUs and is projected to reach 4.42× on 128 GPUs. The source code is publicly available.
A Doubly Smoothed Decentralized Stochastic Minimax Optimization Algorithm
Xinwen Zhang ⋅ Chiu C Tan ⋅ Haibin Ling ⋅ Hongchang Gao
Decentralized stochastic minimax optimization has recently attracted significant attention due to its applications in machine learning. However, existing state-of-the-art methods use learning rates of different scales for the primal and dual variables, making them difficult to tune in practice. To address this problem, this paper proposes a novel doubly smoothed decentralized stochastic minimax algorithm. Specifically, in terms of algorithm design, we update both the primal and dual variables using smoothed gradients and introduce novel approaches to handle the computation and communication of the auxiliary variables introduced by the smoothing technique. On the theoretical side, for nonconvex-PL problems, our convergence analysis reveals that the learning rates for the primal and dual variables are of the same scale. Moreover, the order of the condition number in our convergence rate is improved to $O(\kappa^{3/2})$. To the best of our knowledge, this is the first time it has been improved to such a favorable order. Finally, extensive experimental results validate the effectiveness of our algorithm.
AdpSplit: Error-Driven Adaptive Splitting for Faster Geometry Discovery in 3D Gaussian Splatting
Yongjae Lee ⋅ Jingxing Li ⋅ Abhay Yadav ⋅ Rama Chellappa ⋅ Deliang Fan
Adaptive density control in 3D Gaussian Splatting (3DGS) repeatedly grows the Gaussian population through fixed-cardinality random splitting to discover useful scene structure. However, in vanilla 3DGS, its binary split operator requires many densification rounds to expose fine details, making it a bottleneck for efficient training schedules with fewer iterations. We introduce AdpSplit, an error-driven adaptive split operator that determines the number of split children and initializes the child parameters from L1-pixel-error region statistics, enabling fewer densification iterations, thus reduced training time, while preserving the rendering quality of full-schedule training. Across the MipNeRF360, Deep-Blending, and Tanks\&Temples datasets, AdpSplit reduces the training time of multiple accelerated 3DGS pipelines by 9.2\%-22.3\% as a simple drop-in replacement for the standard split operator. With FastGS, AdpSplit matches the full-schedule PSNR on MipNeRF360 while reducing training time by 16.4\%, corresponding to a 12.6$\times$ acceleration over vanilla 3DGS.
Agentic Video Editing from Underspecified Requests
Yongsheng Yu ⋅ Ziyun Zeng ⋅ Zhiyuan Xiao ⋅ Zhenghong Zhou ⋅ Hang Hua ⋅ Wei Xiong ⋅ Jiebo Luo
Recent video editing models have converged on a unified-conditioning design: a single diffusion transformer reads text, source video, reference images, and masks through one token sequence, and one set of weights covers replacement, removal, style transfer, and reference-driven insertion. The design is flexible, but it assumes that the user already provides model-ready text, identity references, and spatial targets, which real requests often omit. We present Aurora, an agentic video editing framework that pairs a tool-augmented vision-language models (VLMs) agent with a unified video diffusion transformer. The agent maps a raw user request to a structured edit plan aligned with the transformer's conditioning channels, thereby resolving textual and visual underspecification before generation. We train the agent with supervised data for executable edit planning and reference-image selection, together with preference pairs for robust tool use and instruction refinement. Moreover, we introduce AgentEdit-Bench to evaluate agent-enhanced video editing under textual and visual underspecification. Experiments on EditVerse-Bench, OpenVE-Bench, and AgentEdit-Bench show that Aurora improves over text-only baselines and its agentic capability transfers to compatible frozen video editing models. Code, data, and models will be released.
Agent-ToM: Learning to Monitor Autonomous LLM Agents via Theory-of-Mind Reasoning
Nesreen Ahmed ⋅ Nima Nafisi
Monitoring autonomous large language model (LLM) agents for covert malicious behavior (e.g., covertly pursuing a hidden malicious objective) is challenging due to delayed, context-dependent, and long-horizon attack patterns. In adversarial settings such as sabotage, agents may pursue hidden objectives while maintaining superficially benign behavior, making detection difficult even with full trajectory access. Prior monitoring approaches primarily improve monitor scaffolding or ensemble aggregation, but treat each trajectory independently and do not improve from prior monitoring experience. Moreover, standard reasoning methods explain observed behavior but do not explicitly reason about agent beliefs, intentions, and goal alignment required to distinguish benign task execution from covert deviation. We propose Agent-ToM, a learning-to-monitor framework grounded in Theory-of-Mind (ToM) reasoning for security analysis of autonomous agents. Agent-ToM performs structured full-trajectory analysis by inferring beliefs, step-level intent hypotheses with calibrated confidence, expected actions, and deviations from task-consistent behavioral baselines. At inference time, it employs a Reason--Verify--Refine pipeline to construct and validate monitoring decisions. At training time, Agent-ToM learns from prior monitoring episodes by distilling critique signals into a persistent semantic guardrail memory that accumulates monitoring strategies, enabling reusable belief- and intent-conditioned constraints to be applied across episodes. We evaluate Agent-ToM on adversarial agent monitoring benchmarks (SHADE-Arena and CUA-SHADE-Arena). Agent-ToM achieves strong precision--recall balance and outperforms state-of-the-art monitoring baselines, including ensemble methods, while using a single coherent reasoning pipeline. These results demonstrate that \emph{learning at the monitoring layer}, combined with structured ToM reasoning and verification, provides an effective and deployable foundation for securing autonomous LLM agents.
AI Safety Evaluations Need More Human-AI Experiments
Michelle Vaccaro ⋅ Jaeyoon Song ⋅ Abdullah Almaatouq ⋅ Michiel Bakker
Current frontier AI safety evaluations emphasize static benchmarks, third-party annotations, and red-teaming. In this position paper, we argue that AI safety research should focus on human-centered evaluations that measure harmful capability uplift: the marginal increase in a user's ability to cause harm with a frontier model beyond what conventional tools already enable. We frame harmful capability uplift as a core AI safety metric, ground it in prior social science research, and provide concrete methodological guidance for systematic measurement. We conclude with actionable steps for developers, researchers, funders, and regulators to make harmful capability uplift evaluation a standard practice.
Almost Sure Convergence of Linear Temporal Difference Learning with Arbitrary Features
Jiuqi Wang ⋅ Shangtong Zhang
Temporal difference (TD) learning with linear function approximation (linear TD) is a classic and powerful prediction algorithm in reinforcement learning. While it is well-understood that linear TD converges almost surely to a unique point, this convergence traditionally requires the assumption that the features used by the approximator are linearly independent. However, this linear independence assumption does not hold in many practical scenarios. This work is the first to establish the almost sure convergence of linear TD without requiring linearly independent features. We prove that the weight iterates of linear TD converge to a bounded set, and that the value estimates derived from the weights in that set are the same almost everywhere. We also establish a notion of local stability of the weight iterates. Importantly, we do not impose assumptions tailored to feature dependence and do not modify the linear TD algorithm. Key to our analysis is a novel characterization of bounded invariant sets of the mean ODE of linear TD.
Almost Sure Convergence Rates of Stochastic Approximation and Reinforcement Learning via a Poisson-Moreau Drift
Xinyu Liu ⋅ Zixuan Xie ⋅ Shangtong Zhang
Establishing almost sure convergence rates for stochastic approximation and reinforcement learning under Markovian noise is a fundamental theoretical challenge. We make progress towards this challenge for a class of stochastic approximation algorithms whose expected updates are contractive, a setting that arises in many reinforcement learning algorithms such as $Q$-learning and linear temporal difference learning. Specifically, for a power-law learning rate $\mathcal{O}(n^{-\eta})$ with $\eta \in (1/2, 1)$, we obtain an almost sure convergence rate arbitrarily close to $o(n^{1 - 2\eta})$. For a harmonic learning rate $\mathcal{O}(n^{-1})$, we obtain an almost sure convergence rate arbitrarily close to $o(n^{-1})$, which we argue is a strong result because it is close to the optimal rate $\mathcal{O}(n^{-1}\log\log n)$ given by the law of the iterated logarithm (for a special case of i.i.d. noise). Key to our analysis is a novel Lyapunov drift construction that applies a Poisson-equation based correction for Markovian noise to the well-established Moreau-envelope smoothing for the contractive mapping.
A Margin Perspective on LoRA: Robustness to Catastrophic Forgetting and Adapter Merging (MaLoRA)
Ziqing Xu ⋅ Hancheng Min ⋅ Lachlan MacDonald ⋅ Salma Tarmoun ⋅ Enrique Mallada ⋅ Weijie Su ⋅ Rene Vidal
Low-rank adaptation (LoRA) is the de facto method for parameter-efficient fine-tuning of large neural networks, achieving strong task adaptation with minimal trainable parameters and low optimization cost. Beyond this efficiency, practitioners have observed two striking properties: *robustness to catastrophic forgetting* and the ability to *merge independently trained adapters* into a single model that performs competitively across multiple tasks. These properties are central to continual and multi-task learning, yet remain poorly understood. In this work, we provide a theoretical explanation through a unified *margin-based perspective*. We analyze LoRA in multiclass linear classification under a near-orthogonal task regime with $l_2$-regularization, and characterize the optimal LoRA adapter across regularization regimes. Our analysis shows that, in an intermediate regime of regularization parameters, the optimal adapter aligns with the *max-margin solution* on the fine-tuning data. Building on this characterization, we derive two key consequences. First, we obtain closed-form expressions for the margins on pre-training and fine-tuning data, revealing a precise margin trade-off: the regularization parameter controls the balance between retention and adaptation. Second, we analyze adapter merging, proving that merged models achieve positive margin on each task and deriving optimal mixing coefficients that balance margins across tasks and maximize the margin over their union. These results lead to a simple, training-free merging rule, which we term *margin-based LoRA merging* (MaLoRA). Experiments on modern architectures and real datasets validate our theoretical predictions, showing that MaLoRA matches or outperforms several adapter-merging baselines across a range of vision and language classification tasks.
AME-TS: Anchored Mixture-of-Experts for Time Series Forecasting
Rui Wang ⋅ Renhao Xue ⋅ Ray Razi ⋅ Huan Song ⋅ Hannah Marlowe
Time series forecasting models are increasingly scaled through large Transformer backbones, yet most existing approaches process all series through a shared dense computation path despite substantial heterogeneity in temporal structure. Mixture-of-Experts (MoE) offers a natural alternative by enabling conditional computation, but standard MoE routing leaves expert specialization weakly identified and often unstable during downstream adaptation. We propose AME-TS, a structure-guided sparse time series foundation model that aligns expert routing with interpretable temporal structure. AME-TS first uses a lightweight regime predictor to estimate series-level descriptors, including forecastability, seasonality, trend, and sparsity, and maps them to a soft structural prior over experts. This series-level prior guides token-level routing during training, encouraging structure-aligned specialization. On the GIFT-Eval benchmark, AME-TS delivers a strong accuracy-efficiency tradeoff across model scales: it substantially outperforms existing time series foundation models at small model scales and remains competitive with the strongest models at larger scales, while activating substantially fewer parameters through sparse routing. We further show that AME-TS learns more interpretable routing geometry and substantially more stable expert specialization than standard MoE during fine-tuning on the M5 dataset. These results suggest that structure-aware routing is an effective and reliable way to realize the benefits of sparse expert models for time series forecasting.
AMPS: Adaptive Modality Preference Steering via Functional Entropy
Zihan Huang ⋅ Xintong Li ⋅ Rohan Surana ⋅ Tong Yu ⋅ Rui Wang ⋅ Julian McAuley ⋅ Jingbo Shang ⋅ Junda Wu
Multimodal Large Language Models (MLLMs) often exhibit significant modality preference, which is a tendency to favor one modality over another. Depending on the input, they may over-rely on linguistic priors relative to visual evidence, or conversely over-attend to visually salient cues over textual facts. Prior work has applied a uniform steering intensity to adjust the modality preference of MLLMs. However, strong steering can impair standard inference and increase error rates, whereas weak steering is often ineffective. Since steering sensitivity varies substantially across instances, a single global strength is difficult to calibrate. To address this, we introduce an instance-aware diagnostic metric Modality Contribution Ratio (MCR) that quantifies each modality’s information contribution and reveals sample-specific susceptibility to steering. Building on this signal, we propose a scaling strategy and a learnable module for instance-aware control of modality preference. Experiments show that AMPS outperforms conventional steering on $MC^2$ by improving preference control with lower generation collapse, and improves MLLM performance on general multimodal QA dataset such as MM-Vet v2.
Analytical Correction for Subsampling Bias in Drifting Models
Jiaru Zhang ⋅ Zeyun Deng ⋅ Juanwu Lu ⋅ Ziran Wang ⋅ Ruqi Zhang
Drifting models are capable one-step generative models trained to follow a drifting field. The field combines attractive and repulsive softmax-weighted centroids over the data and current-generator distributions. In practice, only a minibatch of $n$ samples from each distribution is available, and each centroid is approximated by an empirical estimate. In this paper, we begin by showing that the minibatch centroid is in general a *biased* estimator of the target centroid, with a pointwise $O(1/n)$ bias arising from softmax self-normalization. Correcting this bias requires the expectation over the full distribution, which is intractable. We instead approximate the leading bias term from in-batch statistics and propose *Analytical Bias Correction* (ABC), a closed-form plug-in adjustment. We prove that ABC reduces the bias from $O(1/n)$ to $O(1/n^2)$, introduces no first-order variance inflation, and preserves convex-hull containment of the corrected centroid. In practice, ABC requires only two additional lines of code and has negligible wall-time overhead under compiled execution. Toy experiments confirm the theoretical $O(1/n)$ and $O(1/n^2)$ scaling. On CIFAR-10, ABC reduces FID and trains faster, with the largest gains at small $n$, where the bias is most significant.
Quantum reinforcement learning (QRL) has emerged as a promising approach for controlling quantum systems and accelerating learning tasks with quantum resources. However, most existing QRL formulations still retain a classical reinforcement learning interface: states and actions are often encoded in computational bases and rewards are extracted through measurement. This is less natural for fully quantum environments in which the relevant state information may live in an unknown basis and intermediate measurements can disturb the trajectory. This motivates a fully QRL framework in which the agent, environment, rewards, and return accumulation are all represented quantum mechanically. In this paper, we take a step toward this goal and introduce a new QRL framework in which state, action, reward, and reward-accumulation registers evolve without intermediate measurement. In this framework, both the policy and the environment are modeled by conditional quantum channels: the policy updates the action register conditioned on the state, while the environment updates the state and reward registers conditioned on the action, without measuring or overwriting the corresponding control register. We then propose a quantum policy-gradient algorithm for parameterized conditional quantum channels with a trainable control basis. We also derive finite- and infinite-horizon gradient estimators using a new parameter-shift rule. The algorithm samples a single shifted policy block from a geometric distribution, yielding an unbiased gradient estimator under bounded rewards. Finally, we establish convergence of the resulting stochastic gradient-ascent procedure to stationary points under standard smoothness and step-size assumptions.
A Semantic-Sampling Framework for Evaluating Calibration in Open-Ended Question Answering
Zhanliang Wang ⋅ Jiancong Xiao ⋅ Ruochen Jin ⋅ Shu Yang ⋅ Bojian Hou ⋅ Li Shen
Calibration measures whether a model's predicted confidence aligns with its empirical accuracy, and is central to the reliable deployment of large language models (LLMs) in high-stakes domains such as medicine and law. While much recent work focuses on improving LLM calibration, the equally important question of how to evaluate it in realistic settings remains underdeveloped. Open-ended question answering (QA), the most common deployment setting for modern LLMs, is where existing evaluation methods fall short: logit-based metrics need restricted output formats and internal probabilities; verbalized confidence is self-reported and often overconfident; and sampling-based methods rely on task-specific extraction rules without a clear finite-sample target. We introduce Sem-ECE (Semantic-Sampling Expected Calibration Error), a calibration evaluation framework for open-ended QA that samples answers from the model, groups them into semantic classes, and uses the resulting frequencies as confidence. We study two estimators within this framework: Sem₁-ECE, the same-sample self-consistency score, and Sem₂-ECE, a held-out variant that separates answer selection from confidence evaluation. We prove both are asymptotically unbiased, and further show that they agree on easy questions but diverge on hard ones with Sem₂ achieving strictly smaller calibration error, so their gap also serves as a diagnostic for question difficulty. Experiments on three open-ended QA benchmarks across five leading commercial LLMs match our theoretical predictions and show that Sem-ECE outperforms verbalized confidence and existing sampling-based methods, while complementing logit-based evaluation when internal probabilities are unavailable.
A simple model of co-emergence of grid and place fields
Zhaoze Wang ⋅ Genela Morris ⋅ Dori Derdikman ⋅ Pratik Chaudhari ⋅ Vijay Balasubramanian
Grid cells in the medial entorhinal cortex and place cells in the hippocampus together support spatial navigation. The two regions are reciprocally connected, and there is a chicken-and-egg problem for how both arise and reinforce each other during development. Current computational accounts either derive one type from the other or use network dynamics to model the emergence of one type in isolation. We introduce a unified recurrent network model that instantiates Dale's Law (every neuron is either excitatory or inhibitory), and is trained to predict the next sensory observation from masked previous sensory observations and egocentric motion. To our knowledge, this is the first single-objective model in which grid and place cells co-emerge without supervision of either type, or reliance on pre-existing spatial-cell representations. The two kinds of spatial codes coexist across 1,000 different training configurations, with their balance set by the amount of sensory noise and masking. Without retraining, the network qualitatively reproduces experimentally observed grid fragmentation in hairpin mazes, grid merging after wall removal, lattice alignment across connected rooms, locally ordered 3D fields observed in freely flying bats, as well as the developmental order in which place cells precede grid cells. We interpret these results in terms of two complementary encoding pressures within a single sensory-prediction objective: (1) correcting errors or reconstructing missing components of sensory observations, and (2) prediction of the next sensory state during navigation. Our results suggest a circuit-level account of the co-emergence of grid and place cells, and experimentally testable predictions for the two kinds of spatial codes.
A Single Neuron Is Sufficient to Bypass Safety Alignment in Large Language Models
Hamid Kazemi ⋅ Atoosa Malemir Chegini ⋅ Maria Safi
Safety alignment in language models operates through two mechanistically distinct systems: refusal neurons that gate whether harmful knowledge is expressed, and concept neurons that encode the harmful knowledge itself. By targeting a single neuron in each system, we demonstrate both directions of failure --- bypassing safety on explicit harmful requests via suppression, and inducing harmful content from innocent prompts via amplification --- across seven models spanning two families and 1.7B to 70B parameters, without any training or prompt engineering. Our findings suggest that safety alignment is not robustly distributed across model weights but is mediated by individual neurons that are each causally sufficient to gate refusal behavior --- suppressing any refusal neuron bypasses safety alignment across diverse harmful requests.
A Theory on Flow Matching with Neural Networks
Yihan He ⋅ Qishuo Yin ⋅ Yuan Cao ⋅ Jianqing Fan ⋅ Han Liu
In this work, we develop theoretical foundation for flow matching with neural-network–parameterized conditional velocity fields. We establish convergence guarantees for gradient descent in the over-parameterized 2-layered ReLU neural network regime. We derive generalization bounds for the conditional velocity-field matching objective. Building on these results, we provide Wasserstein-distance guarantees for the samples generated by the induced flow. Our analysis is based on generalization bound for multi-task representation learning with unbounded losses, which may be of independent interest beyond flow-based generative modeling. These theoretical results are validated through extensive experiments on both synthetic and real-world image benchmarks.
Recent direct-sum hardness results show that computing multi-head attention by evaluating each head independently is essentially optimal under standard complexity assumptions, but leave open whether the key-value sharing in modern MQA and GQA architectures can circumvent this barrier. We prove that it cannot: even one-layer MQA with a single shared key-value head requires one full quadratic routing computation per query head in the worst case. To quantify how far practice departs from this worst case, we develop a calibration-stacked spectral framework that measures the effective number of independent routing-message directions in a layer, carefully separating signed, stochastic, and softmax-realizable compression; we also prove tight error-compounding bounds and NP-hardness of the natural route-merging compiler problem. Empirically, across fourteen open-weight GQA checkpoints from four model families (0.6B-70B parameters), eight shared routes capture over 90% of the routing-message energy in every model, and larger models use a progressively smaller fraction of their theoretical routing capacity, revealing a substantial and widening gap between worst-case hardness and the redundancy present in deployed transformers.
Attribute-Efficient Learning of Sparse Halfspaces with Constant Malicious Noise Rate
Shiwei Zeng ⋅ Jie Shen
Attribute-efficient PAC learning of sparse halfspaces has been a fundamental problem in machine learning theory. In recent years, machine learning algorithms are faced with prevalent data corruptions or even malicious attacks. It is of central interest to design computationally-efficient algorithms that are robust to malicious corruptions. In this paper, we consider that there exists a constant amount of malicious noise in the data and show that it is possible to learn an underlying $s$-sparse halfspace $w^* \in \mathbb{R}^d$ with $O(s^2\log^5 d)$ samples. Specifically, we follow a recent line of works and assume that the underlying distribution satisfies a certain concentration condition and a margin condition at the same time. As a complementary result, we provide an information-theoretic sample lower bound under such conditions. Strong evidence shows that our sample complexity is nearly optimal. To show the robustness of our algorithm, we provide a new gradient analysis that carefully handles the sparsity admitted constraints in hinge loss minimization program, which could be of independent interest.
Augmented Lagrangian Method for Last-Iterate Convergence for Constrained MDPs
Michael Lu ⋅ Max Lin ⋅ Mo Chen ⋅ Sharan Vaswani
We study policy optimization for infinite-horizon, discounted constrained Markov decision processes (CMDPs). While existing theoretical guarantees typically hold for the mixture policy, deploying such a policy is computationally and memory intensive. This leads to a practical mismatch where a single (last-iterate) policy must be deployed. Recent theoretical works have thus focused on proving last-iterate convergence, but are largely limited to the tabular setting or to algorithmic variants that are rarely used in practice. To address this, we use the classic inexact augmented Lagrangian ($\texttt{AL}$) method from constrained optimization, and propose a general framework with provable last-iterate convergence for CMDPs. We first focus on the tabular setting and propose to solve the $\texttt{AL}$ sub-problem with projected Q-ascent ($\texttt{PQA}$). Combining the theoretical guarantees of $\texttt{PQA}$ and the standard $\texttt{AL}$ analysis enables us to establish global last-iterate convergence. We generalize these results to handle log-linear policies, and demonstrate that an efficient, projected variant of $\texttt{PQA}$ can achieve last-iterate convergence with comparable guarantees as prior work. Finally, we demonstrate that our framework scales to complex non-linear policies, and evaluate it on continuous control tasks.
Automating ML for Science: Can Frontier Agents Climb Scientific Hills in the Wild?
Ming Zhong ⋅ Stacy Li ⋅ Nicholas Carlini ⋅ Matthew Jagielski
Frontier coding agents are increasingly framed as end-to-end automated scientific researchers, with the promise of accelerating discovery on open-ended problems that lie beyond routine ML pipelines. We introduce Agent4Sci, a long-horizon testbed for measuring how close today's agents are to that vision, spanning 20 scientific benchmarks across 11 domains. Rather than ranking agents on a leaderboard, Agent4Sci asks what kinds of scientific work agents can automate under in-the-wild conditions, and where they still fall short. Empirically, today's frontier agents advance the published best on every benchmark, with Claude Opus reaching 10.4\% mean relative improvement and no run flagged for academic misconduct. These gains, however, come almost entirely from a bag of ML-engineering tricks rather than research-level insight. Trajectory analysis surfaces three recurring limitations in this setting: novelty miscalibration, resource under-utilization, and rapid collapse into local engineering sweeps. Lightweight plug-in skills for research ideation, experiment management, and scheduled checklists raise Claude Opus from 10.4\% to 20.1\% and Codex from 4.4\% to 8.1\%, while yielding more diverse, domain-relevant interventions. The gap to scientific research remains open. Overall, Agent4Sci gives the community a way to track and push frontier agents toward an automated researcher that proposes insights and drives measurable progress on real-world scientific problems.
AVO: Agentic Variation Operators for Autonomous Evolutionary Search
Terry Chen ⋅ Zhifan Ye ⋅ Bing Xu ⋅ Zihao Ye ⋅ Timmy Liu ⋅ Ali Hassani ⋅ Tianqi Chen ⋅ Andrew Kerr ⋅ Haicheng Wu ⋅ Vedaanta Agarwalla ⋅ Fengzhe Zhou ⋅ Shangda Li ⋅ Yang Xu ⋅ Yu-Jung Chen ⋅ Hanfeng Chen ⋅ Aditya Kane ⋅ Ronny Krashinsky ⋅ Ming-Yu Liu ⋅ Vinod Grover ⋅ Luis Ceze ⋅ Roger Bringmann ⋅ John Tran ⋅ Wei Liu ⋅ Feng Xie ⋅ Michael Lightstone ⋅ Humphrey Shi
Agentic Variation Operators (AVO) are a new family of evolutionary variation operators that replace the fixed mutation, crossover, and hand-designed heuristics of classical evolutionary search with autonomous coding agents. Rather than confining a language model to candidate generation within a prescribed pipeline, AVO instantiates variation as a self-directed agent loop that can consult the current lineage, a domain-specific knowledge base, and execution feedback to propose, repair, critique, and verify implementation edits. We evaluate AVO on attention, among the most aggressively optimized kernel targets in AI, on NVIDIA Blackwell (B200) GPUs. Over 7 days of continuous autonomous evolution on multi-head attention, AVO discovers kernels that outperform cuDNN by up to 3.5% and FlashAttention-4 by up to 10.5% across the evaluated configurations. The discovered optimizations transfer readily to grouped-query attention, requiring only 30 minutes of additional autonomous adaptation and yielding gains of up to 7.0% over cuDNN and 9.3% over FlashAttention-4. Together, these results show that agentic variation operators move beyond prior LLM-in-the-loop evolutionary pipelines by elevating the agent from candidate generator to variation operator, and can discover performance-critical micro-architectural optimizations that produce kernels surpassing state-of-the-art expert-engineered attention implementations on today’s most advanced GPU hardware.
Beyond Bounded Variance: Variance-Reduced Normalized Methods for Nonconvex Optimization under Blum-Gladyshev Noise
Antesh Upadhyay ⋅ Arda Fazla ⋅ Abolfazl Hashemi
We study nonconvex stochastic optimization under the Blum-Gladyshev ($\mathsf{BG}$-0) noise model, where the stochastic gradient variance grows quadratically with the distance from the initialization. We consider this problem under both standard smoothness and the symmetric generalized-smoothness framework, which captures objectives whose local curvature can scale with the gradient norm. We prove that normalized stochastic gradient descent with momentum, using only one stochastic gradient per iteration, converges under $\mathsf{BG}$-0 noise with oracle complexity $\mathcal{O}(\varepsilon^{-6})$. This rate holds both for standard smoothness and for $\alpha$-symmetric generalized smoothness, showing that generalized smoothness is rate-neutral for normalized momentum in this setting. We then study a variance-reduced normalized STORM method. Under mean-square smoothness and sharp initialization, the method achieves the minimax optimal $\mathcal{O}(\varepsilon^{-4})$ complexity, matching the lower bound. Under expected $\alpha$-symmetric generalized smoothness, the STORM recursion couples gradient-dependent smoothness with distance-dependent noise, leading to complexity $\mathcal{O}(\varepsilon^{-(4+\alpha)})$ for $\alpha \in (0,1)$ and $\mathcal{O}(\varepsilon^{-5})$ for $\alpha=1$. When the distance-growth parameter in the noise model vanishes, our guarantees recover the standard bounded-variance rates: $\mathcal{O}(\varepsilon^{-4})$ for momentum, $\mathcal{O}(\varepsilon^{-3})$ for variance reduction, and $\mathcal{O}(\varepsilon^{-2})$ in the deterministic case. To our knowledge, these are the first convergence guarantees for normalized methods in non-convex stochastic optimization under $\mathsf{BG}$-0 noise without bounded domains, increasing batch sizes, or explicit anchoring, covering both standard and generalized smoothness regimes.
Beyond Empirical Support: Structured Outlier Generation via Sinkhorn Optimal Transport
Haixiang Sun ⋅ Andrew Liu
Outliers are essential for evaluating and improving the robustness of machine learning systems, especially when future distributions may differ significantly from historical training data. In high-stakes applications, robustness often depends on rare cases that finite datasets fail to capture, making simple resampling or perturbation insufficient for stress scenario generation. Existing outlier synthesis methods typically rely on sparse neighborhoods, low support latent regions, or classifier boundary crossings, which can be heuristic, unstable, and tied to specific modalities or architectures. We therefore propose Sinkhorn Boundary Outlier Generation (SBOG), a structured framework for latent-space outlier generation that couples Sinkhorn optimal transport geometry with distributionally robust boundary modeling. The resulting Sinkhorn-induced support cost guides the sampler toward weakly supported boundary regions, while semantic constraints prevent uncontrolled drift from the intended context, yielding controlled deviations from the in-distribution reference measure rather than arbitrary sparse-region samples. Experiments on time series anomaly generation and image outlier synthesis show that our framework produces informative, semantically controlled outliers and improves downstream robustness evaluation across modalities, providing a foundation for stress scenario generation beyond empirical support.
Beyond Pairs: Your Language Model is Secretly Optimizing a Preference Graph
Ning Liu ⋅ Chuanneng Sun ⋅ Kristina L Klinkner ⋅ Shervin Malmasi
Direct Preference Optimization (DPO) aligns language models using pairwise preference comparisons, offering a simple and effective alternative to Reinforcement Learning (RL) from human feedback. However, in many practical settings, training data consists of multiple rollouts per prompt, inducing rich preference structure that pairwise DPO fails to exploit. Collapsing such data into independent pairs discards transitivity, introduces redundant or conflicting supervision, and can lead to unstable optimization. We propose Graph Direct Preference Optimization (GraphDPO), a principled generalization of DPO that operates over directed acyclic preference graphs induced by rollout rankings. GraphDPO encodes dominance relations as edges and optimizes a graph-structured Plackett--Luce-inspired objective that aggregates supervision over graph neighborhoods, enforcing transitivity while recovering standard DPO as a special case. To handle discrete or sparse signals, we introduce an equivalence-class construction where responses with identical preferences form graph layers, and intra-layer edges contribute zero loss, preventing spurious gradients. Despite leveraging full graph structure, GraphDPO maintains linear per-prompt complexity via efficient log-sum-exp aggregation. We further incorporate optional ground-truth anchoring by inserting verified solutions as dominant nodes and applying an annealed schedule that stabilizes early training while gradually relaxing oracle supervision. Experiments on reasoning and program synthesis tasks demonstrate superior performance, suggesting that graph-structured preference modeling is a scalable and robust alternative to pairwise and listwise alignment objectives.
Beyond the Full Slate: Evaluating MNL Algorithms on All Slates
Flavio Chierichetti ⋅ Mirko Giacchini ⋅ Ravi Kumar ⋅ Silvio Lattanzi ⋅ Alessandro Panconesi ⋅ Erasmo Tani ⋅ Andrew Tomkins
Multinomial logit models (MNLs) are ubiquitous in machine learning, particularly in recommendation systems. While these models are typically evaluated using global metrics over a full catalog of items (such as $\ell_2$-error), practical applications often involve making predictions on small, curated subsets or ``slates'' of items. A model that minimizes global error may nevertheless yield very poor predictions on specific sub-universes. Yet, evaluating performance across all possible subsets remains computationally challenging. In this paper, we present a set of new efficient algorithms to evaluate the small-slate performance of MNL models. Using these tools, we conduct an empirical study comparing standard non-adaptive and adaptive learning algorithms. We demonstrate that while methods that compute the Maximum Likelihood Estimate (MLE) suffer from poor worst-case performance on small slates, specialized adaptive algorithms that dynamically sample difficult subsets can mitigate this issue. Conversely, we find that non-adaptive algorithms often achieve competitive average-case performance; we provide a theoretical model explaining this phenomenon. We conclude with recommendations for practitioners regarding when to utilize adaptive sampling based on the specific robustness requirements of their application.
Bifurcation Models: Learning Set-Valued Solution Maps with Weight-Tied Dynamics
Caleb Jore ⋅ Jialin Liu
Many scientific and combinatorial problems admit multiple correct solutions, not a single label. Standard supervised learning resolves this ambiguity by choosing one solution as the target, but this hidden selector can be arbitrary, discontinuous, and harder to learn than the underlying solution set. We study bifurcation models, a weight-tied dynamical view in which different initializations can converge to different stable equilibria, so the model represents an attractor landscape rather than one chosen branch. We prove that broad set-valued maps with locally Lipschitz branches can be represented by regular equilibrium dynamics and that the induced selectors are almost everywhere regular, while manual selectors can be arbitrarily irregular. Experiments on frustrated Ising models show that such dynamics can discover multiple valid equilibria without branch labels and outperform single-branch supervision. Allen-Cahn experiments further show that diversity is not automatic: it can be encouraged explicitly, but with an accuracy--diversity tradeoff.
Can Entry-Wise Clipping Give Spectral Control of Stochastic Gradients?
Zitao Song ⋅ Cedar Site Bai ⋅ Zhe Zhang ⋅ Brian Bullins ⋅ David Gleich
Training instabilities such as loss spikes are frequently the result of stochastic gradient noise. Because of rare expressions in language training data, and multiple layer composition, the noise impact is heavy-tailed and survives mini-batch averaging. Gradient clipping is designed to address this where vector-norm clipping ignores matrix structure in weight updates, while spectral normalization (e.g. Muon) respects structure at additional cost. We show an entry-wise \emph{heavy-tailed noise} appears similar to real stochastic gradient noise. Furthermore, through a first-order perturbation analysis, we identify a \emph{localization} property under which a simple entry-wise method will give spectral normalization. Exploiting this, we derive a tractable surrogate for the Bayes-optimal entry-wise estimator under a Gaussian signal prior. We establish $O(\epsilon^{-4})$ convergence guarantee under Cauchy-contaminated noise. Empirically, we find that smooth shrinkage improves Adam on NanoGPT pretraining, saving ${\sim}$8% of training tokens. We further find that applying the entry-wise clipping before spectral normalization yields a ${\sim}$2% token saving on top of Muon.
Capturing LLM Capabilities via Evidence-Calibrated Query Clustering
Fangzhou Wu ⋅ Sandeep Silwal ⋅ Qiuyi (Richard) Zhang
Query clustering organizes queries into groups that reflect shared latent capability demands, enabling capability-aware LLM evaluation. Existing clustering methods, which primarily rely on semantic taxonomies or embeddings, often fail to capture such latent capability requirements due to a misalignment between surface-level semantics and actual model performance. We propose ECC, an algorithm that calibrates prior semantic embeddings using limited posterior model comparisons to bridge the gap between surface-level semantics and latent capability requirements. ECC characterizes each cluster through a capability profile parameterized by a Bradley-Terry model and uses trainable mixture weights to accommodate queries with mixed capability demands, jointly learning a flexible, capability-aware clustering structure that supports query-specific inference of LLM capabilities. Extensive quantitative and qualitative evaluations demonstrate that ECC significantly improves LLM capability ranking quality, outperforming human-labeled and embedding-based baselines by an average of 17.64 and 18.02 percentage points, respectively, and proves effective in downstream tasks such as query routing.
We study a canonical multi-task demand-learning problem motivated by retail pricing, where a firm seeks to estimate heterogeneous linear price-response functions across multiple decision contexts. Each context is described by rich covariates but exhibits limited price variation, motivating transfer learning across tasks. A central challenge in leveraging cross-task transfer is endogeneity: prices may be arbitrarily correlated with unobserved task-level demand determinants across tasks. We propose a new meta-learning framework that identifies the conditional mean of task-specific causal demand parameters given a subset of task-specific observables despite such confounding, assuming that each task contains at least two distinct locally exogenous price points. This subset is carefully designed to include all of the prices to address cross-task confounding, while masking two demand outcomes that provide randomized supervision to address identifiability issues arising from the inclusion of all prices. We show that this information design is maximally uniformly valid, in that any refinement of the conditioning set that reveals withheld-outcome information is not guaranteed to identify the conditional mean causal target. We validate our method on real and synthetic data, demonstrating improved recovery of demand responses relative to standard transfer-learning baselines.
CLUE: Correlated Latent Uncertainty for Single-Pass Deep Uncertainty Estimation
Yucheng Wang ⋅ Wenyuan Zhao ⋅ Weifeng Zhang ⋅ Chao Tian ⋅ Xiaoning Qian
We present Correlated Latent Uncertainty Estimation (CLUE), a single-pass deep uncertainty quantification framework that combines efficient amortized neural prediction with Bayesian-style information propagation across inputs. CLUE introduces a kernel-based prior, allowing cross-input dependence over latent variables while preserving test-time inference efficiency. CLUE requires neither posterior sampling nor ensembles, and avoids matrix inversion during inference, yet recovers posterior contraction behavior analogous to conventional Bayesian models. In the white-noise limit of the kernel, CLUE reduces to standard evidential deep learning (EDL). This limiting case reveals standard EDL as amortized variational inference with an independent latent structure, providing a probabilistic explanation for several pathologies of EDL identified in prior work. Empirically, CLUE exhibits consistent Bayesian-like uncertainty contraction and improved uncertainty quality across synthetic and real-world benchmarks, while maintaining competitive predictive accuracy and fast single-pass inference.
Community-Centered AI is Feasible and Beneficial for Impacted Communities
Tzu-Sheng Kuo ⋅ Quan Ze Chen ⋅ Amy Zhang ⋅ Kenneth Holstein ⋅ Haiyi Zhu
AI systems are increasingly used in community contexts, yet they often fail to align with the communities they impact. To address this misalignment, we advocate for community-centered AI---an AI development paradigm that shifts away from pursuing general-purpose AI and instead focuses on co-developing tailored AI systems with the specific communities they impact. This position paper argues that community-centered AI is both feasible and beneficial for impacted communities. To support this argument, we first outline the potential benefits of community-centered AI, including greater alignment, enhanced legitimacy, capacity building, and normative justification. Next, we highlight emerging efforts in community-centered AI across the AI development process, demonstrating its feasibility in delivering these benefits. Finally, we propose a framework to guide future work in this area, characterizing community-centered AI efforts along three dimensions: participation mode, decision-making process, and development layer. Overall, this paper calls for increased research on community-centered AI.
Hybrid language models that mix attention and recurrent layers have shown promise: theoretically, recurrent layers ameliorate the limitations of pure transformers on state tracking, and empirically, hybrids can outperform pure transformers in loss and downstream evaluations \citep{waleffe2024empirical,merrill2026olmohybrid}. Yet it remains unclear which data or capabilities drive these gains, and to what degree they reflect the theoretical advantages motivating hybrid models. We address this by analyzing the benefits of hybrid models at the token level---which kinds of tokens are better predicted by hybrids than by pure transformers---using the open weights from Olmo 3 \citep{olmo2025olmo3} and Olmo Hybrid \citep{merrill2026olmohybrid}. Hybrids predict tokens better across the board, but we show these gains localize to open-class content words rather than closed-class function words. Across natural language and code, the loss gap shrinks on closing brackets (but not opening brackets), consistent with the hypothesis that attention, not hybrid layers, is largely responsible for processing hierarchical structure. The hybrid advantage also vanishes on repeated $n$-grams. Overall, while attention suffices for tokens involving copying and purely syntactic information, hybrids show an advantage on more semantically conditioned predictions, likely because these are aided by a strong representation of the discourse state. We conclude with discussion and proof-of-concept experiments showing how these findings could refine design principles and pretraining evaluations for hybrid architectures.
Complementing DINO Features with Image Structure for Part Discovery
Samyak Rawlekar ⋅ Nikhil C Paleti ⋅ Amey Gupta ⋅ Narendra Ahuja
Self-supervised Vision Transformers (ViTs) like DINO encode rich semantics, enabling training-free segmentation of objects from the background and discovery of their parts via feature clustering. This paper focuses on part discovery: partitioning a foreground object into semantic parts. Existing approaches produce imprecise part boundaries. We trace this to the rigid ViT patch grid used in training DINO, where patches straddling boundaries contain pixels from multiple parts. While DINO's invariance-based training could absorb this pixel-level mixing into clean features, experiments with over 26K foreground patches show it does not: boundary-overlapping patches produce features with higher entropy and lower assignment confidence, blurring predicted part boundaries. Rather than make the massive effort of retraining DINO over geometrically coherent regions, an easier approach is to take boundaries directly from a boundary detector, which supplies the geometric information DINO's features lack. Motivated by this, we introduce Part-DINO, a training-free framework that combines boundaries from low-level image segmentation with DINO's semantic features. We use the boundaries to partition the image into regions, pool DINO features within each region, and group them to discover parts. Without any training, Part-DINO produces structurally coherent part assignments, outperforming training-free baselines across four standard benchmarks (CUB, CelebA, PartImageNet-OOD, PartImageNet-Seg) and remaining competitive with weakly-supervised and unsupervised methods.
Composable Causality: A Toolkit for Systematic Time-Series Causal Discovery and Treatment-Effect Benchmarking
Muhammad Hasan Ferdous ⋅ Md Osman Gani
Real-world multivariate time series datasets rarely come with verified ground-truth causal structure, since the underlying mechanisms are typically unknown and randomized intervention is infeasible in most domains. Empirical research on time-series causal discovery and treatment-effect estimation therefore depends on synthetic data, where the data-generating process is specified by construction. Existing data generation tools fall into two categories. Some are fixed datasets that provide pre-generated time series, which cannot be modified after release. Others are script-based generators, where each script fixes one combination of mechanism, confounding, and missingness, so any new combination requires writing new code. Neither supports the controlled experiments that method development demands, where a single property such as sparsity, noise distribution, or missingness mechanism is varied while others are held fixed. A further gap concerns counterfactual data. Prior work in time-varying treatment-effect estimation has relied on per-paper simulators with hardcoded mechanisms, while general-purpose time-series generators produce observational data only, leaving evaluation of conditional average treatment effect estimators reliant on conditional expectations rather than ground-truth individual effects. We introduce DTCD (Datasets and Toolkit for Causal Discovery), a data generation library that produces multivariate time series together with their ground-truth contemporaneous and lagged adjacency matrices. Topology, mechanism, noise, observational mask, and intervention policy are independent components that compose freely, enabling single-axis sensitivity studies through configuration alone. Paired counterfactual twins are produced by caching the stochastic realization during the factual rollout and re-injecting it during the interventional rollout, recovering individual treatment effects to numerical precision. To demonstrate the library, we present a reference benchmark of eight discovery algorithms across eighty-one discovery configurations and four treatment-effect estimators across eighteen CATE configurations, exposing failure modes not visible in aggregate metrics, including the inability of standard discovery methods to handle missing values regardless of whether the missingness mechanism is informative.
Constrained Decoding for Diffusion Language Models via Efficient Inference over Finite Automata
Meihua Dang ⋅ Stefano Ermon
Constrained decoding is essential for serving LLMs, ensuring that generated outputs follow specific structures such as JSON schema-formatted function calls. Existing systems are designed for autoregressive models and assume left-to-right generation, masking out invalid next tokens at each step. Diffusion language models, however, break this assumption: they sample multiple positions simultaneously from a fully-factorized mean-field distribution at each denoising step. In this paper, we present an exact and tractable algorithm for sampling from the constrained mean-field posterior under any constraint expressible as a finite automaton. Viewing finite automata as graphical models, we obtain tractable representations of the constrained distribution that enable efficient inference. The approach guarantees constraint satisfaction by construction, supports both greedy and sampling-based decoding, and is compatible with parallel and block-wise decoding under arbitrary remasking schedules. Applying depth-reduction techniques from arithmetic circuit theory, we further reduce sampling depth from linear to logarithmic in the sequence length. Empirical evaluations on Dream-7B and LLaDA-8B show substantial accuracy gains across various tasks including function calling (xLAM, BFCL), planning (Sudoku, Countdown), text-to-SQL (Spider), and math reasoning (GSM-Symbolic), with little inference overhead relative to unconstrained decoding. For example, on BFCL-Live, our approach improves Dream-7B's greedy decoding accuracy from 63.9% to 71.5%, and stochastic sampling accuracy from 22.3% to 69.0%, where the unconstrained baseline collapses, with under 5% wall-clock overhead.
Continual Robot Learning via Language-Guided Skill Acquisition
Shuo Cheng ⋅ Zhaoyi Li ⋅ Kelin Yu ⋅ Danfei Xu
To support daily human tasks, robots need to tackle complex, long-horizon tasks and continuously acquire new skills to handle new problems. Deep Reinforcement Learning (DRL) offers potential for learning fine-grained skills but relies heavily on human-defined rewards and faces challenges with long-horizon goals. Task and Motion Planning (TAMP) are adept at handling long-horizon tasks but often need tailored domain-specific skills, resulting in practical limitations and inefficiencies. To overcome these complementary limitations, we propose LG-SAIL (Language Models Guided Sequential, Adaptive, and Incremental Skill Learning), a framework that leverages Large Language Models (LLMs) to synergistically integrate TAMP and DRL for continuous skill learning in long-horizon tasks. Our framework achieves automatic task decomposition, operator creation, and dense reward generation for efficiently acquiring the desired skills. To facilitate new skill learning, our framework maintains a symbolic skill library and utilizes the existing model from semantic-related skills to warm start the training. LG-SAIL demonstrates superior performance compared to baselines across six challenging simulated task domains across two benchmarks. Furthermore, we demonstrate the ability to reuse learned skills to expedite learning in new task domains, and deploy the system on a physical robot platform. More results on website: https://sites.google.com/view/continuallearning.
Continuous Diffusion Scales Competitively with Discrete Diffusion for Language
Zhihan Yang ⋅ Wei Guo ⋅ Shuibai Zhang ⋅ Subham Sahoo ⋅ Yongxin Chen ⋅ Arash Vahdat ⋅ Morteza Mardani ⋅ John Thickstun
While diffusion has drawn considerable recent attention from the language modeling community, continuous diffusion has appeared less scalable than discrete approaches. To challenge this belief we revisit Plaid, a likelihood-based continuous diffusion language model (DLM), and construct RePlaid by aligning the architecture of Plaid with modern discrete DLMs. In this unified setting, we establish the first scaling law for continuous DLMs that rivals discrete DLMs: RePlaid exhibits a compute gap of only $22\times$ compared to autoregressive models, matches Duo while using fewer parameters, and outperforms MDLM in the over-trained regime. We benchmark RePlaid against recent continuous DLMs: on OpenWebText, RePlaid achieves a new state-of-the-art PPL bound of $22.6$ among continuous DLMs and superior generation quality. These results suggest that continuous diffusion, when trained via likelihood, is a highly competitive and scalable alternative to discrete DLMs. Moreover, we offer theoretical insights to understand the advantage of likelihood-based training. We show that optimizing the noise schedule to minimize the ELBO's variance naturally yields linear cross-entropy (information loss) over time. This evenly distributes denoising difficulty without any case-specific time reparameterization. In addition, we find that optimizing embeddings via likelihood creates structured geometries and drives the most significant likelihood gain.
Controllable Road Marking Generation
Zhiyu Joey Cai ⋅ Yufan Zhang ⋅ Ruichen Tan ⋅ Zengxiang Lei ⋅ Satish Ukkusuri
Lane and road markings provide critical guidance for vehicle navigation and multi-agent coordination, yet their design principles are scattered across disparate datasets, severely limiting quantitative analysis and scenario testing. We introduce controllable road-marking generation: given a drivable-area mask and a sparse outer-ring observation, a model must synthesize a complete center-region layout of lane dividers, road dividers, and pedestrian crossings that is semantically consistent with a free-form text prompt. We develop a conditional diffusion pipeline that combines (i) a text-conditioned BEV diffusion backbone, (ii) a Gaussian blur-then-deblur training target that stabilizes thin-structure learning, and (iii) a structured Gaussian render post-processing step that snaps soft predictions to crisp, topology-aware markings. On the Argoverse 2 test split, our system substantially outperforms a state-of-the-art DDIM mask-refinement baseline on standard structural fidelity metrics, and supports prompt-level edits across crosswalk, lane-divider, and road-divider semantics. We anticipate that the proposed framework will enable downstream applications in urban infrastructure planning, autonomous-driving stress-testing, and navigation in unstructured environments.
Convex Compositional Reasoning Models
Meir Roketlishvili ⋅ Semen Semenov ⋅ Maksim Bobrin ⋅ Viktor Kovalchuk ⋅ Albert Baichorov ⋅ Abduragim Shtanchaev ⋅ Fakhri Karray ⋅ Dmitry V. Dylov ⋅ Martin Takac ⋅ Arip Asadulaev
Compositional energy-based models can generalize to larger combinatorial reasoning problems by reusing a learned factor energy across many local constraints. In our paper, we show that a key bottleneck in compositional reasoning is not composition itself, but the non-convex geometry of the learned energy landscape. To solve this problem, we introduce Convex Compositional Energy Minimization (CCEM), a framework that parameterizes each factor with an input-convex neural network and optimizes the composed energy over a tight convex relaxation of the feasible set. Because convexity is preserved under summation, the global relaxed objective remains convex, enabling deterministic projected first-order optimization. CCEM is trained in two stages: factor-level contrastive learning to shape local energy basins, followed by end-to-end refinement through an unrolled projected solver. Our experiments show that our models trained on small subproblems or a single problem size transfer to larger instances without retraining.
CoTrek: Toward Scalable On-Policy Distillation for Long Chain-of-Thought Reasoning
Heng Zhang ⋅ Chengyu Zhou ⋅ Jiajun Wu ⋅ Estella Liu ⋅ Liheng Zhang ⋅ Yueqi Guo ⋅ Rui Liu ⋅ JiaHao Hong ⋅ Xuanxun Lian ⋅ Jinpeng Lu ⋅ Jin Huang
On-policy distillation has emerged as an efficient paradigm for improving long chain-of-thought reasoning in large language models, where the student learns from its own rollouts while receiving dense teacher feedback on the states it actually visits. Prior work in this paradigm has focused on advancing \textit{continuation learning} through better teacher scoring, more stable optimization, or more learnable traces, yet largely overlooks a critical failure mode in long-horizon reasoning: once the student drifts at a deep prefix, the bottleneck is no longer how to \textit{continue} from the current path but how to \textit{recover} to an effective one. To address this gap, we propose \ourmethod, a recovery-centric framework for on-policy distillation in long chain-of-thought reasoning. \ourmethod operates on student-generated deep prefixes that have already drifted off track yet still admit successful teacher recovery. From each such prefix, it samples multiple teacher recoveries, extracts the short \textit{repair segment} they share, and trains the student to produce this repair before continuing the remaining reasoning on policy. This design shifts the distillation target from full-suffix imitation to focused path re-entry. To further support long-horizon learning, \ourmethod follows a depth curriculum that expands training depth according to the observed recovery gap, allowing the student to progressively extend its effective reasoning horizon. Extensive experiments on long chain-of-thought benchmarks demonstrate that \ourmethod delivers (I) \textbf{substantial performance gains}, improving strong on-policy distillation baselines by up to $6.84\%$ in final accuracy and $9.27\%$ in recovery success; and (II) \textbf{strong long-horizon robustness}, bringing $3.11\%$--$7.46\%$ gains on deeper prefix regimes and consistent pass@$k$ improvements under longer reasoning horizons.
Cross-Distribution Generalization in Longitudinal Behavioral Data Through Frozen Coherence Constraints
Ahatsham Hayat ⋅ Mohammad Hasan
Cross-distribution generalization in longitudinal behavioral data remains a persistent obstacle. Models trained on one cohort degrade on new populations, and prior approaches operating through feature-distribution alignment or model-capacity scaling have not substantially improved cross-distribution performance. We diagnose the limitation as insufficient representational constraints during training. We propose holding the language model frozen, so that the coherence criterion is defined by its pre-trained language prior and cannot shift during training. We introduce PRISM, a frozen-backbone framework that decomposes each behavioral trajectory into temporal, spectral, and semantic streams and integrates them through directed cross-attention with instance-specific gating. Training uses a dual-path objective combining discriminative and coherence constraints on a shared representation. On GLOBEM, a widely used cross-cohort benchmark for behavioral health prediction, PRISM achieves 79.93\% out-of-distribution accuracy, 27.13 points above the previous best, with an in-distribution to out-of-distribution accuracy gap of 1.24 points. PRISM also achieves the highest OOD accuracy on three additional datasets (LifeSnaps anxiety, MFAFY engagement, CrossCheck schizophrenia symptoms), with consistently smaller ID-to-OOD gaps than fine-tuned VLM baselines. Ablations identify the frozen coherence constraint as the component responsible for the distribution-invariance pattern.
Neural Posterior Estimation (NPE) trains an amortized conditional density estimator to approximate posterior distributions in simulation-based inference. Each training pair is a single draw from the joint distribution of latent and observation, so posterior variance at an observation must be inferred from variation across pairs rather than within them. However, with a sufficiently flexible variational distribution, the NPE training objective is unbounded, and standard optimizers yield arbitrarily small variance. Regularizers like early stopping, dropout, and weight decay constrain network capacity without targeting the correct posterior variance. We propose Cross-Fitting NPE (CF-NPE), which separates mean estimation from higher-moment estimation via sample splitting. Concretely, CF-NPE estimates a conditional-mean ensemble by $K$-fold cross-fitting, then fits a conditional density to the resulting out-of-fold residuals. The conditional variance of an out-of-fold residual is bounded below by the true posterior variance, giving CF-NPE a well-defined population-level target that standard NPE lacks. Across eight synthetic benchmarks and a cosmological application, CF-NPE achieves higher held-out log-likelihood than standard NPE, with gains that grow with the latent dimension.
CSI-TextBench: A Dataset and Benchmark for Language-Grounded Ambient Sensing Perception
Guozhen Zhu ⋅ Yuqian Hu ⋅ Sakila S Jayaweera ⋅ Wei-Hsiang Wang ⋅ Beibei Wang ⋅ K. Liu
Indoor context deciphered by ambient sensing underpins many applications, from assisted living to smart buildings, yet remains weakly connected to the language-aligned paradigm of modern multimodal systems. Through billions of IoT devices, ambient WiFi Channel State Information (CSI) captures the indoor context of human activity and environmental dynamics passively via ubiquitous, always-on infrastructure. However, unlike vision or audio, CSI lacks naturally paired text like captions or transcripts, limiting its integration with language-driven AI systems. We present CSI-TextBench, a large-scale dataset and benchmark for aligning CSI data with natural language, unifying 3 sensing benchmarks into 285,790 samples across 7 tasks and pairing them with 2,291 hierarchically structured, label-derived descriptions via many-to-many assignment to construct 2.0 million CSI–text training tuples. Benchmarking 5 alignment methods from 4 paradigm families, we show that contrastive CSI--text alignment matches supervised classifiers without class labels, adapts to unseen classes with few samples, and responds to open-vocabulary natural-language prompts. A single unified model supports compositional scene understanding, answering joint queries over activity, proximity, and identity, achieving 86.9\% top-1 accuracy on 140 composite scenes, outperforming task-specific classifier ensembles. CSI-TextBench enables ubiquitous ambient sensing as a language-indexed perception layer, enabling indoor contextual awareness in language-driven AI systems.
CUDABeaver: Benchmarking LLM-Based Automated CUDA Debugging
Shiyang Li ⋅ Haoyang Chen ⋅ Mattia Fazzini ⋅ Caiwen Ding
Debugging CUDA programs has long been challenging because failures often arise from subtle interactions among hardware behavior, compiler decisions, memory hierarchy, and asynchronous execution. More importantly, with the rapid expansion of GPU usage across scientific computing, machine learning, graphics, and systems workloads, CUDA debugging has become more challenging than ever. Current evaluations of LLM-based CUDA programming largely miss this setting: a model can pass correctness tests with repair by degeneration, simplifying the CUDA code into a safer but slower program that abandons the original optimization structure. We introduce CUDABEAVER, a benchmark for CUDA debugging from real failing workspaces produced during LLM-based CUDA generation. Each task provides the broken candidate, native build/test commands, raw error evidence, and a single editable file. CUDABEAVER evaluates whether a fixer truly repairs the failing CUDA code or merely finds a slower test-passing replacement, reporting results by failure category, debugging trajectory, stagnation mode, and performance preservation. We further propose pass@k(M,C,A), a protocol-conditional CUDA debugging metric by making the fixer M, corpus C, and protocol axes Aexplicit. Using this metric across 213 tasks and seven frontier LLMs, we show that protocol-aware evaluation gives a more faithful view of CUDA debugging ability: when performance-loss tolerance is high, fixers appear much stronger, but even a minor stricter performance requirement can sharply reduce measured success, shifting scores by up to 40 percentage points.
Decentralized Aggregation of LLM Predictions via Wagering Mechanisms
Yuhong Luo ⋅ David Pennock ⋅ Xintong Wang
We propose WALLA, a decentralized mechanism for aggregating probabilistic predictions from multiple LLMs using wagering mechanisms. Each model reports a prediction and a learned wager reflecting its expected score advantage; predictions are then aggregated using wagers as weights. Our mechanism introduces a leave-one-out baseline that yields three key properties: dominant-strategy incentive compatibility under general belief structures, a best-response wager proportional to expected score advantage, and decoupling of prediction and wager optimization. We instantiate two mechanism variants trading off normality and no-arbitrage, both with bounded worst-case deficit independent of the number of participants. Experiments on QA benchmarks and a forecasting benchmark show that WALLA matches centralized baselines while simultaneously achieving advantage-weighted aggregation, uncertainty-awareness, fully decentralized learning, and incentive-compatibility guarantees.
Decision-Focused Learning in MDPs: An Occupancy Measure Approach
Zihao Zhao ⋅ Ashwath K Karunakaram ⋅ Ali Eshragh ⋅ Yuexing Li ⋅ Kai Wang
In this work, we consider decision-focused learning (DFL) for a Markov decision process (MDP), where existing methods differentiate through the KKT conditions of the Bellman equation and require solving a linear system over all state-action pairs, limiting its scalability. We address this by reformulating the MDP as an occupancy measure-based linear program (LP), whose feasible region is induced by predicted dynamics, and we derive a closed-form gradient by identifying the active constraints in the feasible polyhedron via the pivoting algorithm. This occupancy measure-based LP layer raises two challenges: (1) LP's solution gradient is discontinuous when active constraints change, and (2) the LP backward cost still scales with the state size, which is costly for large or continuous state spaces. We address the challenges with an augmented Lagrangian surrogate and smooth the boundary jumps by random row sketching of the constraints, and a learnable soft state-aggregation layer and its function-approximation generalization that scales the LP to large finite and continuous-state MDPs. Across multiple tasks, our methods reach lower regret than KKT-based DFL and two-stage baselines with significantly lower computation cost. The source code for all experiments is available here.
Semi-implicit variational inference (SIVI) expands the representational capacity of variational families, but optimizing the Evidence Lower Bound (ELBO) remains challenging because the marginal score of the semi-implicit distribution is generally intractable. Unbiased Implicit Variational Inference (UIVI) and related methods address this difficulty through reparameterized ELBO gradients, but existing approaches estimate the required score indirectly through reverse-conditional sampling or approximation, which can be computationally costly and unstable. We propose Denoising Implicit Variational Inference (DIVI), which learns the marginal score directly via denoising score matching. The learned score is used as a plug-in estimator in the pathwise ELBO gradient, replacing inner reverse-conditional sampling with a score-network evaluation. We analyze DIVI as inexact stochastic gradient ascent and show, under stated assumptions, that the averaged stationarity measure is controlled by the usual optimization term and the average score-matching error. Empirically, we evaluate DIVI on both synthetic distributions and a variety of real-data Bayesian inference tasks. The results show that DIVI improves over the current UIVI baselines while reducing the cost of ELBO-gradient estimation.
Diffeomoprhism-Informed 3D Gaussian Splattings via Screen-Space Optimal Transport (OT)
Xiang Gao ⋅ Xiaoping Zhu ⋅ Xinmu Wang ⋅ Yuanpeng Liu ⋅ Haotian Yin ⋅ Dichang Zhang ⋅ Yazheng Chen ⋅ Yue Wang ⋅ Yubin Zhou ⋅ Yu Guo ⋅ Wei Chen ⋅ David Gu ⋅ Xiyun Song ⋅ Heather Yu
3D Gaussian Splatting (3DGS) has emerged as an effective solution for real-time novel view synthesis (NVS) with high rendering quality, but training memory scales with image resolution, making downsampled supervision common and leading to loss of sharp, high-frequency details and degraded perceptual quality. Moreover, uniform supervision assigns equal weight to all pixels, resulting in weak emphasis on detail-rich regions such as edges and thin structures. We propose \textbf{OT-3DGS}, which leverages optimal transport in screen space to reparameterize the image domain prior to downsampling, inducing importance-based non-uniform supervision that redistributes pixel budget toward geometry-critical regions and strengthens supervision on high-frequency content. Our method remains fully compatible with the original 3DGS pipeline, requiring no modification to loss functions, rendering settings, or pruning, cloning, and splitting strategies. Experiments across diverse datasets show that OT-3DGS produces sharper structures, clearer reflectance, and reduced over-smoothing; while PSNR and SSIM may slightly decrease due to deviation from downsampled references, reference-free metrics including BRISQUE, NIQE, and Laplacian Variance (LV) improve significantly, better reflecting perceptual quality and high-frequency detail. These results demonstrate that OT-3DGS aligns with the fundamental goal of NVS: generating perceptually realistic, high-quality unseen views.
Differential Item Functioning as an Item-Level Diagnostic for LLM Benchmarks
Hansol Lee ⋅ Jason B Cho ⋅ Nick Haber ⋅ Benjamin Domingue ⋅ Sanmi Koyejo
Comparative claims about large language model (LLM) performance are typically based on aggregate benchmark scores. This treats models with similar scores as comparable on the items the benchmark contains, an assumption that can fail if models from different populations succeed on systematically different items. We test this assumption using Differential Item Functioning (DIF), a psychometric diagnostic that flags items whose relative difficulty differs across groups after conditioning on overall performance. Applying Mantel--Haenszel DIF analyses to six widely-used LLM benchmarks across two widely-used open-source model families (Llama and Qwen), we find that many items behave differently across families even among models with the same total benchmark score, with some items favoring Llama-family models and others favoring Qwen-family models. The flagged items concentrate in benchmark-provided categorical content (subjects, subtasks, problem types), and choosing items based on which family they favor can substantially amplify, attenuate, or reverse aggregate family-level comparisons. Our results show that aggregate benchmark scores can summarize different item-level performance patterns across model populations, and that DIF offers a useful diagnostic for surfacing this variation.
Diffusion Language Models Can Approximate Optimal Infilling Lengths Implicitly
Hengchang Liu ⋅ Zhao Yang ⋅ Bing Su
Diffusion language models (DLMs) provide a bidirectional generation framework naturally suited for infilling, yet their performance is constrained by the pre-specified infilling length. In this paper, we reveal that DLMs possess an inherent ability to discover the correct infilling length. We identify two key statistical phenomena in the first-step denoising confidence: a local Oracle Peak that emerges near the ground-truth length and a systematic Length Bias that often obscures this signal. By leveraging this signal and calibrating the bias, our training-free method CAL (Calibrated Adaptive Length) enables DLMs to approximate the optimal length through an efficient search before formal decoding. Empirical evaluations demonstrate that CAL improves Pass@1 by up to 47.7% over fixed-length baselines and 40.5% over chat-based adaptive methods in code infilling, while boosting BLEU-2 and ROUGE-L by up to 8.5% and 9.9% in text infilling. These results demonstrate that CAL paves the way for robust DLM infilling without requiring any specialized training.
DiPMInd: Distance profile based mutual independence testing for random objects
Yaqing Chen ⋅ Paromita Dubey
This paper develops a novel unified framework for testing mutual independence among random objects residing in possibly different metric spaces. The framework generalizes existing methodologies and introduces new measures of mutual independence, and proposes associated tests that achieve minimax rate optimality and exhibit strong empirical power. The foundation of the proposed tests is the new concept of joint distance profiles, which uniquely characterize the joint law of random objects under a mild condition on either the joint law or the metric spaces. Our test statistics quantify the difference of the joint distance profiles of each data point with respect to the joint law and the product of marginal laws of the vector of random objects. To enhance power, we consider integrating this difference with respect to different measures and incorporate flexible data-adaptive weight profiles in the test statistics. We derive the limiting distribution of the test statistics under the null hypothesis of mutual independence and show that the proposed tests with certain weight profiles are asymptotically distribution-free if the marginal distance profiles are continuous. Furthermore, we establish the consistency of the tests under sequences of alternative hypotheses converging to the null. For practical implementations, we employ a permutation scheme to approximate the p-values and provide theoretical guarantees that the permutation-based tests maintain type I error control under the null and achieve consistency under alternatives. We demonstrate the power of the proposed tests across various types of data objects through simulations and real data applications, where the new tests exhibit better performance compared with popular existing approaches.
DisSparse: Pipelined Top-$p$ Sparse Attention for Long-Context LLM Serving
Nurlan Nazaraliyev ⋅ Elaheh Sadredini ⋅ Nael Abu-Ghazaleh
Long-context LLM inference is bottlenecked by the memory demands of the key-value (KV) cache, whose size scales linearly with context length. Dynamic sparse attention reduces this bottleneck by fetching and attending only to a critical subset of tokens. The dominant primitive in dynamic sparse attention research and deployment is fixed-budget top-$k$ selection, which is favored because its deterministic block count aligns with the static memory allocation that systems like vLLM rely on. Top-$k$ uses a fixed budget regardless of how attention mass is distributed across heads, layers, and decode steps, leading to either wasted bandwidth on heads with peaky attention or dropped context on heads with diffuse attention. Top-$p$ (nucleus) selection adapts naturally to this variation but has seen limited adoption in production serving systems due to two system-level challenges: variable block counts that break deterministic block allocation and computationally expensive selection kernels that exceed the cost of attention itself. We present DisSparse, a serving system that integrates top-$p$ sparse attention into vLLM end-to-end. DisSparse decouples block selection from the scheduler's critical path, hides selection latency behind layer computation via a two-stream pipeline, and introduces a single-pass histogram-based top-$p$ kernel. We further observe *intra-block sparsity*, the inflation of selection budgets caused by mixing high- and low-importance tokens within fixed-size KV cache blocks, and address it with a token relocation kernel guided by accumulated prefill attention scores. Across long- and medium-context benchmarks on multiple models, DisSparse achieves up to 1.45$\times$ speedup in sparsity analysis (block selection) over state-of-the-art top-$p$ methods with no accuracy loss and supports up to 8$\times$ larger maximum batch sizes than dense vLLM under the same memory budget.
Distilling Sequential Computation in Transformer Language Models
Zixuan Lan ⋅ Jessica Yang ⋅ Yanhong Li ⋅ Karen Livescu ⋅ Jiawei Zhou
Transformer language models process sequences token by token in an autoregressive manner, making growing contexts increasingly expensive. Yet many adjacent token spans are highly predictable or frequently occur as stable units, suggesting that their representations may be compressible. We introduce a method for distilling sequential computation by replacing spans of input tokens with collapsed representations, computed on the fly by a lightweight merge module. This module generates a single surrogate embedding from a sequence of static token embeddings that captures the functional role of the multiple tokens, allowing pretrained models to operate on compressed inputs without architectural changes or re-training. We apply this approach during inference to compress both prompts and intermediate decoding steps, using a rollback mechanism to substitute stored multi-token KV cache entries with their single-step surrogates. Experiments across diverse models show that the merge module can be used to reduce effective sequence length by up to 40\% with minimal accuracy degradation across language-modeling evaluations and downstream tasks, including question answering, summarization, commonsense reasoning, and long-form mathematical reasoning. Additional lightweight adaptation of the merge module further improves the accuracy-compression trade-off in selected settings. These results demonstrate that sequential token computation in Transformers can be effectively approximated through condensed surrogate representations that preserve the original behavior without model updating.
DivMoE: Fine-Grained MoE Upcycling via Cross-Domain Expert Composition
Yuxuan Lou ⋅ Kai Yang ⋅ Geng Zhang ⋅ Yong Liu ⋅ Yang You
Mixture-of-Experts (MoE) architectures have become essential for building capable large language models, with recent work demonstrating the benefits of fine-grained expert designs. However, training MoE models from scratch is computationally expensive, and existing upcycling methods that convert dense models to MoE face limitations: they either initialize experts as identical copies (limiting routing diversity) or use random perturbations (risking knowledge loss). We propose \textsc{DivMoE}, a framework that addresses these challenges through two innovations. First, we introduce \emph{domain-specialized expert initialization}, deriving fine-grained experts from models fine-tuned on distinct domains (mathematics, code, science, commonsense), providing meaningful diversity while preserving pre-trained knowledge. Second, we propose \emph{diversity-constrained routing}, which enforces that each token selects at most one expert per domain group, structurally preventing routing collapse and enabling cross-domain knowledge composition. Experiments on two base models demonstrate that \textsc{DivMoE} outperforms all upcycling baselines (47.0% vs.\ 44.4% average accuracy) and achieves competitive performance with MoE models trained from scratch, matching Moonlight-MoE at 64.5% average while being constructed via efficient upcycling.
Do Joint Audio-Video Generation Models Understand Physics?
Zijun Cui ⋅ Xiulong Liu ⋅ Hao Fang ⋅ Mingwei Xu ⋅ Jiageng Liu ⋅ Zexin Xu ⋅ Weiguo Pian ⋅ Shijian Deng ⋅ Feiyu Du ⋅ Chenming Ge ⋅ Yapeng Tian
Joint audio-video generation models are rapidly approaching professional production quality, raising a fundamental question: do these models truly understand audio-visual physics, or do they merely generate plausible sounds and frames that violate real-world physical consistency? To answer this question, we introduce AV-Phys Bench, the first comprehensive benchmark for evaluating physical commonsense in joint audio-video generation. AV-Phys Bench systematically tests joint audio-video generation models across three scene categories that probe how physical commonsense holds as the scene evolves: (a) Steady State, (b) Event Transition, and (c) Environment Transition. Each scene category investigates three physics-grounded subcategories that reflect real-world scenes, along with an additional Anti-AV-Physics subcategory, where prompts deliberately violate audio-visual physics to probe whether models possess generative physics knowledge or merely encode physically consistent priors. Each generation is scored along five dimensions: semantic adherence and physical commonsense within each modality, and cross-modal physical commonsense, which tests whether the visual and audio streams agree on the same physical event. Across three proprietary and four open-source models, Seedance 2.0 leads on physical commonsense, with an overall pass rate of 0.660. The gap to open-source models remains pronounced; every model degrades by up to 67% on event-driven and environment-driven transitions, and proprietary leaders collapse by 45–69% on Anti-AV-Physics prompts. Beyond human evaluation, we introduce AV-Phys Agent, a ReAct-style agentic evaluator that pairs a multimodal language model with deterministic acoustic measurement tools and ranks generators in close alignment with human ratings, enabling scalable physical-commonsense evaluation without further human annotation. AV-Phys Bench identifies cross-modal physical consistency and transition-driven scene dynamics as the open frontier for joint audio-video generation. We release AV-Phys Bench and AV-Phys Agent to facilitate future research on joint audio-video generation and evaluation.
Do Latent-CoT Models Think Step-by-Step? A Mechanistic Study on Sequential Reasoning Tasks
Jia Liang ⋅ Liangming Pan
Latent Chain-of-Thought aims to enable step-by-step computation without emitting long rationales, yet its internal mechanisms remain unclear. We study CODI, a continuous-thought teacher–student distillation model, on strictly sequential polynomial-iteration tasks with known intermediate states. Using logit-lens decoding, linear probes, attention analysis, and activation patching, we localize intermediate-state representations and trace how they are routed to the final readout. In short-horizon, low-hop tasks, CODI forms faithful bridge states across latent-thought positions, while the final input follows a separate near-direct route; predictions arise through late fusion at the answer readout. As task depth and difficulty increase, however, CODI does not reliably sustain a full latent rollout: it either compresses computation into a partial late-intermediate pathway or, in harder regimes, loses the latent reasoning signature altogether. To explain this transition, we show theoretically that the task’s algebraic structure controls its effective memory: compressible regimes support late-bottleneck reasoning, while incompressible regimes preserve full-history dependence and destabilize latent rollouts. Overall, our results characterize when CODI-style latent-CoT yields faithful iterative computation versus compressed or shortcut strategies.
Do multimodal models imagine electric sheep?
Santhosh Kumar Ramakrishnan ⋅ Carl Vondrick ⋅ Raja Giryes ⋅ Philipp Kraehenbuehl ⋅ Vladlen Koltun
Yes. We find that large multimodal models develop mental imagery when solving spatial puzzles, and they do imagine sheep when solving sheep puzzles. We fine- tune a Qwen3.5 VLM to solve twelve diverse visual reasoning tasks—including tangram, jigsaw, sokoban, 3D mental rotation, and rush hour—that require under- standing geometry, spatial constraints, and the consequences of actions. By simply predicting the open-loop sequence of actions to solve a puzzle from an initial state, we show that the model learns successfully, and that its hidden representations after each action encode meaningful visual information about the intermediate puzzle state. This finding suggests that an imperfect visual world model begins to form as a byproduct of learning to select correct actions in an open-loop fashion, in the absence of any explicit visual supervison. Building on this observation, we propose two ways to sharpen the mental images learned by the model through explicit visual supervision or explicit visual tokens. Across puzzles, we find that integrating as few as sixteen visual tokens into the chain of thought per board state improves the average solve rate from 83% to 89%, with gains exceeding 20 percentage points on reasoning-heavy games such as jigsaw and 3D mental rotation. Our results show that visual reasoning is a bottleneck, and that mental imagery may be a key mechanism for robust spatial cognition.
Do Robust LVLMs Hallucinate More? Uncovering Robustness-Induced Hallucination in Large Vision-Language Models
Md Zarif Hossain ⋅ Awal Ahmed Fime ⋅ Ahmed Imteaj
Robustness and accurate alignment with visual content are fundamental to the reliable deployment of large vision-language models (LVLMs). In this work, we uncover a previously overlooked trade-off: improving adversarial robustness can inadvertently increase hallucination in LVLMs. Through extensive evaluations on both open-ended generation and discriminative benchmarks, we reveal that adversarially trained LVLMs consistently produce outputs that are less aligned with the visual input, despite their improved robustness. To understand this trade-off, we analyze the visual token embeddings of robust encoders and find that adversarial training increases inter-token similarity by up to $38$\%. We refer to this phenomenon as spatial token homogenization. We further demonstrate that spatial token homogenization degrades visual information and amplifies decoder's reliance on language priors. Motivated by our findings, we propose Homogenization-Aware Latent Steering (HALS), a training-free inference-time method that steers decoder hidden states away from homogenization-induced hallucination without modifying the robust vision encoder. Extensive experiments across five hallucination benchmarks show that HALS consistently outperforms existing hallucination mitigation methods on robust LVLMs, reducing CHAIR$_S$ by $31.3$ points on average, improving POPE accuracy by $2.6$ points and achieving a $30.6\%$ reduction in hallucination on AMBER. Moreover, robustness evaluations confirm that HALS preserves adversarial performance, demonstrating that robust LVLMs can be made visually grounded without sacrificing their performance.
DRTriton: Large-Scale Synthetic Data Driven Reinforcement Learning for Triton Kernel Generation
Siqi Guo ⋅ Ming Lin ⋅ Tianbao Yang
Developing efficient CUDA kernels is a fundamental yet challenging task in the generative AI industry. Recent research leverages Large Language Models (LLMs) to automatically convert PyTorch reference implementations to CUDA kernels, significantly reducing engineering effort. State-of-the-art LLMs, such as GPT-5.2 and Claude-Sonnet-4.5, still struggle with this task. To address this challenge, we propose DRTriton, a scalable learning framework for training LLMs to convert PyTorch programs into highly optimized Triton kernels, which are then compiled to CUDA kernels at runtime. DRTriton consists of three key components: (i) a data synthetic algorithm CSP-DAG that guarantees full coverage and unbiased uniform sampling over the operator space with controlled difficulty; (ii) a curriculum RL framework with decoupled rewards that jointly optimizes conversion success rate and execution speed; and (iii) a test-time search algorithm that further improves the execution speed of the generated Triton kernels. With a warmup stage of SFT on limited PyTorch-Triton pairs curated using existing LLMs, DRTriton trained by RL on synthesized PyTorch programs generalizes effectively to real-world CUDA kernels that are challenging even for human experts. Experimental results show that DRTriton-7B achieves speedup over PyTorch on 92\% of KernelBench Level 2 tasks, compared to 23\% for GPT-5.2 and 19\% for Claude-Sonnet-4.5.
DUIL: Deep Unsupervised Inverse Learning for in situ Macromolecular Morphology Identification
Mostofa Rafid Uddin ⋅ Seonghui Min ⋅ Mahek Vora ⋅ Qifeng Wu ⋅ Muyuan Chen ⋅ Min Xu
Emerging microscopic technologies such as cryo-electron tomography (cryo-ET) provide direct 3D visualization of macromolecules within the cell, enabling analysis of their in situ morphology. This morphology can be regarded as an SE(3)-invariant, denoised volumetric representation of subvolumes extracted from tomograms, termed as subtomograms. Morphology identification from a set of subtomograms is formulated as an inverse problem of estimating a set of template morphologies and per-subtomogram SE(3) transformations with respect to any one of the templates. The existing expectation-maximization-based solution to this end often struggles with high structural heterogeneity and requires manual selection of a large number of hyperparameters. Addressing this issue, we present a novel deep unsupervised learning framework called DUIL. Given a set of subtomograms, DUIL first models their SE(3)-invariant morphological code using a siamese-like neural network with a multi-choice learning module. The learned morphological codes are clustered and used to generate a set of template morphologies through a generator network. The generated templates are used as references to estimate SE(3) transformations for each subtomograms through latent optimization. The subtomograms with identical template morphologies are then aligned and averaged to iteratively refine the templates. Experiments on simulated and real cryo-ET datasets demonstrate clear improvements over prior methods, including the discovery of previously unidentified macromolecular morphologies.
Dynamically Structured Diffusion Language Model Decoding via Bayesian Inference
Bian Sun ⋅ Kevin Zhai ⋅ Mubarak Shah ⋅ Zhenyi Wang
Diffusion language models (DLMs) have recently emerged as a promising alternative to autoregressive models, primarily due to their ability to enable parallel decoding. Despite this advantage, most existing DLMs rely on a fixed generation length specified prior to decoding, which restricts their flexibility in real-world applications. While a few recent works attempt to support flexible-length generation, they typically suffer from notable limitations: some require costly retraining to accommodate variable-length outputs, while others depend solely on local confidence signals during decoding. Such local criteria fail to capture the evolving structure of the sequence, often resulting in suboptimal generation quality. In this paper, we propose a training-free, Bayesian structured decoding framework that formulates flexible-length generation as a dynamic structural inference problem. Our approach learns the posterior inference over the dynamic block length, block formations and growth, and block decoding order within a unified Bayesian inference framework to jointly reason about how much to grow, where to grow, and how to organize content structurally. At each window expansion step, the method integrates local uncertainty with structural signals to (i) dynamically expand the sequence via adaptive length growth, (ii) infer block boundaries through Chinese Restaurant Process (CRP)-style partitioning, and (iii) allocate different number of decoding steps for different blocks and determine block decoding order via context-aware scheduling. This yields a unified mechanism that supports dynamic structured generation, including both flexible block expansion and block organization, while maintaining coherence. Extensive experiments across multiple benchmarks demonstrate that our approach significantly improves generation quality and flexibility over existing fixed-length and flexible-length baselines. These results highlight the advantage of Bayesian structured decoding for diffusion language model, providing a principled and efficient solution for structured text generation.
Dynamic k-center clustering with lifetimes
Simone Moretti ⋅ Paolo Pellizzoni ⋅ Andrea Pietracaprina ⋅ Geppino Pucci
The $k$-center problem is a fundamental clustering variant with applications in learning systems and data summarization. In several real-world scenarios, the dataset to be clustered is not static, but evolves over time, as new data points arrive and old ones become stale. To account for dynamicity, the $k$-center problem has been mainly studied under the sliding window setting, where only the $N$ most recent points are considered non-stale, or the fully dynamic setting, where arbitrary sequences of point arrivals and deletions without prior notice may occur. In this paper, we introduce the dynamic setting with lifetimes, which bridges the two aforementioned classical settings by still allowing arbitrary arrivals and deletions, but making the deletion time of each point known upon its arrival. Under this new setting, we devise a deterministic $(2+\varepsilon)$-approximation algorithm with $\widetilde{O}(k/\varepsilon)$ amortized update time and memory usage linear in the number of currently active points. Moreover, we develop a deterministic $(6+\varepsilon)$-approximation algorithm that, under ‘‘tame” update sequences, has $\widetilde{O}(k/\varepsilon)$ worst-case update time and heavily sublinear working memory.
Effective Multi-sensor Conditioning for Street-view Novel-view Synthesis
Zhengfei Kuang ⋅ Adam Sun ⋅ Liyuan Zhu ⋅ Tong Wu ⋅ Shengqu Cai ⋅ Jonathan Tremblay ⋅ Iro Armeni ⋅ Ehsan Adeli ⋅ Lior Yariv ⋅ Gordon Wetzstein
Modern vehicle platforms are equipped with a rich sensor suite, including LiDAR, calibrated multi-camera rigs, and accurate ego-motion, that in principle offers strong signal for re-rendering a driving scene from novel viewpoints. A growing line of recent work leverages video diffusion models for this task, using their generative priors to synthesize plausible novel views from sparse vehicle observations. In practice, however, existing methods exploit only a fragment of this signal, and their quality tends to degrade as the target trajectory departs from the recorded driving path. We argue that this is fundamentally a multi-sensor fusion problem: sparse LiDAR reprojections supply accurate but incomplete metric geometry, surround-view reference imagery supplies dense appearance but no metric depth, and camera poses tie the two together across views. We introduce StreetNVS, a video diffusion framework that jointly conditions on all three signals through a Reference-Enhanced Camera Attention module based on relative ray-level positional encoding, trained with a two-stage curriculum that gradually exposes the model to increasingly sparse LiDAR. On the Waymo Open Dataset, StreetNVS substantially outperforms state-of-the-art baselines under sparse LiDAR conditioning, matches methods that rely on 10–100× denser point clouds, and synthesizes coherent video along extreme out-of-trajectory paths such as elevation, lane-shift, pullback, and rotation.
Efficient Algorithms For Fully Dynamic Bipartite Matching In Metric Spaces
Pankaj Agarwal ⋅ Oliver Chubet ⋅ Sharath Raghvendra ⋅ Arian Zamani
We consider the problem of maintaining a minimum-cost bipartite matching between two point sets $A$ and $B$ in a metric space $(\mathbb{X},\mathsf{d})$ under insertions and deletions of input points. The Wasserstein-$p$ ($W_p$) cost of a matching $M$ is defined as $(\sum_{(a,b)\in M}\mathsf{d}(a,b)^p)^{1/p}$ and an $\alpha$-approximate matching is one whose total cost is at most $\alpha$ times the cost of a minimum-cost matching. We obtain two main results. If $A$ and $B$ are points in $\mathbb{R}^d$ and the distance between two points is measured under the $\ell_p$-metric, an $O(d\epsilon^{-3/2})$-approximate $W_1$-matching between $A$ and $B$ can be maintained with an amortized $O\big(n^\epsilon d\epsilon^{-3/2}\varphi(n,1/\sqrt{\epsilon})\big)$ update time, for any parameter $\epsilon\in(0,1]$, and where $\varphi(n,1/\sqrt{\epsilon})$ denotes the update time of a $\epsilon^{-1/2}$-approximate nearest neighbor data structure. For the $\ell_2$ norm this results in an update time of $O\big((d+ \epsilon^{-3/2}n^\epsilon)\log n\big)$. The current state-of-the-art for high-dimensional settings only focus on the $\ell_2$-metric and maintain an $O(\log n)$-approximate matching. Our result not only extends to any $\ell_p$ norm, but it also improves the approximation factor for $d=o(\log n)$ under the $\ell_2$-metric. Next, we consider the problem of maintaining a $W_p$-matching when $A$ and $B$ are point sets in an arbitrary finite metric space. We show that for any $k,p\geq 1$ and constant $\epsilon>0$, a $2k(1+\epsilon)$-approximate matching can be maintained with an amortized update time of $O(kn^{1+1/k}\epsilon^{-1}\log \Delta)$, where $\Delta$ is the spread of $A\cup B$. Prior work on finite metric spaces gave an insertion-only data structure for $W_1$-matching. In contrast, we develop a fully dynamic approach that supports both insertions and deletions and work for all $W_p$-matchings. Together, our results extend dynamic Wasserstein matching beyond fixed-dimensional $W_1$ settings: they handle high-dimensional geometric instances, extend prior insertion-only $1$-Wasserstein matching guarantees to the fully dynamic setting, and support $p$-Wasserstein costs for every integer $p\ge 1$ in arbitrary metric spaces.
Efficient LLM Adaptation with Forward-Only Passes
Baichuan Huang ⋅ Ananth Balashankar ⋅ Amir Aminifar
Large language model (LLM) inference serving is undergoing rapid growth and large-scale deployment, motivating us to rethink how the inference process itself can be leveraged to enable efficient task-specific LLM adaptation. In this paper, we propose a forward-only approach for efficient LLM adaptation with forward-only passes in LLM inference serving. We exploit the angle concentration of activations induced by each singular value decomposition (SVD) component to measure its contribution—dispersed or concentrated—to the angle concentration of the hidden states. Based on this, our forward-only search then efficiently identifies the weight matrix with the highest dispersion that merits rank reduction. We then selectively remove the higher-order components and retain the lower-order components in SVD. Empirical results across diverse datasets demonstrate the competitive accuracy of our forward-only approach, while theoretical analysis shows lower peak memory and greater speedup than the gradient-based approach, and greater speedup than the exhaustive search approach. The extended experiments further present the robustness and generalization of our forward-only approach to various LLMs with up to 57B parameters. The code is included in the supplementary material.
Elephant in the Fridge: Constant-Memory Frame Packing for Long Video Understanding
Shuo Gao ⋅ Chenhao Zheng ⋅ Jason Ren
Hour-long videos, streaming feeds, and movie-length content are pushing vision-language models (VLMs) past their breaking point—the standard recipe of encoding each frame into visual tokens yields sequences that grow linearly with video length, causing prohibitive memory consumption and inference latency. Existing approaches, such as token reduction and keyframe selection, attempt to shorten the token sequence but leave the $O(n)$ scaling intact, failing to resolve the fundamental bottleneck. We propose \model, \emph{a strikingly simple, training-free frame packing framework that compresses arbitrarily long videos into a fixed-size visual representation at constant memory cost.} \model requires no fine-tuning, no architectural modification, and no auxiliary models—it plugs directly into off-the-shelf VLMs at inference time, yet consistently surpasses more elaborate baselines. Drawing inspiration from FramePack in generation literature, we propose a new content-aware compression strategy that operates under a fixed token budget for visual understanding. Specifically, \model proceeds in two steps: (1) scoring each frame by its semantic similarity to the text prompt and ranking frames in a diversity-driven manner, and (2) packing the selected frames at varying resolutions into a fixed-length context window. This design concentrates the memory budget on frames that are both instruction-relevant and visually diverse. While in theory \model can pack arbitrarily many frames into the fixed budget, we identify an empirical instantiation that generalizes robustly across different settings. Extensive experiments on LongVideoBench, MLVU, and Video-MME show that \model consistently outperforms full-resolution baselines as well as prior token reduction and keyframe selection methods, across diverse model families, parameter scales, and frame budgets. Notably, on Qwen3.5-35B-A3B with a 128-frame budget, \model yields gains of \textbf{+12.9\%, +10.6\%, and +9.7\%} over the official model on the three benchmarks, respectively.
EMA-Nesterov: Stabilizing Nesterov's Lookahead for Accelerated Deep Learning Optimization
Chung-Yiu Yau ⋅ Dawei Li ⋅ Athanasios Glentis ⋅ Valentyn Boreiko ⋅ Hoi-To Wai ⋅ Mingyi Hong
Lookahead-based acceleration methods, such as Nesterov’s momentum, are widely used in optimization, but they often become unreliable in deep learning training due to stochastic gradient noise and non-convex loss landscapes. Standard lookahead relies on short-horizon update signals (e.g., differences between consecutive iterates), which are inherently noisy and can lead to unstable extrapolation directions. This work revisits Nesterov's acceleration from a trajectory perspective and argues that effective acceleration in deep learning should follow the low-frequency trend of optimization trajectories rather than extrapolating noisy one-step updates. Leveraging on this insight, we propose EMA-Nesterov, a simple modification that replaces the standard Nesterov's lookahead direction with an exponential moving average of parameter updates. This yields a stabilized lookahead direction that approximates long-horizon trajectory trends while retaining a lightweight single-loop implementation. We show that EMA-Nesterov retains the same theoretical accelerated convergence rate in convex problems. Furthermore, we show that EMA-Nesterov consistently improves optimization performance across a range of optimizers, including Adam, SOAP, and Muon, in deep learning tasks such as language model pre-training. Compared to prior lookahead methods, EMA-Nesterov achieves better performance by avoiding the instability of short-horizon lookahead and inefficiency of multi-step lookahead.
EpiPivot: Learning to Control the Simplex Method under Epistemic Uncertainty
Guantao Zhao ⋅ Mahdi Noorizadegan ⋅ Shihao Yang ⋅ Nicoleta Serban
The simplex method is one of the most widely used algorithms for linear programming, but its practical efficiency is highly sensitive to pivot selection and difficult to predict due to structural uncertainty in the search process. We propose EpiPivot, which casts pivot selection as a controllable decision process under epistemic uncertainty. EpiPivot identifies this uncertainty as two-dimensional: temporal dependence across the optimization trajectory and joint uncertainty across candidate pivot rules, and addresses both through temporal attention and an Epistemic Neural Network with shared latent sampling. At decision time, Thompson sampling combines these uncertainty-aware predictions into robust pivot choices. EpiPivot achieves significant improvements over classical and learning-based baselines, reducing pivot cost by up to 79\% over the best-performing classical rule on large-scale instances where most classical rules fail to converge within the time limit.
Epistemic Infrastructures of Science in AI Era Should Rebalance Costs of Generation and Verification
Jiaqi Ma
AI systems can now cheaply generate plausible scientific artifacts such as papers, reviews, and surveys. This has led to \emph{epistemic pollution} in our scientific systems, where unreliable but plausible-looking artifacts accumulate faster than the system can filter them out. The problem is structural: the epistemic infrastructure of science was calibrated to a world where producing a plausible artifact required substantial expertise, labor, and time, so generation cost itself served as a rough filter; AI weakens that filter without lowering verification cost. We argue that \textbf{AI-era science should rebalance the costs of generation and verification through a redesign of the epistemic infrastructure}. The current paper-centered system makes verification expensive: papers compress long-context scientific logic into prose, forcing reviewers, human or AI, to reconstruct underlying argument structure before they can evaluate it. To address this challenge, we propose \textbf{blueprints} as preliminary epistemic infrastructure: structured, decomposed research artifacts that represent claims, evidence, assumptions, and definitions as typed graph components. Blueprints trade an upfront generation cost for cheaper, more local, more distributed verification downstream. We have instantiated the proposal in a proof-of-concept prototype.
Flow models show promise for molecular design due to their fast, expressive sampling capabilities. However, their applicability to complex biological systems remains limited by a lack of physical grounding, which leads to unrealistic or unstable molecular structures. This work presents a framework that integrates force field guidance with consistency-based training to improve the physical fidelity of flow-based generative models. We calibrate pretrained flow models using differentiable physical energy functions to steer generation toward low-energy and sterically valid conformations. A consistency-based training strategy enables accurate, robust generation with very few sampling steps, improving inference efficiency. We evaluate it on multiple protein design tasks, including full-atom structure generation and peptide binder modeling. Experiments show that our approach consistently improves physical plausibility and geometric stability, while enabling favorable trade-offs between structural diversity and computational cost. By unifying physical calibration and efficient sampling, we advance the scalability and reliability of flow-based molecular generation.
Ergodic Trajectory Design by Learned Pushforward Maps: Provable Coverage via Conditional Flow Matching
Ehsan Aghazadeh ⋅ Masoud Malekzadeh ⋅ Ahmad Ghasemi ⋅ Hossein Pishro-Nik
Designing continuous trajectories whose time-averaged occupancy provably matches a prescribed spatial density (the *ergodic coverage* problem) is central to UAV-assisted data collection and sensing, robotic exploration, and mobile monitoring. For flying agents in particular, this challenge is acute: trajectories must balance coverage fidelity against tight energy budgets, no-fly zones, and acceleration limits. Existing methods either re-optimize each trajectory online (with cost growing in the horizon and re-running for every target, agent, and realization) or rely on bespoke analytical constructions that must be re-derived for each new constraint. We propose a *pushforward* framework that decouples ergodicity from density matching: an analytic latent trajectory provides exact uniform ergodicity on a simple annular domain, and a single map, learned offline by optimal-transport conditional flow matching, transports this latent occupancy onto the prescribed target density. The composed trajectory is then asymptotically ergodic with respect to the learned pushforward distribution, with deviation from the target controlled by the flow-matching training loss. Once trained for a given target density and constraint set, the map serves an unbounded number of trajectories and a multi-agent fleet without per-agent retraining, and many differentiable operational constraints (no-fly zones, acceleration ceilings, or fairness penalties) enter as additive soft penalties in the training loss without re-deriving the design. We prove three results (an acceleration-energy bound, an $O(1/\sqrt{K})$ ergodic convergence rate in the number of trajectory cycles $K$, and an approximation-error bound) that combine into an end-to-end coverage bound estimable from CFM training diagnostics (certified given an architectural Lipschitz bound on $v_\theta$). Experiments on synthetic targets empirically support each theoretical envelope; on a real UAV-coverage dataset, the proposed method gives the strongest observed coverage--energy and coverage--constraint tradeoffs among the evaluated time-warping, optimization, and concurrent flow-matching baselines.
Evaluating Depth and Breadth in Test-Time Scaling for Compositional Visual Generation
Shantanu Jaiswal ⋅ Mihir Prabhudesai ⋅ Nikash Bhardwaj ⋅ Zheyang Qin ⋅ Amir Zadeh ⋅ Chuan Li ⋅ Katerina Fragkiadaki ⋅ Deepak Pathak
Test-time scaling is increasingly used to improve visual generation, yet it remains unclear how different scaling strategies should be evaluated when they trade off accuracy, latency, throughput, compute cost, and visual quality in different ways. We study this question through a systematic comparison of prominent test-time strategies including sampler-depth scaling, breadth-oriented parallel sampling, step-by-step construction, iterative refinement, and hybrid breadth--depth for compositional text-to-image generation. Our results show that the preferred strategy depends on prompt complexity and cost assumptions: parallel sampling remains competitive for simpler prompts and high-throughput settings, while iterative refinement becomes increasingly useful as prompts require more object, spatial, numeric, and relational bindings. Surprisingly, step-by-step generation does not consistently inherit the benefits of step-by-step reasoning in language models, since early visual decisions about field of view, layout, scale, and resolution can constrain later edits. Across fixed budgets, hybrid policies often provide the strongest accuracy--cost tradeoff by combining parallel exploration with sequential correction. Finally, we show that refinement-based scaling is bottlenecked by verifier and editor reliability, and that adaptive routing can recover much of the benefit of fixed hybrid policies at lower average cost. Overall, our findings show that effective test-time scaling depends on matching the policy to the prompt and deployment bottleneck: breadth supports exploration and throughput, depth supports semantic repair, and hybrid/adaptive policies offer the strongest tradeoff when compositional correctness is the priority.
Everything at Every Scale: Scale-Invariant Diffusion with Continuous Super-Resolution
Jessie Chen ⋅ Zhuo Chen ⋅ Archer Wang ⋅ Jeff Gore ⋅ Bill Freeman ⋅ Congyue Deng ⋅ Marin Soljacic
Creating images from noise is image generation; reconstructing fine details from coarse inputs is super-resolution. Despite their practical differences, both can be understood as reversing information loss across scales. We introduce **SKILD**, a **S**cale-invariant **K**-Space **I**mage **L**earning **D**iffusion model that unifies generation and continuous super-resolution within a single unconditional framework. Both natural images and critical physical systems exhibit scale invariance, and we leverage it to design a forward process that attenuates image content from fine to coarse scales while injecting spectrum-matched Gaussian noise, making scale an explicit coordinate of the diffusion dynamics. The same trained reverse process performs generation and continuous super-resolution by varying only the starting timestep: *no task-specific architecture, no conditioning branch, no classifier-free guidance, no retraining per scale factor*. Empirically, SKILD reaches FID $2.65$ and Inception Score $9.63$ on unconditional CIFAR-10, performs $2\times$–$8\times$ super-resolution on ImageNet from a single unconditional checkpoint while outperforming conditional models across perceptual metrics, and reconstructs critical Ising models whose connected four-point correlations closely track the ground truth.
Exact Unlearning via Quantized Sufficient Statistics
Ami Tavory ⋅ Shripad Gade ⋅ Tal Sarig ⋅ Noam Touitou ⋅ Ido Guy
Exact machine unlearning guarantees that after deleting a user's data, the model produces the same predictions as if it had never seen that data in the first place. SISA, the current state-of-the-art approach, partitions data into disjoint shards, with necessary $O(n/S)$ retraining cycle for each deletion, and it cannot lower this cost through redundancy, because overlapping shards only multiply the damage.We introduce Quantized Sufficient Statistics (QSS), a non-parametric framework that pairs frozen prediction heads (the schema, trained on a small random subset $\mathcal{D}^{\circ}$) with mutable sum-decomposable accumulators indexed by Residual Quantization codes over the complementary data (the content, $\mathcal{D} \setminus \mathcal{D}^{\circ}$). With probability $1{-}\rho$ (where $\rho = |\mathcal{D}^{\circ}|/n$, typically $\leq 1\%$), deletion reduces to a constant-time arithmetic update independent of dataset size $n$; with probability $\rho$, a full rebuild is required. Maintaining $p$ independent schemas suppresses the synchronous rebuild probability to $\rho^p$, and because every schema aggregates all data, decommissioning incurs zero accuracy loss. Across 15 datasets ($n \geq 50$K) spanning vision, text, and tabular modalities at $\rho=0.5\%$, QSS matches or exceeds SISA accuracy on 5 datasets, trails by $\leq 2$ pp on 5 more, and by 3–11 pp on 3 datasets where high class count or large rebuild cost limits performance, while delivering 3–645$\times$ faster median expected deletion (e.g., 0.2 s expected vs. 109 s on Jigsaw, $n=1.4$M).
Exploiting Textual Semantics for Robust Cross-View Object Correspondence
Bing Fan ⋅ Yunhe Feng ⋅ Yan Huang ⋅ Heng Fan
Cross-view object correspondence (CVOC) aims to establish associations of the same target between query and search videos captured from different viewpoints. Existing methods often rely on visual cues for CVOC. Despite recent progress, these methods struggle in complicated scenarios with substantial viewpoint changes and appearance variations, due to lacking sufficient target information. Addressing this, we introduce TeSCo, a novel framework that exploits rich Textual Semantics of an object, in addition to its visual cues, for cross-view object Correspondence. Our key insight is, textual description of a target, by capturing diverse attributes such as category, texture, and color, provides viewpoint- and appearance-invariant semantics, which are complementary to visual cues and can hence enhance correspondence robustness in complicated scenes. Inspired by this, TeSCo first generates a textual expression of the target from the given query view using a vision-language model, and then extracts textual feature to enhance visual features for localization in the search view. To realize this, we introduce a simple yet effective text-conditioned cross-modal fusion (TCF) module that incorporates the textual feature into visual features with text-guided modulation, producing more robust multimodal target representation for object correspondence. Since not all textual cues are equally compatible with the target in current search-view frame, we propose an iterative textual feature refinement (ITFR) module that progressively adjusts textual feature using search-view information before the TCF module, enabling search-view-aware textual semantics to be fused into visual features and leading to better performance. In extensive experiments on Ego-Exo4D and HANDAL-X, TeSCo demonstrates state-of-the-art results and largely outperforms other models, validating its efficacy. Our code and model as well as results will be released.
Fast Accurate Quantum Monte Carlo without Metropolis Adjustment
Reuben Cohn-Gordon ⋅ Gabriel Pescia ⋅ Sumner N Hearth ⋅ Jakob Robnik ⋅ Uros Seljak ⋅ Peter Lunts
In quantum systems, physical quantities of interest can often be expressed as expectation values of a probability distribution, which allows their estimation by Markov Chain Monte Carlo (MCMC) methods. This approach, an instance of Quantum Monte Carlo (QMC), plays a central role in obtaining predictions of system properties relevant to high energy or condensed matter physics. The use of Hamiltonian dynamics to design a Markov kernel, known as Hybrid or Hamiltonian Monte Carlo (HMC), is widely used in quantum applications. In this context, it is standard to use an HMC kernel that is ``adjusted'' with the Metropolis-Hastings (MH) criterion, so that estimates of expectations converge to their true value in the limit of infinite sample size. However, recent work in computational statistics suggests that an \emph{unadjusted} HMC kernel can be significantly more efficient, while maintaining an asymptotic bias which is small relative to the error arising from the variance of the finite sample size. We adapt this approach to the QMC setting, focusing on a challenging and high-dimensional \emph{spin-fermion} model of a quantum phase transition. We find that unadjusted methods outperform adjusted HMC in terms of effective sample size per gradient call by around an order of magnitude, while retaining accurate results.
Fast Diverse Nearest Neighbor Search
Justin Chen ⋅ Soham Nagawanshi ⋅ Shenghao Xie ⋅ Haike Xu ⋅ Alan Zhou ⋅ Samson Zhou
In the $k$-diverse nearest neighbor search problem, the input is a dataset in which each point is assigned a color, and given a query $q$, the goal is to retrieve $k$ approximate nearest neighbors with distinct colors. This color diversity metric is highly essential for information retrieval tasks where results are required to have different categories, e.g., recommending products from different sellers. Previous state-of-the-art solution by Anand et al. [ICML 2025] constructs a diversity-aware graph to meet this requirement. However, they suffer from an $\mathcal{O}(k^2)$ multiplicative query time overhead, creating a computational bottleneck when $k$ is large. To break this barrier, we propose a novel color bucketing framework that selects a subset of colors in each bucket and instantiates an independent approximate nearest neighbor search algorithm on the corresponding points. Inspired by group testing, we provide a randomized color sampling scheme that achieves an $\mathcal{O}\left(k^{1-\frac{1}{c^2}-o(1)}\log k\right)$ overhead in Euclidean spaces and an $\mathcal{O}\left(k \log k\right)$ overhead in general metric spaces, where $c$ is the approximation factor, reducing a factor of $k$. In addition, the space usage to store the data structure matches or improves upon prior methods. Empirical results on semi-synthetic and real-world datasets demonstrate that our approach achieves significantly faster search times and higher recall compared to state-of-the-art diversity search baselines. Furthermore, we introduce a dataset-oblivious deterministic bucketing scheme using expander graphs for a relaxed diverse search problem that only requires $k(1-\varepsilon)$ colors. Here, dataset-oblivious means that the color bucket construction does not depend on the spatial configuration of the dataset. We then establish an $\Omega(k^2)$ lower bound on the number of buckets for any dataset-oblivious deterministic bucketing scheme that gives an \emph{exact} $k$-diverse solution. We subsequently circumvent this by a dataset-aware adaptive segment tree bucketing scheme with an overhead of only $\mathcal{O}(k \log N)$, where $N$ is the number of colors. As an extension of our results, we solve the problem with general diversity metric, where the goal is to maximize the minimum pair-wise distance of the $k$ solutions, and improve the query time.
FASTER: Value-Guided Sampling for Fast RL
Perry Dong ⋅ Alexander Swerdlow ⋅ Dorsa Sadigh ⋅ Chelsea Finn
Some of the most performant reinforcement learning algorithms today can be prohibitively expensive as they use test-time scaling methods such as sampling multiple action candidates and selecting the best one. In this work, we propose FASTER, a method for getting the benefits of sampling-based test-time scaling of diffusion-based policies without the computational cost by tracing the performance gain of action samples back to earlier in the denoising process. Our key insight is that we can model the denoising of multiple action candidates and selecting the best one as a Markov Decision Process (MDP) where the goal is to progressively filter action candidates before denoising is complete. With this MDP, we can learn a policy and value function in the denoising space that predicts the downstream value of action candidates in the denoising process and filters them while maximizing returns. The result is a method that is lightweight and can be plugged into existing generative RL algorithms. Across challenging long-horizon manipulation tasks in online and batch-online RL, FASTER consistently improves the underlying policies and achieves the best overall performance among the compared methods. Applied to a pretrained VLA, FASTER further improves task success while substantially reducing training and inference compute requirements.
Coresets are widely used to compress large datasets into small weighted summaries. We mainly focus on the $k$-means objective where the cost is defined to be the sum of squared distances of every point to its closest center. A coreset approximately preserves the cost of every candidate set of $k$ centers up to a small $(1\pm \varepsilon)$ multiplicative error. By far the most flexible and powerful technique in this line of work is sensitivity sampling, where we pick points proportionate to their highest relative cost contribution in any solution. In general, the transmission and storage of these coresets are assumed to be reliable and always keep the coreset intact, without accounting for the possibility of corruptions. This raises a basic question: To what extent can coresets be made fault-tolerant? We study an adversarial fault model in which up to $f$ points of the coreset may be arbitrarily corrupted, including their weights, and the goal is to recover a valid coreset from the corrupted summary. Our main result shows that sensitivity sampling yields fault-tolerant coresets of size $O(f\cdot k/\varepsilon + m)$, where $m$ is the size of a non-fault-tolerant coreset computed via sensitivity sampling. This result is also optimal in that any fault-tolerant $k$-means coreset must have size $\Omega(f \cdot k/\varepsilon)$. The decoding algorithm computing a sanitized coreset from a corrupted one is efficient and we demonstrate practical viability via our experiments.
FiedlerPrune: Connectivity-Preserving Cross-Layer Pruning for Large Language Models
Zijun Sun ⋅ Yanning Shen
Large language models (LLMs) have achieved remarkable success across diverse tasks, yet their ever-growing model sizes impose significant computational and memory costs that hinder practical deployment. Pruning addresses this by introducing sparsity into weight matrices, but existing layer-wise pruning methods operate independently on each linear layer, ignoring cross-layer dependencies and yielding globally suboptimal masks. End-to-end pruning methods address this limitation but incur prohibitive computational overhead. In this work, we propose FiedlerPrune, a pruning framework that achieves a better balance between the two paradigms by incorporating cross-layer dependencies. Guided by graph theory, FiedlerPrune constructs weighted multipartite graphs over consecutive linear layers within each Transformer block, and derives an inter-layer importance score from each weight's contribution to the Fiedler Value of the corresponding graph. Combined with any intra-layer metric, FiedlerPrune provides a unified and versatile pruning criterion reflecting both local quantitative importance and cross-layer connectivity-preserving importance . Extensive experiments demonstrate that FiedlerPrune consistently improves over layer-wise baselines, and matches or outperforms end-to-end methods at orders-of-magnitude lower pruning cost. We further demonstrate FiedlerPrune's practical utility through inference speedup, compatibility with quantization, and post-pruning fine-tuning.
FILOsofer: A TEE-Shielded Model Partitioning Framework based on Fisher Information-Guided LoRA Obfuscation
Fan zhang ⋅ Ziqi Zhang ⋅ Hossein Khalili ⋅ Neiro Cabrera ⋅ Jonathan Xue ⋅ Nader Sehatbakhsh
On-device machine learning exposes deep neural networks as white-box artifacts, making them vulnerable to model-stealing attacks. Trusted Execution Environments (TEEs) mitigate this risk by isolating model execution, but running entire models inside TEEs incurs prohibitive overhead. To balance security and efficiency, prior work proposes TEE-Shielded DNN Partitioning (TSDP), which executes privacy-insensitive components on GPUs while confining sensitive layers to TEEs. We demonstrate that existing TSDP schemes remain vulnerable because exposed GPU weights provide an effective warm start. This allows adversaries to exploit inevitable information leakage and reconstruct high-fidelity surrogates using only a fraction of the training data. To address this vulnerability, we propose FILOsofer, a principled defense that strategically obfuscates exposed weights using Fisher Information. By deliberately rendering leaked weights misleading, FILOsofer steers an adversary’s initialization away from the true optimum. To recover user-side accuracy, we introduce a novel cross-layer LoRA mechanism that efficiently restores performance while storing only lightweight LoRA parameters inside the TEE. Extensive evaluation in real-world settings shows that FILOsofer achieves black-box–equivalent security in the worst case, while reducing computational overhead by more than $50\times$ compared to prior approaches.
Exact optimal-decision recovery can be stronger than required when decisions are evaluated at a finite regret tolerance. This paper studies finite-resolution sufficiency under partial linear observations and bounded measurement error. A design is sufficient when every noisy observation fiber admits a single feasible decision with regret at most a prescribed tolerance for all costs in that fiber. We prove a complete finite certificate for insufficiency: an indistinguishable hard tuple of costs with no common low-regret decision. For linear-optimization regret, the required tuple size is controlled by projected cost dimension after quotienting directions that are invisible to regret. For finite cost libraries, this certificate gives exact fixed-design verification and separation. Under coordinatewise noise and a finite query library, query design is exactly set cover over hard tuples; this reduction transfers the standard set-cover greedy guarantee and hardness barrier, and supports an exact delayed-constraint method under exact verification and exact restricted-master solves. Structured cases reduce to polynomial formulations through separability, nested one-dimensional coverage, and interval incidence.
Finite Time Analysis of Risk-Sensitive RL via Noisy Power Iteration
Waqar Mirza ⋅ Yashaswini Murthy ⋅ Laixi Shi ⋅ Eric Mazumdar ⋅ Adam Wierman
Estimating the principal eigenpair of a positive operator from stochastic evaluations gives rise to a noisy form of normalized power iteration: each step applies a sampled operator estimate and then renormalizes. We establish finite-time stochastic-approximation guarantees for this procedure, working in Hilbert's projective metric, which is well-suited to the multiplicative geometry of Perron--Frobenius eigenproblems. Our main application is risk-sensitive average-cost reinforcement learning (RL) with exponential utility. In this setting the Bellman equations are multiplicative, and value functions are characterized by nonlinear eigenvalue problems rather than additive fixed points. We cast both policy evaluation and control in this framework, obtaining risk-sensitive TD- and Q-learning algorithms that learn from a single Markovian trajectory. Under explicit positivity, mixing, and linear function approximation assumptions, we prove finite-time bounds on the recovered eigenvector and eigenvalue with $\tilde{O}(\epsilon^{-2})$ sample complexity up to problem-dependent constants. The results cover both tabular and linear function approximation regimes, and through the duality between exponential utility and KL-robust control yield finite-time guarantees for KL-robust average-cost RL as well.
Flash-KMeans: Fast and Memory-Efficient Exact K-Means
Shuo Yang ⋅ Haocheng Xi ⋅ Yilong Zhao ⋅ Muyang Li ⋅ Xiaoze Fan ⋅ Jintao Zhang ⋅ Han Cai ⋅ Yujun Lin ⋅ Xiuyu Li ⋅ Kurt Keutzer ⋅ Song Han ⋅ Chenfeng Xu ⋅ Ion Stoica
k-means has historically been positioned primarily as an offline processing primitive, typically used for dataset organization or embedding preprocessing rather than as a first-class component in online systems. In this work, we revisit this classical algorithm under the lens of modern AI system design and enable k-means as an online primitive. We point out that existing GPU implementations of k-means remain fundamentally bottlenecked by low-level system constraints rather than theoretical algorithmic complexity. Specifically, the assignment stage suffers from a severe IO bottleneck due to the massive explicit materialization of the N × K distance matrix in High Bandwidth Memory (HBM). Simultaneously, the centroid update stage is heavily penalized by hardware-level atomic write contention caused by irregular, scatter-style token aggregations. To bridge this performance gap, we propose Flash-KMeans, an IO-aware and contention-free k-means implementation for modern GPU workloads. Flash-KMeans introduces two core kernel-level innovations: (1) FlashAssign, which fuses distance computation with an online argmin to completely bypass intermediate memory materialization; (2) Sort-Inverse Update, which explicitly constructs an inverse mapping to transform high-contention atomic scatters into high-bandwidth, segment-level localized reductions. Furthermore, we integrate algorithm-system co-designs, including chunked stream overlap and cache-aware compile heuristic, to ensure practical deployability. Extensive evaluations on NVIDIA H200 GPUs demonstrate that Flash-KMeans achieves up to 17.9× end-to-end speedup over best baselines. At the kernel level, FlashAssign and Sort-Inverse Update deliver up to 21.2× and 6.3× speedups. By systematically restructuring execution around underlying hardware constraints, Flash-KMeans delivers mathematically exact, scalable, and highly deployable acceleration across diverse AI workloads.
Flow Map Denoisers: Traversing the Distortion-Perception Plane for Inverse Problems
Nicolas Zilberstein ⋅ Morteza Mardani ⋅ Santiago Segarra
Image restoration faces a fundamental tradeoff: methods that minimize error produce blurry reconstructions, while those that maximize perceptual quality yield sharp but less faithful images. Existing approaches either commit to a single operating point on this distortion–perception (DP) frontier or require retraining, auxiliary models, or changes in discretization to access different points. We show that flow map models, a recent extension of flow matching for few-step sampling that learns an average field, implicitly define a one-parameter family of denoisers that continuously spans the DP frontier. The parameter, the lookahead $t$, acts as a knob: varying it traces a smooth path from the MMSE estimator to a perceptually aligned one. For Gaussian targets, we prove that this path recovers the optimal DP frontier exactly; for natural images, we demonstrate empirically that it closely follows the same behavior. Embedded within a Plug-and-Play solver, a single trained flow map matches or exceeds specialized baselines at both ends of the DP spectrum and uniquely traces a continuous curve in between without retraining, paired data, or auxiliary networks. Extensive experiments on CelebA ($128\times 128$) and AFHQ ($256\times 256$) across several linear and nonlinear inverse tasks validate our findings.
Flow Mismatching: Unsupervised Anomaly Detection via Velocity Discrepancies in Flow Matching Models
Shengzhe Chen ⋅ Mehrdad Moradi ⋅ Kamran Paynabar ⋅ Hao Yan
We propose Flow Mismatching, an unsupervised anomaly detection method that deliberately avoids reconstruction-based paradigms. Instead, we treat flow matching as geometric dynamics and leverage a key insight: anomalies occur at places where the learned normal flow disagrees with the geometric path toward a test image. Given a flow matching model trained only on normal images, we probe its learned velocity field along affine paths from Gaussian noise to a target image. Along each path, we compare the model-predicted velocity, which follows normal generative dynamics, with the geometric velocity toward the target, which includes any anomalous content. Anomalies induce strong local disagreement between these velocities. Aggregating the mismatch over different time steps and multiple paths yields pixel-wise heatmaps and image-level scores without test-time optimization, feature memories, or additional calibration. Our analysis shows that the population mismatch decomposes into an irreducible denoising term and a Fisher-divergence term between the test-path and normal-path score functions, which identifies the score-gap component that drives anomaly separation and explains the effectiveness of robust path aggregation. Extensive experiments on MVTec-AD and VisA demonstrate superior performance compared with SOTA reconstruction-based and recent flow matching-based approaches.
FlyAOC: Evaluating Agentic Ontology Curation of Drosophila Scientific Knowledge Bases
Xingjian Zhang ⋅ Sophia Moylan ⋅ Ziyang Xiong ⋅ Qiaozhu Mei ⋅ Yichen Luo ⋅ Jiaqi Ma
Scientific knowledge bases accelerate discovery by curating findings from primary literature into structured, queryable formats for both human researchers and emerging AI systems. Maintaining these resources requires expert curators to search papers, reconcile evidence across documents, and produce ontology-grounded annotations. Existing benchmarks usually evaluate isolated subtasks, such as named entity recognition or relation extraction, and therefore do not capture this end-to-end workflow. We present FlyAOC to evaluate AI agents on end-to-end agentic ontology curation from scientific literature. Given a gene symbol, a concise FlyBase gene description, access to a 16,898-paper corpus, and ontology resources, agents must search for evidence and recover as many curator-relevant structured annotations as possible. Outputs span standardized function terms, expression patterns, and historical synonyms linking decades of nomenclature. The benchmark includes 7,397 expert-curated annotations across 100 genes drawn from FlyBase, the Drosophila knowledge base. Across four baseline agent harnesses--memorization, fixed pipeline, single-agent, and multi-agent--FlyAOC is sensitive to harness design, model family, and tool-use reliability. These results reveal system-level failure modes that model-only evaluations do not capture. FlyAOC provides a reproducible testbed for retrieval-augmented scientific curation. - Anonymous code: https://anonymous.4open.science/r/flyaoc-0562/ - Anonymous data: https://huggingface.co/datasets/anonymous-042/flyaoc
FOCUS: Benchmarking Retinal Model Generalization from Foundation Vision Encoders to Multimodal LLMs
David Restrepo ⋅ Chenwei Wu ⋅ Luis Nakayama ⋅ Miguel Martins ⋅ Stergios Christodoulidis ⋅ Maria Vakalopoulou ⋅ Enzo Ferrante
Progress in AI-based retinal image analysis has accelerated with the adoption of foundation models, yet evaluating their real-world reliability remains challenging. Performance reported on a single dataset does not capture how models behave under dataset shift, across clinical definitions, or for different patient subgroups. This limitation is particularly critical in in medical imaging analysis, where robustness, calibration, and fairness are essential for safe deployment. We introduce FOCUS (Foundation Ophthalmic Cross-Dataset Understanding under Shift), a cross-dataset benchmark for evaluating retinal fundus models that considers vision-only encoder models (VM), vision-language dual-encoder models (VLM), and multimodal large language models (MLLM). FOCUS harmonizes binary diabetic retinopathy, referable diabetic retinopathy, and glaucomatous optic neuropathy tasks across ten public datasets spanning diverse geographies, acquisition conditions, and label protocols. The benchmark evaluates models through a unified analysis layer that measures ranking performance, calibration, subgroup disparities, and image-quality robustness. We present a large-scale evaluation covering 532 base configurations and 228 low-rank adaptation LoRA-adapted MLLMs trained with supervised fine-tuning (SFT). Results show that no model family consistently dominates across tasks and datasets: general VM encoders achieve the strongest average ranking performance, medical MLLMs are competitive but variable, and dual encoder VLMs benefit substantially from lightweight adaptation. Fine-tuning improves in-domain performance but exhibits heterogeneous transfer to external datasets, particularly in calibration. These findings demonstrate that retinal model evaluation is inherently multidimensional. FOCUS provides a practical framework and public benchmark to assess generalization, reliability, and robustness beyond single-dataset leaderboards.
ForceBody: Force-Paired Parametric Body Motion with Torque Uncertainty
Joonwoo Kwon ⋅ Yufei Zhang ⋅ Xiaoming Liu ⋅ Zijun Cui
Forces and torques drive human motion, central to biomechanics, robotics, and physics-aware animation, yet they are often absent from learning-based motion pipelines for body reconstruction and generation. Some motion datasets provide force annotations, but the paired motion sequences are incompatible with the parametric body models used in modern learning pipelines. In addition, existing datasets typically obtain joint torques through inverse dynamics, which is inherently sensitive to the quality of the input kinematics; however, they do not quantify the reliability of these torque estimates. We close this gap with \textbf{ForceBody}, the first dataset to bring ground truth force supervision into a parametric body representation, shipped with per-sample torque uncertainty. ForceBody pairs the SKEL body model with ground reaction forces and inverse-dynamics joint torques across $10{,}389$ motion trials ($9.7$M frames, $27$ hours) from $140$ subjects. Each torque label is paired with a per-frame, per-joint uncertainty annotation obtained by Monte Carlo sampling through the inverse dynamics pipeline. We benchmark six architectures (MLP, Conv1D, LSTM, GRU, Mamba2, Transformer) on ground reaction force and joint torque prediction from SKEL motion. As one example use of the released uncertainty, finetuning a Transformer with per-sample uncertainty weighting reduces the MAE of joint torque estimation by $12\%$.
From Matrix Inversion to Constraints: Provably Tighter Confidence Regions for Importance Weights in Label Shift
Mushan Li ⋅ Kihyun Han ⋅ Yanyuan Ma
Importance weights are essential in domain adaptation under label shift, yet their utility is often undermined by the finite sample uncertainty associated with their estimation. Existing methods typically analyze this uncertainty through Gaussian elimination on interval-valued linear systems, which leads to overly conservative confidence regions and inefficient downstream applications. We propose a paradigm shift from inversion-based inference to a direct matrix constraint framework. We use this framework to define a joint confidence region and extract marginal intervals via linear programming, deriving provably tighter bounds for importance weights while maintaining exact finite-sample validity. Furthermore, we analyze the confidence region's geometry and provide the theoretical results for its diameter bounds. Evaluated across text, image, multimodal benchmarks, including AGNews, MNIST, CIFAR-10, N24News, and a real-world autonomous driving dataset, nuImages, our approach consistently yields shorter confidence intervals and smaller prediction sets than inversion-based methods.
FrontierOR: Benchmarking LLMs' Capacity for Efficient Algorithm Design in Large-Scale Optimization
Minwei Kong ⋅ Chonghe Jiang ⋅ Ao Qu ⋅ Wenbin Ouyang ⋅ Zhaoming Zeng ⋅ Xiaotong Guo ⋅ Zhekai Li ⋅ Junyi Li ⋅ Yi Fan ⋅ Xinshou Zheng ⋅ Xi Jing ⋅ Yikai Zhang ⋅ Zhiwei Liang ⋅ Seonghoo Kim ⋅ Runqing Yang ⋅ Sirui Li ⋅ Han Zheng ⋅ Wangyang Ying ⋅ Ou Zheng ⋅ Chonghuan Wang ⋅ Jinglong Zhao ⋅ Paul Liang ⋅ Jinhua Zhao ⋅ Hai Wang
Large language models (LLMs) are increasingly used for optimization modeling and solver-code generation, yet practical operations research often requires a harder capability: designing scalable algorithms that exploit problem structure and outperform direct formulation-and-solve baselines. Existing benchmarks are limited to small or simplified examples far below real-world scale and complexity. We introduce FrontierOR, the first large-scale benchmark targeting LLM-based efficient algorithm design for realistic optimization problems. FrontierOR includes 110 tasks derived from methodologically diverse papers published in top-tier operations research venues, each with standardized instances and a hidden, human-verified evaluation suite. We evaluate seven frontier LLMs in one-shot and test-time evolution settings. The results reveal that frontier models still struggle to move from executable formulations to efficient optimization algorithms: the strongest one-shot model outperforms Gurobi in only 39\% of cases in terms of both solution quality and runtime, and even strong coding agents with test-time evolution achieve only 50\% on selected hard tasks. FrontierOR establishes a practical evaluation platform for LLM-based optimization algorithm design, which enables future LLMs and agents to be systematically tested on whether they can move beyond correct formulation toward feasible, high-quality, and runtime-competitive algorithms.
Frontier Task Synthesis Via Solution-Centric Evolution
Yangzhen Wu ⋅ Aaron Li ⋅ Wenjie Ma ⋅ Li Cao ⋅ Ziheng Zhou ⋅ Mert Cemri ⋅ Shu Liu ⋅ Yuran Xiu ⋅ Chenxiao Yan ⋅ Haikun Zhao ⋅ Bin Yu ⋅ Ion Stoica ⋅ Dawn Song
The rapid progress of frontier large language models has led to widespread benchmark saturation, limiting the ability of existing datasets to differentiate model capabilities or provide useful training signal. For instance, on LiveCodeBench, frontier models achieve over (99%) Pass@1 on easy splits and exceed (90%) Pass@1 on average across difficulty levels. Constructing new, sufficiently challenging datasets typically requires substantial human effort, creating a bottleneck for continued progress. We study a solution-centric evolutionary approach that automatically transforms existing programming problems into substantially harder variants. Rather than generating problems from scratch, the approach evolves reference solutions through structured transformations and derives corresponding problem statements and tests from the evolved solutions. This design grounds generation in executable semantics, enabling scalable construction of high-quality, diverse, and difficult tasks with verifiable correctness. Applied to LiveCodeBench and SciCode, it produces evolved tasks that are substantially more difficult while preserving validity, reference correctness, and diversity. Importantly, these tasks remain challenging even for the model that generates them, creating the prerequisite for self-improvement rather than merely expanding an evaluation set. We further show that RL on evolved tasks improves held-out coding performance: for \texttt{gpt-oss-20b}, seed+evolved training achieves (+8.7) and (+8.3) Pass@1 gains on LCB v6 Hard and LCB-Pro Easy, exceeding seed-only gains by (70.7%) and (34.8%), respectively. This closes the loop from self-generated challenges to capability improvement, demonstrating that saturated benchmarks can be converted into both stronger evaluations and reusable training signal.
FuRA: Full-Rank Parameter-Efficient Fine-Tuning with Spectral Preconditioning
Yequan Zhao ⋅ Ruijie (Ray) Zhang ⋅ Liyan Tan ⋅ Niall Moran ⋅ Tong Qin ⋅ Zheng Zhang
Both full fine-tuning (Full FT) and parameter-efficient methods like LoRA add weight updates without regard to the spectral structure that pretraining has established. This allows noisy gradients from a small fine-tuning distribution to freely perturb the robust features learned through pretraining. We first identify *spectral preconditioning* as the key missing ingredient: reparameterizing each weight $\mathbf{W}$ through its full-rank SVD and freezing one singular basis confines every update to the pretrained column space, yielding a preconditioned optimizer that outperforms unconstrained Full FT at the same parameter count. To make this insight practical, we propose FuRA (**Fu**ll-**R**ank **A**daptation), which factorizes $\mathbf{W}$ via a block tensor-train decomposition $\mathbf{W}=\mathbf{L}\mathbf{S}\mathbf{R}$: the large core $\mathbf{L}$ is frozen at the pretrained block-wise SVD basis while only the small core $\mathbf{R}$ and per-block singular values $\mathbf{S}$ are trained. This single design choice simultaneously delivers full-rank spectral preconditioning, full-rank update capacity, and parameter, step time, memory efficiency on par with LoRA. FuRA outperforms Full FT on LLM fine-tuning ($+1.37$ on LLaMA-3-8B commonsense reasoning), LLM math reinforcement learning, and VLM visual instruction tuning. The 4-bit quantized version QFuRA also outperforms QLoRA.
GauS: Differentiable Scheduling Optimization via Gaussian Reparameterization
Yaohui Cai ⋅ Vesal Bakhtazad ⋅ CUNXI YU ⋅ Zhiru Zhang
Efficient operator scheduling is a fundamental challenge in software compilation and hardware synthesis. While recent differentiable approaches have sought to replace traditional ones like exact solvers or heuristics with gradient-based search, they typically rely on categorical distributions that fail to capture the ordinal nature of time and suffer from a parameter space that scales poorly. In this paper, we propose a novel differentiable framework, GauS, that models operator scheduling as a stochastic relaxation using Gaussian distributions, which fully utilize modern parallel computing devices like GPUs. By representing schedules as continuous Gaussian variables, we successfully capture the ordinal nature of time and reduce the optimization space by orders of magnitude. Our method is highly flexible to represent various objectives and constraints, which provides the first differentiable formulation for the complex pipelined scheduling problem. We evaluate our method on a range of benchmarks, demonstrating that GauS achieves Pareto-optimal results.
GenEnv: Difficulty-Aligned Co-Evolution Between LLM Agents and Environment Simulators
Jiacheng Guo ⋅ Ling Yang ⋅ Peter Chen ⋅ Qixin Xiao ⋅ Yinjie Wang ⋅ Xinzhe Juan ⋅ Ke Shen ⋅ Mengdi Wang
Training capable Large Language Model (LLM) agents is critically bottlenecked by the high cost and static nature of real-world interaction data. We address this by introducing GenEnv, a framework that establishes a difficulty-aligned co-evolutionary game between an agent and a scalable, generative environment simulator. Unlike traditional methods that evolve models on static datasets, GenEnv instantiates a dataevolving: the simulator acts as a dynamic curriculum policy, continuously generating tasks specifically tailored to the agent's ``zone of proximal development''. This process is guided by a simple but effective -Curriculum Reward, which aligns task difficulty with the agent's current capabilities. We evaluate \autoenv on five benchmarks, including API-Bank, ALFWorld, BFCL, Bamboogle, and TravelPlanner. Across these tasks, GenEnv improves agent performance by up to 40.3% over 7B baselines and matches or exceeds the average performance of larger models. Compared to Gemini 2.5 Pro-based offline data augmentation, \autoenv achieves better performance while using 3.3 less data. By shifting from static supervision to adaptive simulation, \autoenv provides a data-efficient pathway for scaling agent capabilities.
Generative OOD-regularized Model-based Policy Optimization
Aysin Tumay ⋅ Jiahe Huang ⋅ Elise Jortberg ⋅ Rose Yu
We study sequential decision-making with offline reinforcement learning (RL). Traditional offline RL policies may result in out-of-distribution (OOD) actions when training relies only on sparse offline representations. To ensure safe offline policies in a sparse state-action space, we explore how density estimation models can be integrated into model-based RL methods to avoid the OOD regions. Generative models are capable of explicitly modeling the density in sparse state-action spaces. Building on this, we introduce Generative OOD-regularized Model-based Policy Optimization (GORMPO), a density-regularized offline RL algorithm that uses generative density modeling to restrict policy updates to high-density areas of the dataset. We present theoretical results on GORMPO's performance. Furthermore, we examine whether better OOD detection corresponds to better model-based offline policies. We compare (1) the OOD detection capabilities of various density estimators and (2) their performance within the GORMPO framework on a real-world medical dataset and sparse offline RL datasets. We theoretically guarantee GORMPO's performance under mild assumptions. Empirically, GORMPO outperforms state-of-the-art baselines by 17\% on a real-world medical dataset and enhances the base model on the offline RL datasets. Our empirical findings show that better OOD detection generally results in improved policies in environments with stable dynamics, while conservative penalties with poor density estimation are favored when dynamics are uncertain.
GeoFidelity-Bench: Evaluating Block-Conditioned Geographic Fidelity of Street-View Generation
Kaizhen Tan
Text-to-image models can generate plausible street scenes from prompts such as “a street in New York City,” but it remains unclear whether these images resemble the requested place or merely reflect a generic city stereotype. Existing evaluation metrics mainly measure image quality or text alignment, and do not directly assess geographic fidelity. We introduce GeoFidelity-Bench, a benchmark for evaluating whether generated street-view images match a target location at the level of named street blocks. The benchmark contains 112 street blocks from 25 cities across six continents, paired with 7563 curated Mapillary reference images and geographic metadata. Its block-level design allows us to compare city-only prompts, prompts with street and neighborhood names, and prompts that additionally include raw GPS coordinates. Across six open-source text-to-image models, adding named local text improves similarity to the target location, while raw GPS coordinates add only a small and uneven gain. Same-city control prompts further show that the improvement is not explained by prompt length alone: corrupting local tokens reduces retrieval performance, with stronger evidence for neighborhood-level or combined local information than for the street token alone. The benchmark also shows that current generators remain far from matching real local street-view variation. GeoFidelity-Bench provides a controlled testbed for studying location-conditioned generation and for measuring progress beyond generic city-level plausibility.
Geometrically Disentangling Concept Learning from the Language Modeling Loss
Yupei Wang ⋅ Neil R Mallinar ⋅ Misha Belkin ⋅ Alex Warstadt
How do language models acquire such a vast array of concepts and abilities from next-token prediction alone? We introduce an interpretability framework that exposes how this single loss relates to different concepts at different points during pretraining. For each layer and checkpoint, we measure the \emph{optimization engagement} with a concept, i.e., alignment between a probe-defined concept subspace and the average gradient outer product (AGOP) of the next-token loss. The concept subspace captures where the concept currently lives in the model's representation; AGOP captures the directions in which the loss exerts the strongest pressure. Across 12 lexical, syntactic, and semantic tasks and 19 Pythia-1B and -410M checkpoints, we find that optimization engagement with a concept is temporally aligned with behavioral changes in the model related to the concept. Furthermore, optimization engagement tends to peak before we observe the largest behavioral changes in the model, suggesting that sudden changes in model performance ("grokking") may be preceded by behaviorally unobservable geometric changes. However, this "geometric precedence" pattern is not universally observed; we also see cases where optimization engagement does not peak once, but rather persists at a high value, or peaks multiple times. These results indicate that the loss contributes to concept learning in a myriad of ways that simple probe performance alone cannot reveal.
Ghosted Layers: Unconstrained Activation Alignment for Recovering Layer-Pruned LLMs
Vincent-Daniel (Juyoung) Yun ⋅ Junhyuk Jo ⋅ Sai Praneeth Karimireddy ⋅ Sunwoo Lee
Layer pruning removes entire Transformer decoder blocks from large language models, but introduces a mismatch between the hidden state received by the next surviving layer and the distribution it was trained to process, leading to significant performance degradation. We propose Ghosted Layers, a training-free recovery module that addresses this issue by solving a boundary activation alignment problem. Our method derives a closed-form optimal linear operator from a small calibration set to reconstruct the activation discrepancy introduced by the pruned layers. We show that this solution corresponds to the unconstrained optimum of the alignment objective, whereas existing methods are restricted to constrained solutions over limited operator subspaces. Experiments across multiple LLM backbones and pruning strategies demonstrate that our method consistently improves accuracy and perplexity over prior training-free baselines, while preserving the efficiency gains of layer pruning.
Golden Layers and Where to Find Them: Improved Knowledge Editing for Large Language Models Via Layer Gradient Analysis
Shrestha Datta ⋅ Hongfu Liu ⋅ Anshuman Chhabra
Knowledge editing in Large Language Models (LLMs) aims to update the model’s prediction for a specific query to a desired target while preserving its behavior on all other inputs. This process typically involves two stages: identifying the layer to edit and performing the parameter update. Intuitively, different queries may localize knowledge at different depths of the model, resulting in different sample-wise editing performance for a fixed editing layer. In this work, we hypothesize the existence of fixed golden layers that can achieve near-optimal editing performance similar to sample-wise optimal layers. To validate this hypothesis, we provide empirical evidence by comparing golden layers against ground-truth sample-wise optimal layers. Furthermore, we show that golden layers can be reliably identified using a proxy dataset and generalize effectively to unseen test set queries across datasets. Finally, we propose a novel method, namely Layer Gradient Analysis (LGA), that estimates golden layers efficiently via gradient-attribution, avoiding extensive trial-and-error across multiple editing runs. Extensive experiments on several benchmark datasets demonstrate the effectiveness and robustness of our LGA approach across different LLM types and various knowledge editing methods.
Graph Sparse Sampling: Breaking the Curse of the Horizon in Continuous MDP Planning
Idan Lev-Yehudi ⋅ Vadim Indelman
Planning under uncertainty in continuous domains poses significant challenges, yet remains essential for autonomous systems. Tree-based search methods such as Monte Carlo Tree Search (MCTS) remain popular, but their branching structure can require sampling budgets that grow exponentially with lookahead depth in the worst case. From a tree perspective, continuous state or action spaces become especially challenging, since the planner must decide where to search in an infinite branching hierarchy. We propose Graph Sparse Sampling (GSS), an online planning algorithm that shares sampled futures across many candidate decisions, rather than sampling separate successors for each candidate action. This branch-free graph exposes large GPU-friendly batches, while using heuristics to focus computation. We prove finite-sample performance guarantees for GSS covering full-rank or low-rank generative simulators via smoothed backups, and discrete or sampled continuous action spaces. Under suitable overlap, regularity, and action-coverage conditions, these bounds have polynomial dependence on the planning horizon, formalizing when shared futures can avoid the exponential horizon dependence of tree-shaped sparse sampling. We demonstrate continuous-control simulations where GSS substantially outperforms tree-based planners on long horizons or achieves near-optimal performance, supporting no-branching graph planning as a useful complementary design principle for online control.
Guiding Data Allocation for Robust Subpopulation Generalization
Zhaoying Pan ⋅ Yipei Wang ⋅ Shenyu Lu ⋅ Xiaoqian Wang
Machine learning models often achieve high average accuracy in the training data while performing poorly on test data due to subpopulation shift. A common data-centric solution is to enforce balanced subgroup proportions, but full balance can be costly, infeasible, and not always necessary. In this work, we study whether balanced training data is the unique optimal configuration for robust subpopulation generalization. We analyze the theoretical performance across training subgroup distributions and show that multiple configurations, including substantially imbalanced ones, can achieve performance comparable to the balanced configuration. We further derive gradient-based directions for adjusting subgroup proportions to improve robustness more effectively. These directions can diverge from the direct path toward balance, suggesting that balancing is not always the most efficient data-allocation strategy. We validate the theoretical insights with controlled experiments on image and text benchmarks, showing that gradient-guided allocation can improve robustness more efficiently than directly enforcing balance. These findings suggest that strategically allocating data offers a more flexible and principled path to robust performance than simple balancing.
GUI-Libra: Data-Efficient Post-Training for Reliable Reasoning-and-Acting in Native GUI Agents
Rui Yang ⋅ Qianhui Wu ⋅ Zhaoyang Wang ⋅ Hanyang Chen ⋅ Ke Yang ⋅ Hao Cheng ⋅ Huaxiu Yao ⋅ Baolin Peng ⋅ Huan Zhang ⋅ Jianfeng Gao ⋅ Tong Zhang
Open-source native GUI agents still lag behind closed-source systems on long-horizon tasks. One reason is the direct reuse of generic post-training pipelines that ignore GUI-specific failure modes: standard supervised fine-tuning (SFT) with long chain-of-thought (CoT) reasoning often degrades grounding, and stronger offline optimization in RL does not necessarily translate to better online performance. This offline-to-online mismatch arises in part from \emph{partial verifiability}: multiple actions may validly advance a task, but supervision typically marks only one demonstrated action as correct, creating reward ambiguity. We present \textbf{GUI-Libra}, a data-efficient post-training recipe for reliable reasoning-and-acting in native GUI agents. GUI-Libra combines a construction and filtering pipeline for a curated 81K GUI reasoning dataset, \emph{action-aware supervised fine-tuning} that mixes reasoning-then-action and direct-action supervision with action-aware token reweighting, and KL-constrained RL with success-adaptive scaling to improve offline-to-online predictability under ambiguous rewards. Across web and mobile benchmarks, GUI-Libra consistently improves both step-wise accuracy and end-to-end task completion. GUI-Libra-4B and GUI-Libra-8B improve their base models by +15.6\% and +12.2\% on AndroidWorld, +4.0\% and +8.7\% on Online-Mind2Web, and +12.5\% and +11.3\% on WebArena-Lite-v2. These results show that careful reasoning data curation and tailored post-training can substantially improve long-horizon task solving without costly online data collection. We release our dataset, code, and models to support future research.
G-Zero: Self-Play for Open-Ended Generation from Zero Data
Chengsong Huang ⋅ Haolin Liu ⋅ Tong Zheng ⋅ Runpeng(Leo) Dai ⋅ Langlin Huang ⋅ JINYUAN LI ⋅ Zongxia Li ⋅ Zhepei Wei ⋅ Yu Meng ⋅ Jiaxin Huang
Self-evolving LLMs excel in verifiable domains but struggle in open-ended tasks, where reliance on proxy LLM judges introduces capability bottlenecks and reward hacking. To overcome this, we introduce G-Zero, a verifier-free, co-evolutionary framework for autonomous self-improvement. Our core innovation is \textbf{Hint-$\delta$}, an intrinsic reward that quantifies the predictive shift between a Generator model's unassisted response and its response conditioned on a self-generated hint. Using this signal, a Proposer model is trained via GRPO to continuously target the Generator's blind spots by synthesizing challenging queries and informative hints. The Generator is concurrently optimized via DPO to internalize these hint-guided improvements. Theoretically, we prove a best-iterate suboptimality guarantee for an idealized standard-DPO version of G-Zero, provided that the Proposer induces sufficient exploration coverage and the data filteration keeps pseudo-label score noise low.. By deriving supervision entirely from internal distributional dynamics, G-Zero bypasses the capability ceilings of external judges, providing a scalable, robust pathway for continuous LLM self-evolution across unverifiable domains.
Handwriting decoding as a challenging motor task for EEG Foundation Models
Srinivas Ravishankar ⋅ Ishayu Ghosh ⋅ Nora Zajzon ⋅ Teng (Simon) Fei ⋅ Virginia de Sa
Recent attempts at creating Foundation Models (FMs) for Electroencephalography (EEG) have achieved state-of-the-art performance on multiple tasks including Motor Imagery (MI). These MI tasks have typically involved coarse classification between imagined limb movements. However, the development of foundation models necessitates diverse datasets, both for pretraining and evaluating the progress of these models. In this work, we propose handwriting decoding as a challenging motor task for FMs. We show that several existing datasets are affected by confounds, and introduce a dataset that more rigorously evaluates models. On this dataset, we find that current FMs, despite showing SOTA performance in multiple MI datasets are outperformed by smaller task-specific models. We also highlight challenges specific to EEG-based handwriting decoding to inform future work. In our 4-letter classification task, we show that (a) Knowledge of movement-onset is crucial to reported decoding performance in prior works, with average performance across subjects dropping from $41.3\%$ to $32.4\%$. (b) Increasing test-time signal quality provides significant performance improvements ($45\%$ to $78\%$ in our best subject) compared to scaling training data with single-trial EEG. (c) While scaling training data steadily improves decoding performance, existing FMs do not outperform specialist models in handwriting decoding. We make our code and dataset available at https://anonymous.4open.science/r/EEG-Handwriting-BCI-DFCD
HearSayBench: Can LLMs Navigate from Abstract Human Rights to Lived Lives?
Sobhan Lotfi ⋅ Ava Iranmanesh ⋅ Ali Iranmanesh ⋅ Liwei Jiang
"Hearing is never like being.'' —Persian Proverb Large language models have become the default advisors for life-critical human problems. While they democratize access to personal counseling, they suffer from a silent foundation bias: the internet is a record of people with the freedom to act. Current benchmarks assume users have this same agency, ignoring the reality of those in war zones or navigating statelessness. These long-tail experiences are not only missing from training data, but authentic evaluation data to measure them is equally scarce. We introduce HearSayBench, a human-verified dataset of 400 scenarios from respected archives like the United Nations, covering 80 regions across three specific barriers: social, personal, and environmental. Our work uses Capabilities Approach to test if a model can distinguish between what a person is legally promised and what they are actually free to do in their specific environment. While these models may have "heard'' about global inequality during training, we find that this knowledge is merely hearsay. Across 11 frontier and open-weight models, we identify a systemic %37 performance drop between situational comprehension and structural reasoning. When faced with the most vulnerable users, models consistently offer a "Checklist of Impossible Things'': polite, fluent advice that is physically impossible or legally suicidal to follow. Ultimately, we show that the true digital divide is no longer about access to technology, but about whether an AI can recognize the reality of your life.
H-Flow: Self-supervised Human Scene Flow via Physics-inspired Joint Multi-modal Learning
Zhanbo Huang ⋅ Xiaoming Liu ⋅ Yu Kong
Parametric human models capture global pose but overlook fine-grained surface dynamics. Generic scene flow estimates dense motion but struggles with articulated humans and lacks 4D ground truth. To bridge this gap, we introduce H-Flow, a dense 4D motion representation that captures non-rigid deformations beyond skeletal kinematics. We estimate H-Flow from monocular video via a unified multi-head architecture that jointly perceives pose, depth, and flow. To overcome the scarcity of dense motion annotations, we propose a self-supervised learning paradigm that embeds geometric, structural, and biomechanical priors into optimization. These cross-modal constraints tightly couple pose, depth, and flow, so that improving any one modality simultaneously drives the others toward consistency. For evaluation, we present DynAct-4D, a high-fidelity synthetic benchmark providing dense 4D ground truth for complex human movements. Extensive experiments show that our method outperforms state-of-the-art scene flow baselines. Furthermore, H-Flow serves as an effective motion primitive, bringing substantial improvements to downstream tasks including action recognition and video generation. Models, code, and resources will be released upon publication.
Hierarchical Denoising For Multi-Step Visual Reasoning
Zezhong Qian ⋅ Xiaowei Chi ⋅ Chak-Wing Mak ⋅ Tianze Zhou ⋅ Ruibin Yuan ⋅ Yuhan Rui ⋅ Hengzhe Sun ⋅ Zhuoqun Wu ⋅ Yuming Li ⋅ Siyuan Qian ⋅ Sirui Han ⋅ Shanghang Zhang
Video models are recently evolving into vision foundation models, but they still lack human-like, multi-step reasoning. Existing streaming autoregressive diffusion models are efficient but lack the reasoning ability, whereas bidirectional diffusion allows for global revision but incurs high inference cost due to the dense frames in fixed-sequence denoising. Consequently, both paradigms struggle to maintain logical consistency with low-latency streaming in complex reasoning tasks. Bridging this gap, we propose HDR (Hierarchical Denoising for Visual Reasoning), a unified framework for multi-step reasoning by integrating hierarchical latents into the causal video generation process. HDR organizes video latents into a tree-structured hierarchy to perform coarse-to-fine reasoning before streaming output. Coarse denoising layers maintain uncertain hypotheses for global planning, while finer denoising layers progressively refine them into concrete visual states. A sparse hierarchical attention pattern (SHAP) further reduces temporal attention cost. We construct a level-stratified multi-step video reasoning benchmark with out-of-distribution cases, covering six tasks: maze navigation, Tower of Hanoi, one-line drawing, sliding puzzle, Sokoban, and water pouring. Compared with the streaming autoregressive diffusion baseline, HDR improves overall success from 34.22 to 60.29 (76.2% relative gain) in multi-step reasoning accuracy, and improves average progress from 76.00 to 89.56, indicating more consistent intermediate reasoning trajectories. For deployment efficiency, HDR maintains low-latency streaming at 0.70s per latent, 54.2x faster than bidirectional diffusion during streaming. HDR also demonstrates strong data efficiency, retaining 82.9% of its full-data success score using only 2% of the training data, compared with 52.0% for bidirectional diffusion. Further experiments on real-world robots showcase the potential of HDR in physical interaction, providing a new paradigm for physical world modeling. Project demo page is available at https://hierarchical-diffusion-reasoning.github.io/.
HorizonComposer: Spatiotemporally Consistent Driving Video Editing with Enriched Traffic Semantics
Mauricio Soroco ⋅ Yuqiu Liu ⋅ Zaid Tasneem ⋅ Francesco Pittaluga ⋅ Abhishek Aich ⋅ Wuyang Chen ⋅ Manmohan Chandraker ⋅ Ziyu Jiang
Instruction-guided video generative models offer a scalable solution for stress-testing autonomous driving systems by simulating diverse environmental conditions. However, driving scenes operate within a dense Operational Design Domain (ODD) governed by strict traffic semantics. When applied to global driving-condition edits, general-purpose instruction-guided video editors frequently corrupts these semantics, leading to structural hallucinations and ``temporal shock''. This work strictly distills and protects traffic semantics during video editing at three levels. First, we construct a hybrid dataset by combining temporally aligned real-world videos with synthetic edits, balancing foundational scene structure with unambiguous appearance signals. Second, during training, we cast model alignment as offline reinforcement learning via advantage conditioning. We extract dense, pixel-level rewards from the hybrid data to serve as a localized signal and actively steer generation toward structurally reliable pixel states. Finally, our model mitigates temporal shock by introducing thinking frames, a transition mechanism that seamlessly reconciles static image conditioning with dynamic video context. Extensive experiments demonstrate that our method prevents the corruption of multi-agent dynamics, establishing state-of-the-art spatiotemporal consistency and yielding an overwhelming user preference (88 % relative improvement in content preservation and 75 % in temporal consistency) and yielding a significant 5 % gain in downstream road line segmentation. We provide more video results in the supplementary material.
Large language models (LLMs) increasingly help people solve problems, from debugging code to repairing machinery. This process requires generating plausible hypotheses from partial descriptions, then updating them as more information arrives. Yet how LLMs perform this form of inference, and how close it is to optimal, remains unclear. We study this question in the number game, a controlled setting in which a learner infers the hypothesis supported by a few positive integers, such as $\{16, 8, 2, 64\}$: a rule like powers of 2 or an interval like numbers near 20. We measure the posterior over hypotheses using three complementary probes: posterior prediction, hypothesis evaluation, and hypothesis generation. We then compare LLM behavior with an optimal Bayesian model and human behavior, and test whether the same posterior is expressed across probes. LLMs are often well described by a two-parameter Bayesian fit, but with systematic offsets: by default they show a strong-sampling assumption that creates an implicit Occam's razor, favoring narrower hypotheses, while thinking mode shifts them toward greater prior reliance. We also find a robust evaluation--generation gap: LLMs select more correct hypotheses during hypothesis evaluation but generate simpler, more rule-like hypotheses. Finally, this Bayesian-with-bias pattern does not extrapolate. Models can behave as if they hold rule-like hypotheses over observed examples, yet generalize poorly to parts of the hypothesis domain not covered by those examples. Our results highlight a limitation of LLMs as general problem solvers, especially for scientific inference, where hypotheses must go beyond the data.
Improving constraint-based discovery with robust propagation and LLM priors
Ruiqi Lyu ⋅ Alistair Turcan ⋅ Martin J Zhang ⋅ Bryan Wilder
Constraint-based causal discovery recovers causal DAG structure from conditional independence (CI) relations. Classical methods such as PC orient v-structures first, then propagate edge directions from these seeds, relying on accurate CI tests and rich separating-set searches. In practice, these conditions often fail, causing cascading orientation errors. Recent work uses large language models (LLMs) as experts to augment edge orientation when standard assumptions fail, but often treats LLM outputs as reliable or assumes stable error behavior, despite hallucinations and instability. We propose MosaCD, a constraint-based framework that robustly combines CI tests with LLM inference to obtain high-confidence orientation seeds, then propagates them with Seeded Propagation Rules (SPR), which mitigate the fragility of collider-first orientation. We prove oracle-level soundness for SPR under explicit assumptions on the skeleton, separating-set record, and seed orientations, and give a stylized finite-sample analysis showing why prioritizing non-collider evidence can reduce orientation errors. Across 13 real-world benchmarks, MosaCD and SPR achieve substantially higher accuracy than existing methods through more reliable seeds and more robust propagation.
In-Context Multi-Operator Learning with DeepOSets
Shao-Ting Chiu ⋅ Aditya Nambiar ⋅ Ali Syed ⋅ Jonathan W. Siegel ⋅ Ulisses M. Braga-Neto
An important application of neural networks to scientific computing has been the learning of non-linear operators. In this framework, a neural network is trained to fit a non-linear map between two infinite dimensional spaces, for example, the solution operator of ordinary and partial differential equations. Recently, inspired by the discovery of in-context learning for large language models, an even more ambitious paradigm has been explored, called multi-operator learning. In this approach, a neural network is trained to learn many different operators at the same time. In order to evaluate one of the learned operators, the network is passed example inputs and outputs to disambiguate the desired operator. In this work, we provide a precise mathematical formulation of the multi-operator learning problem. In addition, we modify a simple efficient architecture, called DeepOSets, for multi-operator learning and prove its universality for multi-operator learning. Finally, we provide experiments showing the efficacy of DeepOSets for learning multiple operators corresponding to different initial-value and boundary-value differential equation problems.
Inferential Theory of Learning as a Framework for Test-Time Computation in Foundation Models
Mohit Prabhushankar ⋅ Ghassan AlRegib
Foundation models are billion-parameter neural networks that are trained under statistical learning principles to reason inductively regarding multifarious tasks at inference. However, foundation models are increasingly deployed in settings where the statistical principles that they were trained on may not hold. During deployment, users intervene in these systems' functionality through prompts, instructions, demonstrations, analogies, retrieval, tool calls, memory, verification, search, and multi-step reasoning. These operations change the effective knowledge state available at inference time, all of which are not well described by induction alone. This paper argues that Michalski’s Inferential Theory of Learning (ITL) provides a useful conceptual basis for describing deployed foundation models as multistrategy, goal-directed inference systems. In ITL, learning is modeled as the transformation of knowledge through transmutations such as generalization, specialization, abstraction, concretion, association, discrimination, explanation, derivation, reformulation, insertion, deletion, replication, and sorting. We reinterpret these classical transmutations in the context of modern test-time computation techniques, showing that the functionality of reasoning models, intelligent prompting, retrieval-augmented generation, tool use, memory, and agentic search can be understood as transmutation programs over knowledge states. We then identify limitations of classical ITL for contemporary machine learning and propose a probabilistic extension in which transmutations are stochastic operators selected under uncertainty and cost. Finally, we connect this view to a system-level information bottleneck principle, quantifying the new knowledge that is acquired during the inference process. The resulting framework positions ITL as a bridge between statistical learning, symbolic reasoning, abductive explanations, prompting, and agentic foundation models.
Informed Posterior Sampling: More Efficient Online Learning with Few Offline Demonstrations in Average-Reward MDPs
Dengwang Tang ⋅ Rahul Jain ⋅ Botao Hao ⋅ Zheng Wen ⋅ Dongze Ye
We study the problem of efficient online reinforcement learning in the infinite horizon setting when there is an offline dataset to start with. We assume that the offline dataset is generated by an expert but with unknown level of competence, i.e., it is not perfect and not necessarily using the optimal policy. We show that if the learning agent models the behavioral policy (parameterized by a competence parameter) used by the expert, it can do substantially better in terms of minimizing cumulative regret, than if it doesn't do that. We establish an upper bound on regret of the exact informed PSRL (iPSRL) algorithm that scales as $\tilde{\mathcal{O}}(\sqrt{T})$. This requires a novel prior-dependent regret analysis of Bayesian online learning algorithms for the infinite horizon setting. We then propose the informed RLSVI (iRLSVI) algorithm to efficiently approximate the iPSRL algorithm. Empirical results show that small offline expert datasets are sufficient for iRLSVI to outperform online-only algorithms on hard exploration domains.
Inline Critic Steers Image Editing
Weitai Kang ⋅ Xiaohang Zhan ⋅ Yizhou Wang ⋅ Mang Tik Chiu ⋅ Jason Kuen ⋅ Kangning Liu ⋅ Yan Yan
Instruction-based image editing exhibits heterogeneous difficulty not only across cases but also across regions of an image, motivating refinement approaches that allocate correction to where the model struggles. Existing refinement signals arrive late, after a fully generated image or a completed denoising step. We ask whether such a signal can act within an ongoing forward pass. To investigate this, we probe a frozen image-editing model and find that although generation capability emerges only in the last few layers, the error pattern is already set in early layerss (rank correlation ρ = 0.83 with the final-layer error map). Based on this, we introduce Inline Critic, a learnable token that critiques a frozen model's predictions at its intermediate layers and steers its hidden states to refine generation during the forward pass. A three-stage recipe is proposed to stabilize the training from learning how to critique to steering generation. As a result, we achieve state of the art on GEdit-Bench (7.89), a +9.4 gain on RISEBench over the same backbone, and the strongest open-source result on KRIS-Bench (81.92, surpassing GPT-4o). We further provide analyses showing that the critic genuinely shapes the model's attention and prediction updates at subsequent layers.
Inside Emergence: Structure-Behaviour Gaps in Language Model Training
Hak Hyun Kim ⋅ Yash Raj ⋅ Soroush Vosoughi
In densely checkpointed language model training, a capability can remain flat and then appear within a narrow window of steps. Behaviour alone cannot tell whether internal structure changes just as abruptly or instead lags earlier structural reorganisation. We study this relationship across 150 main Pythia 70M-410M trajectories (3 scales $\times$ 5 tasks $\times$ 10 seeds), using seed replication to estimate trajectory-level event order. Tracking the spectra of mean-ablation patching matrices throughout training, we find two task-determined dimensions. The discontinuity ratio $\rho$ separates tasks where behaviour changes more abruptly than the structural spectrum from tasks where the two co-evolve, reconciling competing accounts of emergence within this model range. The structure-behaviour gap $\tau$ shows that spectral completion precedes behavioural emergence in 94% of main trajectories, with median absolute leads of 2,000-12,200 training steps (11$\times$-206$\times$ in step ratio). Together these quantities support offline trajectory auditing: $\rho$ computed from 28% of training predicts final $\rho$ at $r = 0.93$, while $\tau$ identifies a pre-emergence checkpoint for circuit inspection; at those checkpoints, Pythia-410M causal ablations show that early-prominent components carry 86-99% of post-emergence capability across the five tasks tested causally.
Interpreting Latent Protein Language Model Features with Geometric Annotations
Siddharth Setlur ⋅ Djordje Mihajlovic ⋅ Darrick Lee
Protein language models (pLMs) encode information about protein sequences which enable downstream tasks such as structure prediction, but their internal representations are not well understood. Sparse autoencoders (SAEs) provide a promising tool to disentangle latent pLM representations into interpretable features, but existing annotation pipelines largely rely on protein-level annotations derived from database labels and LLM annotations of top activating sequences. Such annotations can overlook the localized residue-level and geometric patterns encoded by sparse features. We introduce an automated and scalable method for interpreting SAE features in ESM-2 by using geometrically inspired features of the protein $\text{C}_{\alpha}$ backbone. Across ESM-2 8M layers, geometric annotations explain a large fraction of SAE features, expanding coverage beyond database and sequence-based methods. In particular, geometry can distinguish SAE features sharing the same database annotation, revealing substructure within known biological labels. A significant portion of SAE features activate on unannotated metagenomic protein sequences enabling us to use our SAE annotations to better understand these sequences. In addition, ablation experiments at the level of contact predictions hint toward SAE features controlling protein geometry. This provides a robust method of annotating proteins activated within SAE neurons at a residue level, providing a bridge between mechanistic interpretability and structural biology.
Intra-Option Fitted Q-Evaluation: Evaluating Hierarchical Policies from Non-Hierarchical Data
Yunfu Deng ⋅ Josiah Hanna
Off-policy evaluation (OPE) estimates the expected return of a target policy from previously collected data without additional environment interaction. While OPE methods for flat Markovian policies are well studied, little work has addressed evaluating hierarchical policies in which a high-level policy selects temporally extended options that generate primitive actions until a termination condition is met. The primary existing approach applies per-decision importance sampling at the option level, but requires option-annotated trajectories and exhibits variance that grows with the horizon and action dimensionality. For non-hierarchical policies, fitted Q-evaluation (FQE) typically achieves lower error than importance sampling by leveraging the classic Bellman equation for policy evaluation; however, a naive extension of FQE to hierarchical policies results in a biased policy value estimate. In this paper, we introduce Intra-Option Fitted Q-Evaluation (IO-FQE), which estimates a value function in the augmented state-option space; this approach enables OPE of hierarchical policies even when we lack annotations of what option was ran in the data. We develop two continuous-action instantiations of IO-FQE and show on hierarchical continuous control tasks (AntMaze navigation and OGBench Puzzle manipulation) that IO-FQE eliminates the bias incurred by a naive application of FQE to hierarchical policies and substantially lowers mean squared-error compared to option-level importance sampling.
Intrinsic Riemannian Cross-covariance for Manifold-valued Random Objects
Carlos Soto ⋅ Cheng Wang ⋅ Yujing Huang ⋅ Xiaoyu Chen
Covariance estimation yields a fundamental second-order statistic underlying representation learning, dimension reduction, and dependence modeling. While covariance has been well understood in Euclidean spaces, it is ill-defined for random objects residing on nonlinear Riemannian manifolds, which increasingly arise in modern machine learning applications involving shapes, symmetric positive definite (SPD) matrices, etc. This paper introduces an intrinsic Riemannian cross-covariance for manifold-valued random objects. Our approach defines covariance and correlation by transporting local variations to a common tangent space via parallel transport, yielding a second-order descriptor that is independent of arbitrary coordinate choices. We establish that the proposed covariance inherits desirable properties of its Euclidean counterparts and characterize its asymptotic behavior. Numerical studies on spheres and SPD manifolds, together with real-data experiments on heart valve shapes in Kendall's shape space, demonstrate the effectiveness and verify the properties. Our results position Riemannian covariance as a fundamental tool for second-order learning and analysis in non-Euclidean representation spaces.
Steering vectors (SVs) are widely used to influence the expression of concepts (e.g., truthfulness) in large language model outputs. A key assumption underpinning SVs is that they are linearly discriminative with respect to the concept: representations of texts that exhibit the concept are more aligned with the SV than those that do not, motivating shifts along the positive or negative SV direction to respectively promote or suppress the concept. In this work, we identify an inverted detection-control phenomenon in which some highly discriminative SVs that are aligned with positive representations can consistently promote the opposite behavior. We refer to such vectors as inverted-steering vectors (ISVs). We provide a geometric characterization of ISVs' effects, finding that steering along these directions systematically pushes representations in discriminative downstream heads as if the concept were absent, even prior to decoding. Motivated by this analysis, we propose an approach for distinguishing ISVs without requiring generation or associated response scoring. This enables targeted sign flips, which we use to improve a foundational detection-based steering pipeline via Inference Time Intervention (ITI). Our approach improves results in 27/30 experiments, ranging from +0.9\% to +138\%. We evaluate our findings on Gemma 3 12B, Qwen 2.5 14B, and Olmo 3 7B across 5 concepts. We will make our code publicly available upon acceptance.
Is Decentralized LLM Agent RL Robust to Heterogeneity? An Asymmetric Tale
Canyu Chen ⋅ Kangyu Zhu ⋅ Zhaorun Chen ⋅ Zhanhui Zhou ⋅ Shizhe Diao ⋅ Yiping Lu ⋅ Tian Li ⋅ Manling Li ⋅ Dawn Song
Training AI agents powered by Large Language Models (LLMs) typically requires centralized access to user data, raising privacy and scalability concerns. We explore FedAgent, a decentralized reinforcement learning paradigm that collaboratively trains LLM agents across distributed clients without sharing local data. The central reliability question is: Is FedAgent effective under uniform client distribution, and more importantly, is it robust to client heterogeneity? For the former, we provide the first empirical evidence that FedAgent matches Centralized Agent Training and outperforms Local Agent Training. For the latter, we first formalize Agent Heterogeneity at two structurally distinct levels: task-level (what clients ask the agent to do) and environment-level (the dynamics in which the agent acts), anchored on the Input-Dynamics Asymmetry of task-augmented MDPs, referring to the architectural fact that tasks enter the policy through its input channel, while environments do not. Then, we theoretically establish an Asymmetric Robustness Mechanism: FedAgent is robust to task-level heterogeneity but non-robust to environment-level heterogeneity. We further identify three sufficient conditions under which FedAgent recovers robustness despite environment-level heterogeneity, and illustrate four possible training-curve patterns. On real-world agent benchmarks WebShop and ALFWorld, we empirically verify that FedAgent remains robust under extreme task-level heterogeneities and traces a stable-degrade-collapse spectrum under environment-level heterogeneities.
JARVIS-Bench: Benchmarking Personal Intelligence Agents on Long-Horizon Real-User Daily Traces
Weizhi Zhang ⋅ Wei-Chieh Huang ⋅ Yueqing Liang ⋅ Liwei Jiang ⋅ Zhengxiang Wang ⋅ Liangwei Yang ⋅ Zechen Li ⋅ Yuchen Wu ⋅ Haozhen Zhang ⋅ Yu Wang ⋅ Yuanchen Bei ⋅ Yue Zhou ⋅ Siqi Zhu ⋅ Henry P Zou ⋅ Jiahong Liu ⋅ Xinni Zhang ⋅ Paul Martin ⋅ Joseph Marvin Imperial ⋅ Yuyang Luo ⋅ Xiongxiao Xu ⋅ Baixiang Huang ⋅ Shanglin Wu ⋅ Lucas Resck ⋅ Yibo Wang ⋅ Yuqing Liu ⋅ Langzhou He ⋅ Chengze Li ⋅ Yuxin Tian ⋅ Kening Zheng ⋅ Enze Ma ⋅ Boi Huynh ⋅ Zheng Hui ⋅ Rui Yang ⋅ Tao Feng ⋅ Jie Yang ⋅ Shanghao Li ⋅ Haoran Wang ⋅ Wooseong Yang ⋅ Hanrong Zhang ⋅ Huanhuan Ma ⋅ Daye Yoon ⋅ Yaozu Wu ⋅ Shikan Lian ⋅ Xiaoqian Ruan ⋅ Fangxin Wang ⋅ Hyeonjeong Park ⋅ Hins Hu ⋅ Wenzhe Fan ⋅ Chen Wang ⋅ Yifan Gu ⋅ Dongyuan Li ⋅ Song Wang ⋅ Aylin Caliskan ⋅ Jindong Wang ⋅ Xiao Luo ⋅ Yankai Chen ⋅ Kai Shu ⋅ Steve Liu ⋅ Philip S Yu
Personal intelligence agents aim to support users across daily-life tasks by learning their preferences, routines, needs, and emotional states from long-term interaction. They are expected to anticipate user needs, provide proactive assistance, and infer preferences that users have never explicitly articulated. However, existing benchmarks for LLM personalization lack real user data spanning extended periods and diverse daily-life domains, and typically reduce personalization to simplified settings such as recommendation or fact retrieval. We introduce JARVIS-Bench, a new benchmark for evaluating personal intelligence agents, curated from real users’ daily traces and augmented with synthetic trajectory expansions grounded in implicit-preference insights from surveys and structured personas. JARVIS-Bench is built from participants who contributed 28 to 44 days of multimodal self-tracking logs, structured personas, and a 100-question implicit-preference survey spanning eight domains. It supports four downstream task surfaces: implicit preference reasoning, proactive-help prediction, emotion-aware modeling, and cross-domain transfer, all evaluated through a unified event iterator and long-horizon user-memory pipeline. We benchmark 28 LLMs from 10 model families, including Gemini, GPT, Qwen, Gemma, and Claude, across a five-condition input ladder ranging from no memory to lifelong memory. Results show that memory and model scaling improve personalization, yet current frontier models remain far from achieving robust real-world personal intelligence.
K-PWM: Control-Oriented Structured World Models under Partial Observation
Santosh M Rajkumar ⋅ Sriram Narayanan ⋅ Samuel E Otto ⋅ Debdipta Goswami
World models enable prediction, planning, and decision-making by learning internal simulators of environment dynamics. Although substantial progress has been made in world models from pixel-based observations, many physical systems are instead observed through vector-based measurements that are noisy and only partially informative of the underlying state. We introduce K-PWM, a Koopman-structured probabilistic world model for prediction and control under partial observation. K-PWM combines a parameterized Koopman-structured state-space model with a nonlinear observation decoder, and performs probabilistic latent-state inference directly through the learned model parameters rather than through a separately trained inference network. We train K-PWM using a generalized expectation conditional maximization (GECM) procedure with principled initialization. Across Gymnasium MuJoCo tasks, K-PWM improves sample efficiency, yields reliable long-horizon predictions, and supports downstream control through model predictive path integral (MPPI) control. These results suggest that structured probabilistic latent dynamics provide a useful route toward data-efficient world modeling and control in partially observable vector-valued settings.
Linear attention has recently gained significant attention for long-context inference due to its constant decoding cost with respect to context length. However, existing serving systems typically serve linear attention by recurrently computing and updating a large linear attention state in every decoding step. Since the state is much larger than the per-token key and value, recurrent decoding incurs substantial memory access and becomes inefficient for serving linear attention. In this paper, we propose KVBuffer, an IO-aware serving mechanism for linear attention. By buffering recent keys and values, KVBuffer enables serving systems to compute linear attention outputs in more flexible and memory-efficient ways. For decoding, KVBuffer enables chunkwise computation, which reduces average memory access and decoding latency by deferring state updates and applying them in batch. For speculative decoding, KVBuffer verifies draft tokens in parallel and avoids storing temporary states. For short contexts, KVBuffer computes attention outputs directly from buffered keys and values, without creating or updating the linear attention state. We implement KVBuffer in SGLang for Qwen3-Next. Our evaluations show that KVBuffer can reduce linear attention decoding latency by up to 45.17\% and increase the maximum number of serving requests by $5 \times$ for speculative decoding when verifying four draft tokens.
Domain adaptation faces a fundamental paradox in the cold-start regime. When target data is scarce, statistical methods fail to distinguish relevant source domains from irrelevant ones, which often leads to negative transfer. In this paper, we address this challenge by leveraging expert textual descriptions of the target domain, a resource that is often available but overlooked. We propose a probabilistic framework that translates these semantic descriptions into a choice model, namely a Language-Induced Prior (LIP), that learns the preferences from a pre-trained Large Language Model (LLM). The LIP is then integrated into an Expectation-Maximization (EM) algorithm to identify source relevance. Methodologically, this framework is compatible with any parametric model where a likelihood is available. It allows the LIP to guide the selection of sources when target signals are weak, while gradually refining these choices as samples accumulate. Theoretically, we prove that the estimator roughly matches an oracle cold-start MSE under a correct prior, while remaining asymptotically consistent regardless of the quality of the LIP. Empirically, we validated the framework on a descriptive (Gaussian estimation), a predictive (C-MAPSS dataset), and a prescriptive task (MuJoCo Hopper).
Learnable Low-Rank Polynomial Sketch for Effective Linear Attention
Zongyue Qin ⋅ Haoran Deng ⋅ Jason Cong ⋅ Yizhou Sun
Softmax attention in Transformers suffers from quadratic complexity in sequence length, making it impractical for long-context applications. Linear attention alleviates this issue by replacing the exponential kernel with alternative functions that enable linear-time computation. Among existing linear attention approaches, recent studies have shown that polynomial kernels are particularly effective, as they exhibit sparse and spiky behavior similar to softmax attention, which emphasizes large dot products while suppressing irrelevant interactions. However, the exact computation of high-degree polynomial kernels is infeasible for high-dimensional representations. As a result, prior work relies on approximate polynomial kernels. This introduces a non-negligible approximation error. In this paper, we show that, from the perspective of polynomial kernel approximation, existing linear attention methods are still suboptimal. We propose Learnable Low-Rank Polynomial Sketch (LLoPS), a principled and flexible framework for approximating polynomial kernels with linear attention. Our method learns a low-rank polynomial sketch that provably achieves a strictly smaller approximation error than existing approaches. Experiment results show that LLoPS achieves the highest performance across extensive benchmarks, comparing with various linear attention baselines.
Learning a Unified Cross-Model Semantic Dictionary via Gated Bottleneck Sparse Autoencoders
Jinchi Zhu ⋅ Thomas Tie Luo
Foundation models pretrained on similar data distributions tend to encode semantically aligned concepts; yet these representations remain entangled with model-specific inductive biases, which hinders both unified interpretability and cross-model feature reuse. Existing approaches address this by aligning concepts across model-specific representation spaces, but do not explicitly account for model-specific biases, resulting in limited cross-model reconstruction fidelity (low $R^2$) and poor feature transferability. We propose the *Gated Bottleneck Sparse Autoencoder* (GB-SAE), a framework that takes multiple—homogeneous or heterogeneous—foundation models as input and factorizes their representations into shared and private components. GB-SAE jointly learns a single model-agnostic semantic dictionary and, for each model, a private residual dictionary, via a learnable gating mechanism that encourages competition between the two. Conceptually, we cast unified multi-model interpretability as a representation factorization problem and solve it through bottlenecked sparse dictionary learning. Empirically, GB-SAE achieves unified and faithful interpretability across diverse architectures, high reusability of the learned shared dictionary, and strong generalization to downstream tasks—capabilities that alignment-based paradigms, by design, cannot fully support.
Cell types are organized by taxonomic relationships that define lineages in the so called cell ontology. However, most existing foundation models typically ignore cell-type lineages encoded in this cell ontology. We introduce a biologically informed foundation model called \textbf{scOntoFM}, which embeds hierarchical cell ontology into representation learning. Using Lowest Common Ancestor (LCA) distances from the ontology graph, our framework pairs efficient offline triplet sampling with hierarchical cell-ontology learning. This approach jointly preserves local neighborhoods and shapes the global embedding geometry to reflect the ontology structure. Across diverse cell- and gene-level benchmarks, the model consistently improves performance, with especially strong gains in zero-shot settings. Our model also balances batch integration with biological structure preservation, providing complementary perspectives to existing embedding evaluation frameworks and supporting scalable biological discovery.
Learning Evidence Highlighting for Frozen LLMs
Shaoang Li ⋅ Yanhang Shi ⋅ Yufei Li ⋅ Mingfu Liang ⋅ Xiaohan Wei ⋅ Yuchen Pu ⋅ Fei Tian ⋅ Chonglin Sun ⋅ Frank Shyu ⋅ Luke Simon ⋅ Sandeep Pandey ⋅ Xi Liu ⋅ Jian Li
Large Language Models (LLMs) can reason well over focused inputs, yet often miss decisive evidence buried in long, noisy contexts. We introduce HiLight, an Evidence Emphasis framework that turns evidence selection into a learned, non-destructive input-side control problem for frozen LLMs. Rather than retrieving, pruning, compressing, or rewriting the input, HiLight trains a lightweight Emphasis Actor to insert minimal highlight tags around pivotal spans while preserving the original context. A frozen Solver then reasons over the emphasized input. The Actor is trained only from the Solver's downstream task reward, requiring no evidence labels, Solver gradients, logits, or internal activations. This yields a solver-compatible alternative to retrieval-style hard selection, context compression, and instance-level prompt rewriting. Across sequential recommendation and QA, HiLight consistently improves over manual prompting and strong automated prompt-optimization baselines, with gains up to +27.5\% over manual instruction (MI) and +10.8\% over the strongest baseline on Amazon-Beauty. The learned emphasis policy transfers zero-shot to smaller and larger unseen Solvers across model families, including an API-based Solver, and its highlights align with human supporting evidence up to 0.78 F1. These results suggest that evidence selection can be learned as a reusable input-side control mechanism for frozen LLMs.
Learning in Context, Guided by Choice: A Reward-Free Paradigm for Reinforcement Learning with Transformers
Juncheng Dong ⋅ Moyang Guo ⋅ Bowen He ⋅ Ethan Fang ⋅ Zhuoran Yang ⋅ Vahid Tarokh
In-context reinforcement learning (ICRL) leverages the in-context learning capabilities of transformer models (TMs) to efficiently generalize to unseen sequential decision-making tasks without parameter updates. However, existing ICRL methods rely on explicit reward signals during pretraining, which limits their applicability when rewards are ambiguous, hard to specify, or costly to obtain. To overcome this limitation, we propose a new learning paradigm, \emph{In-Context Preference-based Reinforcement Learning} (ICPRL), in which both pretraining and deployment rely solely on preference feedback, eliminating the need for reward supervision. We study two variants that differ in the granularity of feedback: \emph{Immediate Preference-based RL} (I-PRL) with per-step preferences that generalize dueling bandits, and \emph{Trajectory Preference-based RL} (T-PRL) with trajectory-level comparisons. We first show that supervised pretraining, a standard approach in ICRL, remains effective under preference-only context datasets, demonstrating the feasibility of in-context solving unseen tasks using only preference signals. To further improve data efficiency, we introduce alternative preference-native frameworks for I-PRL and T-PRL that directly optimize TM policies from preference data without requiring reward signals nor optimal action labels. Experiments on dueling bandits, navigation, and continuous control tasks demonstrate that ICPRL enables strong in-context generalization to unseen tasks, achieving performance comparable to ICRL methods trained with full reward supervision.
Learning Rate Decay Can Exponentially Accelerate SGD for Global Optimization of Nonconvex Functions
Guneykan Ozgul ⋅ Dylan Herman ⋅ Junhyung Lyle Kim ⋅ Shree H Sureshbabu ⋅ Shouvanik Chakrabarti
Stochastic Gradient Descent (SGD) is a workhorse algorithm for continuous optimization. It is a folklore belief among deep learning practitioners that learning rate decay in SGD substantially improves performance. However, it has remained unclear whether learning rate decay offers an asymptotic advantage for \emph{global} nonconvex optimization. We answer this question in the affirmative by demonstrating a natural class of nonconvex functions for which we prove that SGD with learning rate decay requires \emph{exponentially fewer} gradient queries for global optimization than SGD with any fixed learning rate. To the best of our knowledge, this is the first exponential advantage that has been demonstrated for learning rate decay. The class of functions we consider includes many popular benchmark nonconvex functions. Our results provide a robust explanatory theory for the empirically observed benefits of learning rate decay. Our technical results are built upon a new discretization analysis of SGD with decaying step size, that allows us to establish a clean correspondence with continuous-time annealing of Langevin diffusions. We then show that this annealed diffusion performs the non-logconcave sampling task associated to the optimization problem in polynomial time, via a novel application of weak Poincar\'{e} inequalities.
The Normalized Transformer, or nGPT (Loshchilov et al., 2025) achieves impressive training speedups and does not require weight decay or learning rate warmup. However, despite having hyperparameters that explicitly scale with model size, we observe that nGPT does not exhibit learning rate transfer across model dimension and token horizon. To rectify this, we combine numerical experiments with a principled use of alignment exponents (Everett et al., 2024) to revisit and modify the $\mu$P approach to yperparameter transfer (Yang and Hu, 2021). The result is a novel nGPT parameterization we call $\nu$GPT. Through extensive empirical validation, we find $\nu$GPT exhibits learning rate transfer across width, depth, and token horizon.
Learning Task-Centric World Models from Visual Foundations
Minghao Fu ⋅ Fan Feng ⋅ Nick Hansen ⋅ Biwei Huang
World models enable agents to predict future dynamics conditioned on actions, making the choice of latent state representation central to planning and control. Existing latents are often either learned directly from pixels with limited semantic structure or inherited from frozen visual foundation models with excessive task-irrelevant detail, yielding state spaces that are poorly matched to downstream planning and control. This is especially challenging in reward-free offline settings, where the model must learn from fixed trajectories without reward supervision or online interaction. To address this, we propose TC-WM, a framework for turning foundation-model embeddings into compact, task-sufficient world representations. The key design is to treat the pretrained embedding space as a semantic scaffold rather than as the final state space: TC-WM linearly projects high-dimensional visual embeddings into a compact latent, aligns a designated subspace with the agent’s physical state via contrastive learning, and reconstructs embeddings to preserve useful visual structure. This combines the generality of foundation features with the controllability of task-centric dynamics. Theoretically, we show that TC-WM suffices to identify the task-centric latent factors up to a simple transformation. Empirically, TC-WM enables test-time planning across diverse environments, e.g., Robomimic and D4RL, achieving better world modeling quality and more precise control compared to state-of-the-art world model approaches. Webpage: https://tc-wm.github.io/
Learning to Follow In-Context Watermark Instructions via Self-Distillation
Yepeng Liu ⋅ Tianyi Chen ⋅ Xuandong Zhao ⋅ Dawn Song ⋅ Yuheng Bu
In-context watermarking (ICW) prepends an instruction to a query asking the model to embed a statistically detectable signal in its response. It thus equips LLMs with a watermarking interface that third parties can invoke without access to model internals. Its reliability hinges on the LLM following the instruction without degrading answer quality, yet how well current LLMs do so has not been measured. We introduce ICWBench, a benchmark of three verifiable ICW instruction families, each scored on both detectability and answer quality. Evaluating 14 frontier proprietary and open-source LLMs, we find that none of the evaluated LLMs achieves both objectives across all three families. To address this, we propose a self-contained two-stage training method, requiring no distillation from a stronger model, no manual annotation, and no pre-existing ICW IF ability. The first stage, self-distillation with logits perturbation (SDLP), uses the same base LLM as both teacher and student: an instruction-equivalent decoding-time logits perturbation makes the teacher follow the ICW instruction, and the student is trained to match the teacher's output distribution. The second stage applies reinforcement learning with the automatic verifier as the reward. Applied to Qwen3-14B, the weakest of the 14 evaluated LLMs in ICW IF, our method raises average TPR@$1\%$FPR across three ICW instructions from $0.100$ to $0.974$, achieving a more favorable trade-off than the frontier proprietary LLMs we evaluate.
Learning permutations is fundamental to sorting, ranking, and matching, but existing differentiable methods based on entropy-regularized Sinkhorn produce a single softened solution and collapse under ambiguity. We present PermFlow, a conditional flow matching framework that operates directly on the affine subspace of matrices with unit row and column sums. A closed-form tangent-space projector preserves these constraints exactly along every trajectory, by construction rather than through iterative correction, and a nearest-target coupling routes distinct noisy initializations toward distinct valid permutations. The result is a model that captures multimodal permutation distributions rather than collapsing them to a single mode. On a visual sorting task with blended-digit ambiguity and a symmetric linear assignment problem, PermFlow achieves high accuracy on unambiguous inputs and recovers both valid permutations under ambiguity, where Sinkhorn-based baselines structurally fail.
Learning What Not to Impute: An Uncertainty-Aware Diffusion Framework for Meaningful Missingness
Lixing Zhang ⋅ Yidong Ouyang ⋅ Weifu Li ⋅ Guang Cheng ⋅ Shixiang Zhu ⋅ Liyan Xie
Missing value imputation is a fundamental task in machine learning, with most existing methods assuming that all missing entries correspond to unobserved regular values. In many real-world datasets, however, missingness may arise from two distinct sources: some entries are meaningfully missing (intrinsically absent and semantically valid), while others are missing due to the observation process and should be imputed. We formalize this distinction as a selective imputation problem, where the goal is to jointly infer which missing entries should be preserved and which should be recovered. To address this challenge, we propose Diff-Joint, a diffusion-based framework that jointly models tabular data together with a latent missingness mask. The method alternates between conditional sampling and uncertainty-aware aggregation to iteratively refine both imputed values and missingness labels. Empirical results on synthetic and real-world datasets demonstrate that Diff-Joint effectively identifies meaningfully missing entries while achieving competitive imputation accuracy and improved downstream task performance.
Learning What to Predict: Downstream-Guided Task Design for Continued Pretraining
Shuqi Ke ⋅ Giulia Fanti
Continued pretraining is optimized on a fixed self-supervised task but selected by downstream performance. This creates a coarse feedback loop: practitioners evaluate checkpoints, revise data mixtures or objectives, and rerun pretraining runs, while individual pretraining updates receive no signal about whether they help the target capability. We ask whether a small set of verifiable downstream examples can provide step-level feedback during continued pretraining without becoming learner supervision. We introduce V-pretraining, which separates a learner trained only by a self-supervised loss from a lightweight task designer that constructs targets or views for unlabeled batches. Given the current learner and an unlabeled batch, V-pretraining estimates the downstream value of a candidate target or view construction by the first-order predicted decrease in downstream loss after the self-supervised update it induces. The designer is trained to increase this value; the learner then applies the resulting self-supervised update with targets or views detached, so downstream labels never directly update learner parameters. V-pretraining can be used to learn adaptive top-$K$ soft targets for language modeling and learned views for self-supervised vision. Under wall-clock-matched continued pretraining, V-pretraining improves GSM8K Pass@1 for Qwen models using 1,024 GSM8K examples only as feedback, including a +7.4 point single-run gain for Qwen2.5-0.5B. In vision, V-pretraining improves DINOv3 transfer to ADE20K semantic segmentation and NYUv2 depth estimation while preserving ImageNet linear accuracy, indicating that feedback-guided task construction improves target downstream capabilities without collapsing general-purpose representations.
Learning Where and What to Restore for Composite Image Restoration
Jiachen Jiang ⋅ Tianyu Ding ⋅ Ke Zhang ⋅ Jinxin Zhou ⋅ Tianyi Chen ⋅ Ilya Zharkov ⋅ Zhihui Zhu ⋅ Luming Liang
Real-world degraded images often contain multiple co-occurring degradation types, making composite image restoration fundamentally different from the single-degradation setting assumed by most existing all-in-one methods. These methods typically apply uniform spatial computation and single-label task conditioning, limiting both spatial adaptivity and explicit modeling of degradation mixtures. We propose CART (Composite-Adaptive Routing and Task Conditioning), a unified framework that jointly decides where to spend computation and what degradation cues should guide restoration: a spatial mixer routes patches to graded-capacity experts by local restoration difficulty, and a channel mixer routes each image through degradation-specific experts, conditioned on a global task feature with multi-hot classification supervision. Empirically, CART achieves state-of-the-art performance for composite degradation restoration on CDD-11 and delivers the best results to date on the conventional 3-task and 5-task all-in-one benchmarks.
Less Structure is More: Minimal Representations for Supervised Learning
Menghui Zhou ⋅ Vitaveska Lanfranchi ⋅ Po Yang
Many real-world applications require highly interpretable machine learning systems, particularly in high-stakes domains such as healthcare. A promising recent direction is the paradigm of Maximal Coding Rate Reduction (MCR$^2$), which seeks to characterize and preserve the low-dimensional structure underlying each class. However, we find that exhaustively preserving structural information is often unnecessary and can even be detrimental in supervised learning, especially under noisy and uncertain real-world conditions, as it may overly constrain the fitting flexibility of the model. In contrast, we propose a simple yet effective framework, termed SimCoding, which captures only minimal structural information for each class. Despite relying on substantially less structural information, SimCoding significantly improves the generalization ability and robustness of deep models. Extensive experiments across diverse benchmark datasets demonstrate the effectiveness of SimCoding. We further validate SimCoding on a challenging real-world application, Parkinson’s disease severity assessment from free-living human activity signals, where it consistently achieves strong robustness and outperforms competing methods. Moreover, SimCoding can be naturally extended to incremental learning scenarios, where it substantially alleviates catastrophic forgetting and consistently surpasses strong baselines.
Leveraging Latent Visual Reasoning in Silence
Dongyao Zhu ⋅ Zhen Wang ⋅ Xi Xiao ⋅ Han Jiang ⋅ Saeed Vahidian ⋅ Wei-Lun (Harry) Chao ⋅ Tanya Berger-Wolf ⋅ Yu Su ⋅ Ranga Raju Vatsavai ⋅ Jianyang Gu
Latent visual reasoning involves visual evidence more directly in multimodal reasoning by inserting continuous latent tokens before textual generation. However, the necessity of these latent tokens at inference remains ambiguous. We show that replacing latent tokens with random noise or removing them completely causes little performance degradation across spatial reasoning benchmarks. Reinforcement learning further diminishes the latent generation behavior after post-training. These observations raise a central question: $\textit{Is latent visual reasoning still meaningful}$? We argue that its value should be measured by how effectively latent tokens guide learning, rather than whether they persist as an inference-time format. Our analysis shows that latent reasoning is unevenly favorable across question types, yet hard task-level routing for applying latent generation is brittle. Motivated by these findings, we propose an attention-based reward that encourages generated latent tokens to interact with later text tokens during RL. This reward promotes latent utilization when the latent mode is activated while preserving the flexibility to use pure-text reasoning. Experiments show that our method improves performance across perception and visual reasoning benchmarks, even when latent tokens are rarely generated after post-training. Our results highlight that, without explicit expression at inference, latent visual reasoning can shape better visual grounding and more accurate textual reasoning $\textbf{in silence}$. Our code and trained models are publicly available at Hugging Face https://huggingface.co/collections/doubleblindsubmission/submission3847.
Leviathan: Decoupling Input and Output Representations in Language Models
Reza T Batley ⋅ Sourav Saha
Modern language models use a single matrix for input embedding and output projection. This couples two distinct objectives: token representation and discrimination over a vocabulary. This work introduces *Leviathan*, a Transformer architecture that replaces the input embedding matrix with *learned embedding vectorization (LEV)*, a compact continuous mapping from token indices to embeddings. Leviathan's output head remains untied for a parameter increase of as low as 0.2\%. Under controlled comparisons with identical Transformer backbones, Leviathan consistently improves language modeling performance over standard tied-embedding baselines across a 200M-1.2B parameter regime on The Pile with gains that grow during training. At 1.2B scale, Leviathan reduces validation perplexity by 9\%, requires $2.1\times$ fewer training tokens to reach the tied baseline's final loss, and improves on all six downstream benchmarks evaluated, including a 30\% reduction in LAMBADA perplexity. Frequency-stratified analysis reveals gains to be concentrated in rare tokens, where continuous parameterization reduces perplexity by 81\%, falling to near zero for the most frequent.
Linguistic Trajectory Encoding for Efficient Long-Horizon Spatial Memory in Embodied Agents
Xie Tianyidan ⋅ Shenyi Wang ⋅ Qiang Tang ⋅ Mingjie Wang ⋅ Zhicheng Qiu ⋅ Xuanfu Li ⋅ Zhan Xu ⋅ Jian Yang ⋅ Lanjun Wang ⋅ Zili Yi
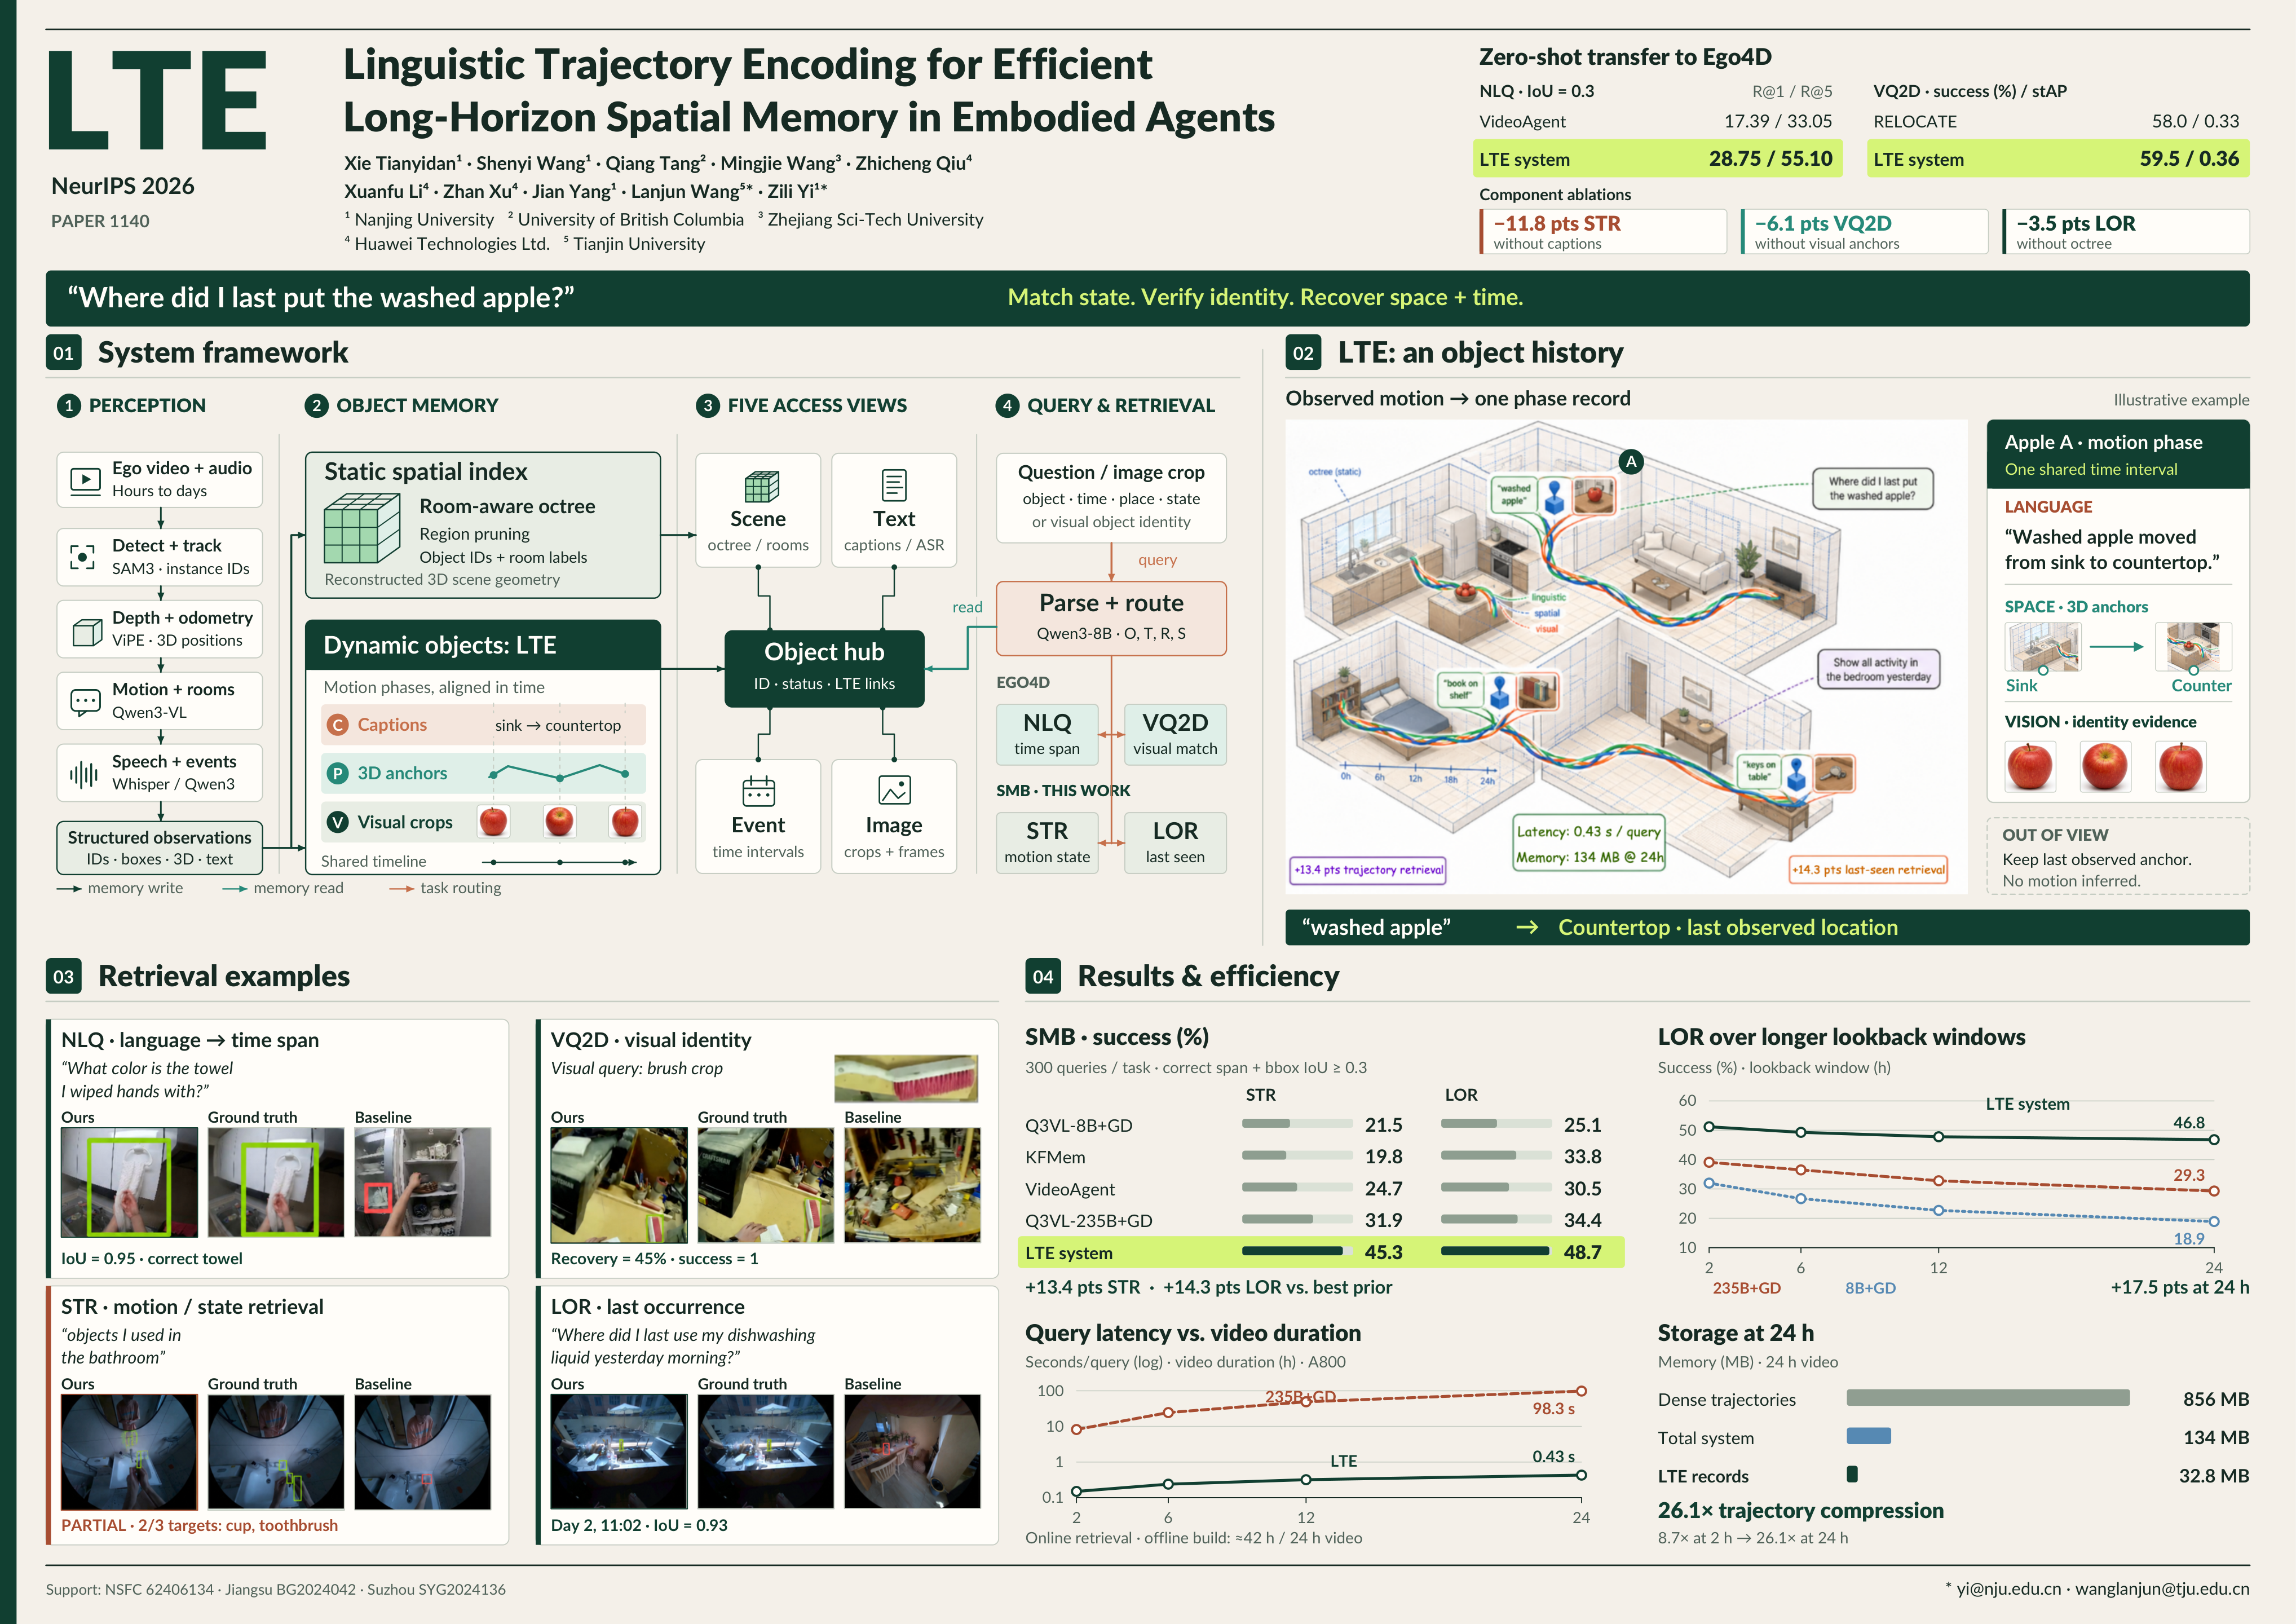
Embodied agents performing long-horizon tasks require a memory representation in which the state transitions of dynamic objects remain queryable in natural language across hours-to-days observation horizons. Existing systems either drop fine-grained motion (clip-level video-language embeddings), keep it only as raw coordinates (geometric SLAM), or organise it around immediate task context (agent working memories). None of them gives the agent a per-object timeline whose state transitions are themselves queryable in language. Our key contribution is \textbf{Linguistic Trajectory Encoding} (LTE), which compresses dynamic object motion histories via a hybrid representation combining natural language descriptions, sparse spatial anchors, and visual anchors. LTE adapts compression to motion complexity by anchoring periods without reliable observations to the last seen location, while representing motion with geometric waypoints and linguistic descriptions to preserve accuracy. To evaluate these capabilities across extended time horizons, we construct the \textbf{Spatial Memory Benchmark} (SMB) from EgoLife multi-day recordings, targeting capabilities absent in existing benchmarks: semantic trajectory retrieval and long-horizon object retrieval. On SMB, the LTE-based system achieves $45.3\%$ success in semantic trajectory retrieval and $48.7\%$ in long-horizon object retrieval, outperforming structured-memory and VLM baselines (best prior: $31.9\%$ and $34.4\%$). LTE achieves trajectory compression by factors of $8.7\times$ to $26.1\times$ with sub-second query latency on $24$\,h video. On Ego4D natural-language queries, the system reaches $28.75\%$ / $55.10\%$ R@1/R@5, $+15.80$ / $+31.30$ pts over EgoVLPv2.
Localizing Concepts in Visual Autoregressive Models
Nanxiang Jiang ⋅ Yang Liu ⋅ Yuanhao Wang ⋅ Min Xu
Understanding the internal routing of visual concepts is crucial for the safe and controllable adaptation of generative models. While concept localization has been widely studied in diffusion models, the emerging paradigm of next-scale visual autoregressive models remains largely unexplored. In this paper, we introduce LoCo, the first model-agnostic framework to localize where and when specific concepts emerge within autoregressive models. Driven by the native coarse-to-fine nature of next-scale generation, our method precisely maps conceptual knowledge across three distinct dimensions: Layer, Scale, and Position. To systematically localize and evaluate concept routing without context bias, we propose LoCoBench, a comprehensive dataset spanning 10 diverse categories. Extensive probing on image and video autoregressive models like Infinity, HunyuanImage-3.0, and InfinityStar shows that the localized positions are both interpretable and causally related to concept emergence. Building on these insights, we apply our localization method to three key applications: concept erasure, model personalization, and adversarial concept injection. Experiments demonstrate that our targeted intervention achieves state-of-the-art performance, substantially reducing computational overhead while preserving benign utility. Overall, our findings offer insights into how conceptual knowledge is routed during autoregressive generation, introducing a practical pathway for more interpretable, efficient, and secure adaptation.
LogicDirector: Enforcing Temporal Composition in Text-to-Video Generation
Yujiang Pu ⋅ Zixu Cheng ⋅ Shaogang Gong ⋅ Handong Zhao ⋅ Yu Kong
Accurately rendering temporal composition is fundamental to text-to-video (T2V) generation. While recent efforts incorporate temporal structure for long-horizon coherence, the intrinsic temporal understanding capability of T2V models remains underexplored. We observe that current models still struggle to respect canonical operators such as before and after, usually accompanied by missing entities and incorrect action binding. In this work, we propose LogicDirector, a test-time guidance framework that enforces temporal composition through executable logical specifications. By translating text prompts into first-order logic constraints over attention-derived evidence, LogicDirector constructs a neuro-symbolic verifier to evaluate noisy latent states during diffusion sampling for entity grounding, action binding, and temporal adherence. To enforce these constraints without expensive gradient-based optimization, we introduce a gradient-free Best-of-n latent search strategy, which preserves the model's native diffusion dynamics while steering logical satisfaction. To systematically study operator-level temporal composition, we curate TempBench, a diagnostic benchmark spanning four canonical relations, together with a hierarchical evaluation protocol that disentangles entity existence, event realization, and temporal correctness. Experiments on CogVideoX and Wan 2.1 demonstrate that our method significantly improves temporal composition while maintaining visual fidelity.
Long-Lived AI Agents Age Too: They Quietly Decay After Deployment
Jianing Zhu ⋅ Yeonju Ro ⋅ John Robertson ⋅ Kevin Wang ⋅ Junbo Li ⋅ Haris Vikalo ⋅ Aditya Akella ⋅ Zhangyang "Atlas" Wang
The reliability of any long-running system degrades over time: databases accumulate stale indices, software accrues technical debts, and human memory fades with age. Memory-enabled agents are no exception: Even with frozen weights, their system state continues to change as they accumulate context across sessions, and their ability to store, retrieve, and apply knowledge deteriorates in ways that standard snapshot evaluation cannot capture. Recent benchmarks have begun to measure static degradation over long-horizon tasks, yet they do not diagnose what kind of degradation occurs, where in the agent memory architecture it originates, or how routine operational events reshape it. In this work, we introduce AgingBench, a longitudinal reliability benchmark suite organized around four aging mechanisms: compression aging, interference aging, revision aging, and maintenance aging. To localize aging, we perform component-level attribution via counterfactual analysis, identifying whether degradation originates in the write, retrieval, or utilization stage of the agent’s memory pipeline. We evaluated across 7 scenarios, 14 models, various memory policies and agent frameworks, ranging from a fully controlled runner to practical automatic agents such as Claude Code. Over ~400 runs across 8-200 sessions, we find aging is not one-dimensional: it can be invisible to behavioral tests while silently decaying; structurally sharp, with a single model shifting from perfect to zero accuracy on derived-state tracking; and stage-dependent, as strong models fail not at writing but at reusing their memory. Our findings demonstrate that as agents take on longer operational lifetimes, understanding the internal structure of how they age is as important as measuring how well they perform on day one.
Lost on Campus: Evaluating Embodied Spatial Reasoning of Vision-Language Models in the Wild
Zehan Zheng ⋅ Yanyuan Chen ⋅ Deming Li ⋅ Yutao Tang ⋅ Jianwen Xie ⋅ Alan Yuille ⋅ Jieneng Chen ⋅ Cheng Peng
Embodied Spatial Reasoning (ESR) is central to deploying Vision-Language Models (VLMs) in real-world embodied tasks, yet remains inadequately evaluated. Existing benchmarks primarily assess spatial reasoning in static images or synthetic indoor environments, where semantic shortcuts often suffice, making it difficult to faithfully evaluate spatial reasoning capabilities in the wild. In light of this, we present Lost on Campus, a benchmark for evaluating ESR in large-scale real-world outdoor 3D environments reconstructed by 3D Gaussian Splatting. Our benchmark introduces a unified reasoning-action evaluation framework that seamlessly integrates diagnostic QA for isolated reasoning with closed-loop interactive navigation for active reasoning under multimodal instructions. To enable fine-grained diagnosis, we systematically decompose ESR into six fundamental capabilities: action grounding, spatial foresight, metric awareness, goal-directed planning, global localization, and spatio-temporal consistency. Extensive experiments reveal that: (i) Compared to indoor settings, real-world outdoor environments impose substantially higher demands on spatial reasoning, where existing models exhibit poor performance; (ii) VLMs still struggle with fine-grained visual alignment, with failures in spatial foresight and self-aware localization emerging as primary bottlenecks; (iii) Improving multimodal interaction capabilities and long-term spatial reasoning is crucial for advancing embodied intelligence. These findings highlight that faithful evaluation of ESR demands benchmarks tightly coupling perception, reasoning and action within realistic and continuous environments.
Magnitude-preserving Layers Enable Efficient GANs
Nick Huang ⋅ Jackson Woodleigh ⋅ Aaron Gokaslan ⋅ Xinjie Yi ⋅ James Tompkin
GANs are appealing because they generate sharp images in a single forward pass. Recent works have stabilized GAN training, but FID may still plateau on diverse datasets like ImageNet-256 because the discriminator's activation magnitudes increase through training. We trace this pathology to the discriminator's incentive to sharpen its decision boundary by rescaling activations rather than by finding better features. Then, building on R3GAN, we treat magnitude preservation as a first-class architectural target across the network: $\ell_2$ weight normalization with centering, magnitude-preserving LReLU and residuals, forced post-update normalization, and feed-forward classifier heads. Across a roadmap of configurations, we perform diagnostic ablations to clarify what does and does not work and why. The resulting models reach FIDs of 2.20 @ 17 M parameters, 1.63 @ 60 M, and 1.52 @ 130 M on class-conditional ImageNet-256. At 1 NFE, this is substantially more efficient than competing diffusion and autoregressive methods, and than prior GAN baselines too (e.g., 10$\times$ more efficient than StyleGAN-XL for similar FID). In sum, our work presents a new SOTA in FID/parameter efficiency derived from simple adversarial training with well-behaved magnitude preserving layers.
Masked Diffusion Language Models are Strong and Steerable Text-Based World Models for Agentic RL
Darshan Deshpande
Recent growth in different reinforcement learning (RL) techniques have surfaced a need for a wide variety of specialized training environments. These environments are typically hand-curated, with task and reward difficulties that are fixed rather than adaptive, making them ineffective training signals once a model's performance on the domain improves. As models continue to improve on these environments and reward signals grow increasingly sparse over longer horizons, the model encounters fewer diverse situations during rollouts, leaving it prone to overfitting on specific workflows or tool structures, also known as mode collapse. World models that simulate environment states have previously matched the performance of pure environment rollouts, making them a promising avenue for scaling diversity given that their outputs can be varied on-demand and at scale. However, autoregressive (AR) world models suffer from a fundamental left-to-right bias that prevents them from conditioning on globally interdependent state anchors such as tool schemas, prior turns, and expected outcomes. In this work, we (i) formalize text-based world modeling as a steerable transition-dynamics problem decomposed into initial environment state, task context, tool schemas, domain rules, and steering directives, and (ii) curate a dataset of 239,403 grounded state–action trajectories spanning nine open-source environments and twelve frontier model families. Using this dataset, we present a comparative study between AR LMs and masked diffusion language models (MDLMs), and show that MDLMs, by virtue of bidirectional anchor-aware denoising, produce better coherence, groundedness, and empirically validated rollout diversity than LLMs more than $4\times$ their total parameter size, with comparable inference latency. We introduce a plug-and-play GRPO training framework with deterministic state checks, and perform zero-shot transfer ablations on three out-of-distribution environments (ScienceWorld, ALFWorld, AppWorld) across three agent backbones from 1.2B–7B parameters (LFM2.5, Qwen3, Mistral), achieving absolute gains of up to 47\% over raw baselines without environment-specific fine-tuning. Finally, we conduct a behavioral analysis of failure modes under adversarial scenarios and a human evaluation centered on realism, outcome correctness, and training utility to showcase their reliability. We open source our work to encourage research in this direction.
MetaCluster: Enabling Deep Compression of Kolmogorov-Arnold Network
Matthew Raffel ⋅ Adwaith Renjith ⋅ Lizhong Chen
Kolmogorov-Arnold Networks (KANs) replace scalar weights with per-edge vectors of basis coefficients, thereby increasing expressivity and accuracy while also leading to a multiplicative increase in parameters and memory usage. We propose MetaCluster, a framework that makes KANs highly compressible without sacrificing accuracy. Specifically, a lightweight meta-learner, trained jointly with the KAN, maps low-dimensional embeddings to coefficient vectors, thereby constraining them to lie on a low-dimensional manifold amenable to clustering. We then run K-means in coefficient space and replace per-edge vectors with shared centroids. Afterward, the meta-learner can be discarded, and a brief fine-tuning of the centroid codebook recovers any residual accuracy loss. The resulting model stores only a small codebook and per-edge indices, exploiting the vector nature of KAN parameters to amortize storage across multiple coefficients. On MNIST, CIFAR-10, and CIFAR-100, across standard KANs and ConvKANs using multiple basis functions, MetaCluster achieves a reduction of up to $80\times$ in parameter storage, with no loss in accuracy. Similarly, in high-dimensional equation modeling tasks, MetaCluster achieves a $124.1\times$ parameter reduction without impacting performance. Code will be released upon publication.
Minimax Optimal Kernel Two-sample Testing in Sub-quadratic Time
Ikjun Choi ⋅ Shourya Pandey ⋅ Purnamrita Sarkar
Kernel two-sample tests based on Maximum Mean Discrepancy (MMD) are widely used, but the standard quadratic time MMD statistic requires evaluating $\Theta(N^2)$ kernel pairs where $N$ is the pooled sample size. Several subquadratic approximated MMD tests have been proposed to alleviate this issue, but existing methods either compromise the test power or make additional distributional assumptions to achieve power comparable to the quadratic-time MMD test. Motivated by this gap, we propose a sub-quadratic time computational method to approximate the MMD test, achieving minimax rate-optimal power with minimal distributional assumptions. Building on ideas in fast kernel density estimation and exponentially convergent trapezoidal rule in numerical analysis, our approximation reduces all-pairs kernel summation to fast Fenwick-tree prefix-sum queries. For fixed dimension, this yields subquadratic-time algorithms for several common characteristic kernels, including Laplace, Mat\'ern, Gaussian, and inverse multiquadric kernels. The approximation error is controlled tightly enough that the resulting subquadratic time test retains the power guarantees of the minimax-optimal unapproximated quadratic-time MMD test. The same implementation remains subquadratic for dimension $d=o(\log N/\log\log N)$, and can be paired with dimensionality-reduction algorithms when the signal is low-dimensional.
MinSteer: Minimal-Pair Steering via Two-Stage Cached Continuation
Muxuan Liu ⋅ Tatsuya Ishigaki ⋅ Yusuke Miyao ⋅ Hiroya Takamura ⋅ Ichiro Kobayashi
Do behavioral styles in large language models correspond to reusable directions in residual space, or do they mainly appear after averaging many noisy contrastive examples? We introduce MinSteer, a two-stage cached-continuation method for estimating a contrastive residual direction (CRD) within one decoding trajectory. Stage-X generates a continuation in one style; a style-flip suffix is then processed using Stage-X's final KV cache; Stage-Y continues from this inherited trajectory. The CRD is computed from generated-token residuals only, excluding prompt and suffix tokens from the average. Across sentiment transfer, politeness control, and a ParaDetox-based bidirectional diagnostic, MinSteer extracts effective steering directions from very small contrasts. On TweetEval sentiment transfer, one MinSteer contrast outperforms a CAA baseline averaged over 50 independent pairs. Japanese keigo CRDs transfer to English and Chinese outputs and outperform trajectory-free TwoSeq controls. In ParaDetox, MinSteer produces bidirectional Detoxify movement under our rewrite setup, while exposing semantic-preservation trade-offs. The directions transfer across tested scenarios and languages and show clear depth dependence. Together, these results show that cached self-rewrite trajectories provide a cleaner signal for residual-space behavior directions than independent-pair averaging.
MLS-Bench: A Holistic and Rigorous Assessment of AI Systems on Building Better AI
Bohan Lyu ⋅ Yucheng Yang ⋅ Siqiao Huang ⋅ Jiaru Zhang ⋅ Qixin Xu ⋅ Xinghan Li ⋅ Xinyang Han ⋅ Huaqing Zhang ⋅ Yicheng Zhang ⋅ Runhan Huang ⋅ Kaicheng Yang ⋅ Zitao Chen ⋅ Wentao Guo ⋅ Junlin Yang ⋅ Xinyue Ai ⋅ Wenhao Chai ⋅ Yadi Cao ⋅ Ziran Yang ⋅ Kun Wang ⋅ Dapeng Jiang ⋅ Huan-ang Gao ⋅ Shange Tang ⋅ Chengshuai Shi ⋅ Simon Du ⋅ Max Simchowitz ⋅ Jiantao Jiao ⋅ Dawn Song ⋅ Chi Jin
Modern AI progress has been driven by ML methods that are generalizable across settings and scalable to larger regimes. As large language models demonstrate advanced capabilities in reasoning, coding, and engineering tasks, it is increasingly important to understand whether they can discover such methods rather than only apply existing ones. We introduce MLS-Bench, a benchmark for evaluating whether AI systems can invent generalizable and scalable ML methods. MLS-Bench contains 140 tasks across 12 domains, each requiring an agent to improve one targeted component of an ML system or algorithm and demonstrate that the improvement generalizes across controlled settings and scales. We find that current agents remain far from reliably surpassing human-designed methods, and that engineering-style tuning is easier for them than genuine method invention. We further study the effects of test-time scaling, adaptive compute allocation, and context provision on agents' discovery performance, together with case studies of their behavior. Our analyses suggest that the bottleneck is not only in proposing new methods, but also in the scientific insight needed to plan, validate, and scale claims about them. More search, compute, or context alone does not remove this bottleneck. We build and maintain a community platform for cumulative and comparable iteration, and release the data and code at https://mls-bench.com.
MoBiQuant: Mixture-of-Bits Quantization for Token-Adaptive Any-Precision LLM
Dongwei Wang ⋅ Jinhee Kim ⋅ Seokho Han ⋅ Denis Gudovskiy ⋅ Yohei Nakata ⋅ Tomoyuki Okuno ⋅ KhayTze Peong ⋅ Kang E Jeon ⋅ Jong Hwan Ko ⋅ Yiran Chen ⋅ Huanrui Yang
Dynamic runtime latency and memory constraints necessitate flexible large language model (LLM) deployment, where an LLM can be inferred with various quantization precisions based on available computational resources. Recent work on such any-precision quantization either relies on hardware-inefficient vector quantization or induces additional scaling factors when switching between bit-widths. Meanwhile, existing post-training quantization (PTQ) methods calibrated for a fixed low precision show poor generalizability under runtime precision change. In this work, we attribute the source of poor generalization across bit-widths to a precision-dependent \textit{outlier migration} phenomenon where the distribution of PTQ-sensitive tokens changes across precisions. Motivated by this observation, we propose \texttt{MoBiQuant}, a novel any-precision Mixture-of-Bits quantization framework that adjusts weight precision for flexible LLM inference based on token sensitivity. Specifically, we propose a many-in-one recursive residual quantization that can iteratively reconstruct higher-precision weights at runtime and mitigates \textit{outlier migration} with a token-aware router to dynamically select the optimal inference precision of each token. Extensive experiments show that \texttt{MoBiQuant} matches or surpasses frontier single-precision PTQ while exhibiting strong elasticity, achieving significant memory savings and throughput gains of up to $1.34\times$ over state-of-the-art any-precision methods. Source code is provided in the supplementary material.
Mode-Controlled Policy Optimization: A Geometry-Aware Recipe for LLM Post-Training
Zhenyu Sun ⋅ Dylan Hadfield-Menell ⋅ Weiguo Feng ⋅ Xiaohuan Zhou ⋅ Yi Zeng
LLM post-training is usually framed as a choice of optimizer, but KL-regularized RL also makes a hidden geometric choice: it fits the learned policy to a reward-tilted target by reverse KL. This places PPO, GRPO, RLOO, REINFORCE++, and related methods at a fixed mode-seeking point in a broader design space. We propose \textbf{Mode-Controlled Policy Optimization (MCPO)}, a geometry-aware recipe that replaces this inherited point with an $\alpha$-divergence dial over mode-seeking versus mode-covering behavior; $\alpha{=}0$ recovers the classical reverse-KL recipe. MCPO admits an off-policy objective, a practical grouped importance-weighted estimator, and a baseline-centered variant for stable training. Across mathematical reasoning, agentic transfer, search-based QA, and safety, no single geometry is uniformly best. Average-case math favors stronger concentration, while pass-based math and Search-QA favor broader support; agentic transfer moves with metric and scale; safety exposes a base-dependent frontier in which the same refusal-only signal can transfer broadly or spill into benign boundary cases depending on the reference model's mode landscape. MCPO's value is therefore not a new universal objective, but a way to expose and select the post-training geometry that RL with fixed reverse-KL geometry silently chooses.
Model-Free Assessment of Simulator Fidelity via Quantile Curves
Yu-Shiou Lin ⋅ Kaizheng Wang ⋅ Garud Iyengar
As generative AI models are increasingly used to simulate real-world systems, quantifying their “sim-to-real” gap is critical. We study this gap across a population of input settings, called scenarios, e.g. survey questions or operating conditions. The population-level quantities defining the real-world and simulated system are only observed through finite, often heterogeneous, samples. Consequently, the population-level discrepancy cannot be directly computed, and standard predictive inference methods that target observable outputs are ill-suited. We propose a model-agnostic framework that constructs confidence sets for the latent parameters, forms a conservative proxy for the sim-to-real discrepancy, and estimates its quantile function across scenarios. The resulting calibrated risk profile allows for inference on a new scenario, tail-risk summaries such as Conditional Value-at-Risk (CVaR), and principled comparisons across simulators. Our method applies to a range of output spaces, including categorical survey responses and continuous outcomes. We demonstrate its utility by evaluating the alignment of four major LLMs with human populations on the WorldValueBench dataset.
Monotone Inclusion Approach to Weakly Monotone Discrete-Time Finite-Horizon Mean-Field Games
Ugur Aydin ⋅ Tamer Basar ⋅ Naci Saldi
We revisit the problem of computing mean-field equilibria (MFEs) in discrete-time, monotone, finite-horizon mean-field games (MFGs). We show that, when the transition kernel is independent of the state-measure term and the reward function satisfies the usual weak monotonicity condition and is Lipschitz continuous, anchored proximal gradient descent methods can be used to compute a monotone MFE. We also establish last-iterate convergence results for these methods. Our approach relies on formulating the computation problem as an optimization problem over the space of occupation measures. Using this formulation, we show that the problem is equivalent to a class of constrained Lipschitz monotone inclusion problems. We then apply iterative methods for this monotone inclusion formulation to derive a tractable algorithm. The resulting algorithm achieves a convergence rate of $O(1/\sqrt{T})$ after $T$ iterations, without requiring any regularization. This rate holds even in the absence of a uniqueness assumption for the corresponding MFE.
MPCI-Bench: A Benchmark for Multimodal Pairwise Contextual Integrity Privacy Evaluation of Language Model Agents
Shouju Wang ⋅ Haopeng Zhang
As language-model agents evolve from passive chatbots into proactive assistants that handle personal data, evaluating their adherence to social norms becomes increasingly critical, often through the lens of Contextual Integrity (CI). However, existing CI benchmarks are largely text-centric and primarily emphasize negative refusal scenarios, overlooking multimodal privacy risks and the fundamental trade-off between privacy and utility. In this paper, we introduce MPCI-Bench, the first Multimodal Pairwise Contextual Integrity benchmark for evaluating privacy behavior in agentic settings. MPCI-Bench consists of paired positive and negative instances derived from the same visual source and instantiated across three tiers: normative Seed judgments, context-rich Story reasoning, and executable agent action Traces. Data quality is ensured through a Tri-Principle Iterative Refinement pipeline. Evaluations of state-of-the-art multimodal models reveal systematic failures to balance privacy and utility and a pronounced modality leakage gap, where sensitive visual information is leaked more frequently than textual information.
Multi-Stage Planning from Single-Stage Data: Reinforcement Learning Helps Composition but Requires Anchoring
Boyuan Zheng ⋅ Zidong Liu ⋅ Yingyu Liang
Long-horizon planning often requires composing familiar local transitions while remaining grounded in a specified goal. We study this setting from single-stage data: on a controlled no-skip graph benchmark, training provides only adjacent-stage demonstrations while evaluation requires composing them on unseen long-horizon start–goal pairs; an event-chain diagnostic decomposes success into legality, stage-bridging, and goal-conditioned termination. Across a minimal Transformer, Qwen2.5-3B, and an external validation on MuSiQue multi-hop QA, supervised fine-tuning (SFT) learns local transitions but degrades with horizon, with failures localized to stage-bridging. Reinforcement learning (RL) narrows this composition gap, especially at longer horizons, but unanchored RL drifts—producing valid stage progress while ignoring the instructed target. Stable gains require two complementary forms of anchoring: instruction-style prompting strengthens prompt-side goal-conditioning, especially at shorter horizons, whereas KL regularization to the SFT reference policy prevents RL-induced drift across horizons; reward shaping mainly provides denser credit. Finally, we identify a Decomposition Paradox: models trained only on long compositions can reach intermediate targets yet fail the corresponding prefix subtasks because stopping at instructed intermediates is never supervised.
Multi-Turn RL Makes Small Language Model Competitive for Optimization Modeling
Xinzhi Zhang ⋅ Zeyi Chen ⋅ Humishka Zope ⋅ Hugo Barbalho ⋅ Konstantina Mellou ⋅ Marco Molinaro ⋅ Janardhan Kulkarni ⋅ Ishai Menache ⋅ Sirui Li
Mathematical optimization drives decisions in supply chains, logistics, energy, and scheduling, but translating natural-language problems into solver-executable formulations remains a bottleneck. While frontier models show promise for this task, many deployments require small language models (SLMs) that run locally under privacy, latency, and cost constraints. Existing SLMs are limited by noisy data, ambiguous benchmarks, and one-shot inference that ignores the iterative, feedback-driven nature of optimization modeling. We introduce \textsc{OptiMind}, a framework for improving SLMs through formulation-centric data cleaning, class-conditional priors, and multi-turn reinforcement learning with solver feedback. \textsc{OptiMind} repairs ambiguous problems, regenerates solution trajectories, audits benchmark labels, constructs accepted objective-value sets, and distills class-level hints from recurring formulation errors. It then trains models to formulate, execute, and revise GurobiPy programs using solver-verified correctness as reward. On expert-cleaned IndustryOR, Mamo-Complex, and OptMATH benchmarks, a 20B \textsc{OptiMind-RL} model outperforms strong open-source baselines and reaches frontier-model performance under the same protocol. Our results suggest that optimization formulation is better treated as an interactive solver-grounded decision process than as one-shot code synthesis. We release our inference framework, cleaned benchmarks, and sample error analyses at \url{https://anonymous.4open.science/r/OptiMind-NeurIPS-1DB020}, with full data and model to follow.
Nearest-neighbor methods are fundamental to classical and modern machine learning, yet their geometric properties are typically analyzed under independent sampling. In this paper, we study the nearest-neighbor radii under dependent sampling. We consider strong mixing dependent observations and ask whether dependence changes the scale of nearest-neighbor neighborhoods. We establish distribution-free almost sure convergence under polynomial mixing and sharp non-asymptotic moment bounds under geometric mixing. The moment bounds depend on the local intrinsic dimension rather than the ambient dimension, making the results applicable to high-dimensional data concentrated near lower-dimensional manifolds. Synthetic experiments and real-world time-series benchmarks support the theory, showing that nearest-neighbor geometry remains informative under dependence sampling.
Near-optimal Explainable $k$-means Clustering under $\ell_p$ Norm
Xinyuan Cao ⋅ Konstantin Makarychev ⋅ Ilias Papanikolaou ⋅ Liren Shan
We study explainable $k$-means clustering, introduced by Dasgupta, Frost, Moshkovitz, and Rashtchian (2020), and generalize it to $\ell_p$ norms. The goal is to find a clustering represented by a threshold decision tree while minimizing the $k$-means objective. Such a clustering is easy for humans to interpret because each internal node partitions the data by thresholding a single feature, so every cluster can be explained through a sequence of simple decisions. We give algorithms that find threshold trees with $(1+\delta)k$ leaves and competitive ratio $\tilde{O}_p(1/\delta\cdot \log^{2+2/p-2/p^2} k)$ for every finite $p \geq 2$ and $\tilde{O}(1/\delta \cdot d^{2/p-1}\log^2 k)$ for every $1 \leq p < 2$. For $1 \leq p < 2$, we show that this dependence on $d$ is unavoidable with less than $k^2/2$ leaves and provide an $\tilde{O}(\log^{2+2/p-2/p^2} k)$-competitive algorithm with $8k^2$ leaves. We also provide near-optimal algorithms for explainable $k$-means under $\ell_p$ norms with exactly $k$ leaves. Our algorithms achieve the price of explainability of $\tilde{O}(k)$ for every finite $p \geq 2$ and $\tilde{O}(d^{2/p-1} k)$ for $1\leq p \leq 2$. We complement these results with nearly matching lower bounds.
Neural-Corrected Operator Learning for Homogenization and Inverse Design
Guangyu Nie ⋅ Yang Jiao ⋅ Yi Ren
In the context of computational materials science, analytical homogenization theories, such as Strong Contrast Expansion (SCE), develop PDE-induced power expansions that map microstructural statistics of material samples to their macroscopic effective properties. However, low-order truncations of such expansions for computational feasibility often trade off prediction accuracy, especially when high-order correlations, finite-resolution effects, or strong contrast regimes become important. While learned residual surrogates, e.g., neural operators, can alleviate this tradeoff, they do not ensure reliable inference of structure-property sensitivities, hampering downstream material design tasks. To this end, we propose Neural-Corrected Operator (NCO) that learns a correction directly to the analytical PDE kernel to compensate for the low-order truncation, and show that NCO intrinsically bounds sensitivity inferences. We evaluate NCO on structure-property prediction and inverse-design tasks for heterogeneous bi-phase composite materials governed by linear second-order PDEs. NCO improves the accuracy of low-order SCE models for structure-property prediction and produces sensitivities that facilitate more effective microstructure design optimization than output-level residual baselines.
NeuronEye: Query-Guided Visual Concept Activation for Vision-Language Reasoning
Ruiyu Yan ⋅ Bowen Chen ⋅ Shaowen Wan ⋅ Lin Zhao
Current vision-language models (VLMs) encode visual information in dense hidden states where object identity, spatial layout, and local attributes are implicitly entangled rather than explicitly disentangled, limiting their ability to isolate and modulate the specific visual evidence required by a given language query. Inspired by sparse population coding and top-down modulation in biological vision, we introduce NeuronEye, a plug-in framework that constructs a sparse, concept-level neuron vocabulary from intermediate VLM representations and selectively activates query-relevant visual concepts during inference. NeuronEye decomposes vision-token states into an overcomplete sparse basis organized by concept-level clusters, uses the language query to activate relevant clusters and localize the patches where selected concepts are expressed, and injects the focused evidence back into vision tokens. A complementary suppression mechanism attenuates dominant perceptual directions to preserve weaker but relevant cues. All operations run in a single forward pass over a frozen VLM backbone. On Qwen2.5-VL-7B, NeuronEye raises CV-Bench overall accuracy by +3.1 with gains of +9.5 on Distance, and improves BLINK Multi-view by +8.3, with similar trends on LLaVA-1.6-7B. These results suggest that sparse neuron vocabularies can serve not only as post-hoc interpretability tools but also as active interfaces for concept-level visual reasoning.
Non-Colliding Biometric Identities for Digital Entities: Geometry, Capacity, and Million-Scale Virtual Identity Provisioning
Yuyang Ji ⋅ Yixuan Shen ⋅ Anil Jain ⋅ Xiaoming Liu ⋅ Feng Liu
Digital entities such as AI agents and humanoid robots increasingly operate alongside real humans, yet their identity infrastructure is based on credentials rather than embodied biometric identity. We introduce Biometric Identity Provisioning (BIP), a new problem and solution framework that addresses: given an enrollment gallery of real human identities, provision virtual identities that are non-colliding with every enrolled identity, maintain sufficient inter-class separability, and are realizable as high-fidelity face images. The key geometric insight is that real face identities occupy a low-dimensional subspace of the embedding hypersphere, leaving no residual subspace for virtual identities. Hence, virtual identities must instead be allocated as unclaimed gaps within the real face manifold itself. BIP is therefore a constrained packing problem: available gaps vastly exceed any foreseeable enrollment scale, and provisioned identities remain non-colliding even as new real identities are subsequently enrolled. Grounded in this geometry, our repulsion-based allocation is not bounded by any fixed provisioning count; we demonstrate 10M non-colliding virtual identity embeddings against a gallery of 360K real identities. Realizing these embeddings as face images requires a generator that operates outside the training distribution of real face images; we introduce GapGen, a gap-aware generator trained with a curriculum that progressively extends synthesis into non-colliding regions, validated at 1M photorealistic virtual face images. We further construct v-LFW, a virtual counterpart to LFW face dataset, with protocols for virtual face verification, cross-reality matching, real-vs-virtual detection, and unified recognition and detection.
Not Every Rubric Teaches Equally: Policy-Aware Rubric Rewards for RLVR
Utkarsh Tyagi ⋅ Xingang Guo ⋅ MohammadHossein Rezaei ⋅ Daniel George ⋅ Anas Mahmoud ⋅ Jackson Lee ⋅ Bing Liu ⋅ Yunzhong He
Reinforcement learning with verifiable rewards has made post-training effective when correctness can be verified automatically, but many useful model behaviors require satisfying several qualitative criteria rather than a single verifier. Rubric-based rewards extend RLVR to these open-ended domains by grading prompt-specific criteria and aggregating them into a scalar reward. However, the common static aggregations conflate a criterion's desired end-state importance with its current usefulness for learning. We show that this conflation is central in rubric RL: many criteria that matter to the final answer are already saturated or currently unreachable for the policy, while criteria with informative rollout variation are not reliably the ones assigned the largest human weights. We introduce a Policy-Aware Rubric Reward framework for RLVR, \textbf{POW3R}, that keeps human weights and reward category balance as the target objective while reallocating within-category training pressure toward criteria that distinguish the current rollouts. Across three base policies on each of two datasets spanning multimodal and text-only settings, POW3R takes first place on $27$ of $33$ (base policy, metric) cells we evaluate, leading both mean rubric reward and the harder strict ``every-rubric-passed'' pass-rate over vanilla GRPO with rubric-based rewards, and reaches the same plateau in $3$--$4\times$ fewer training steps. These findings suggest that rubric rewards should separate what should matter in the final answer from what can teach the current policy.
OmniGF: A Dual-Branch Vision-Language Framework for Unified Gaze Following
Qiaomu Miao ⋅ Haoyu Wu ⋅ Jingyi Xu ⋅ Minh Hoai ⋅ Dimitris Samaras
Understanding human gaze behavior is essential for complex scene comprehension and human-computer interaction. Traditional gaze following models are typically restricted to pure spatial localization, lacking the high-level capacity to reason about semantic targets or complex social contexts. Furthermore, these models often process individuals sequentially, requiring redundant computations over the same scene image for multi-person inference. While recent Vision-Language Models (VLMs) offer the exceptional semantic reasoning needed to address gaze-related semantic tasks, their reliance on discrete text generation inherently limits precision in continuous spatial tasks like gaze localization. To bridge this gap, we propose OmniGF, a unified vision-language framework that adapts foundational VLMs for highly scalable multi-person gaze reasoning. The model adopts a dual-branch decoding strategy: a structured language branch generates discrete reasoning states, while a continuous spatial branch directly taps into the VLM's dense hidden states. Supervising these extracted representations with high-resolution gaze target heatmaps effectively overcomes the spatial bottleneck of text-only coordinate generation. Furthermore, to explicitly ground the model in multi-person scenes, we augment the input with head embeddings encoded from cropped head images, providing fine-grained appearance and orientation cues for all individuals simultaneously. By modeling all individuals and leveraging the strong semantic capability of VLMs, OmniGF seamlessly integrates precise spatial gaze target estimation, semantic gaze prediction, and complex social gaze reasoning. Extensive experiments demonstrate that our framework establishes new state-of-the-art performance across multiple standard benchmarks.
Online Allocation with Differential Privacy
Jianyi Yang ⋅ Xingyu Zhou ⋅ Mostafa Mushsharat ⋅ Shaolei Ren
We study private online allocation problems, where allocation decisions must satisfy differential privacy (DP) to protect sensitive user information while optimizing performance under constrained resources. We first formalize differential privacy notions suited to different privacy requirements in online allocation and establish the fundamental performance limits of any algorithm under these definitions. Based on these insights, we propose PPOA, a privacy-preserving meta algorithm for online allocation, and establish sufficient conditions under which PPOA preserves Joint DP (JDP) or Local DP (LDP) while achieving asymptotically near-optimal performance. Building on these conditions, PPOA can be instantiated into a variety of concrete algorithms. In particular, we present the specific designs, which include PPOA-DMD that preserves JDP and LDP and PPOA-FTRL that preserves JDP. We analyze their performance under both adversarial and stochastic settings and characterize the fundamental trade-offs between DP and allocation performance. Finally, we demonstrate the superior performance of the proposed algorithms via numerical experiments on AI model routing in battery-powered edge systems.
On Neural Scaling Laws for Weather Emulation through Continual Training
Shashank Subramanian ⋅ Alexander Kiefer ⋅ Arnur Nigmetov ⋅ Amir Gholami ⋅ Dmitriy Morozov ⋅ Michael Mahoney
Neural scaling laws, which in some domains can predict the performance of large neural networks as a function of model, data, and compute scale, are the cornerstone of building foundation models in Natural Language Processing and Computer Vision. We study neural scaling in Scientific Machine Learning, focusing on models for weather forecasting. To analyze scaling behavior in as simple a setting as possible, we adopt a minimal, scalable, general-purpose Swin Transformer architecture, and we use continual training with constant learning rates and periodic cooldowns as an efficient training strategy. We show that models trained in this minimalist way follow predictable scaling trends and outperform standard cosine learning rate schedules. Cooldown phases can be re-purposed to improve downstream performance, e.g., enabling accurate multi-step rollouts over longer forecast horizons or sharper predictions through spectral loss adjustments. We also systematically explore a wide range of model and dataset sizes under various compute budgets to construct IsoFLOP curves, and we identify compute-optimal training regimes. Extrapolating these trends to larger scales highlights potential performance limits, demonstrating that neural scaling can serve as an important diagnostic for efficient resource allocation. We open-source our code for reproducibility.
Early prediction of chronic disease risk from electronic health records (EHRs) is challenging because early clinical signals are often sparse, noisy, and indirectly related to future outcomes. Existing methods typically learn from prediction-time records and final outcome labels alone, which provides limited supervision for identifying weak early signals from heterogeneous and confounded clinical records. LLM-generated rationales offer an intermediate form of prediction-time reasoning, but rationales derived from early EHR may still miss weak signals whose relevance becomes clearer only in later records. We therefore use follow-up EHR observed after the prediction time but before outcome assessment as training-time hindsight and propose On-Policy Hindsight Distillation (OPHD), a self-distillation framework that converts follow-up EHR into training signals for LLM-generated prediction-time rationales. Specifically, OPHD first uses an LLM to generate a rationale from prediction-time EHR alone, then re-evaluates the same rationale under privileged follow-up views to derive token-level signals that are distilled back to the prediction-time policy. To handle noisy follow-up records, OPHD emphasizes hindsight signals that are stable across perturbed privileged views. A task-grounded scorer further prioritizes rationales that improve downstream risk discrimination. Experiments on multiple real-world neurodegenerative disease cohorts show that OPHD achieves the best long-horizon prediction performance compared with a variety of baselines.
On the Complexity of Offline Reinforcement Learning with Q*-Approximation and Partial Coverage
Haolin Liu ⋅ Braham Snyder ⋅ Chen-Yu Wei
We study offline reinforcement learning under $Q^\star$-approximation and partial coverage, a setting that motivates practical algorithms such as Conservative $Q$-Learning (CQL) [KZTL20] but has received limited theoretical attention. Our work is inspired by the following open question: \emph{Are $Q^\star$-realizability and Bellman completeness sufficient for sample-efficient offline RL under partial coverage?} We answer this question in the negative through an information-theoretic lower bound. To identify additional structure that enables sample-efficient offline RL under partial coverage, we introduce a general decision-estimation framework, inspired by model-free decision-estimation coefficients (DEC) for online RL [FGO$^+$23, LWZ25b]. Our framework decomposes the complexity of offline RL into two parts: the \emph{decision complexity} and the \emph{value estimation error}. This decomposition allows us to study the two sub-problems in a modular way. Our result not only unifies existing results in the $Q^\star$-approximation and partial coverage regime [CJ22, UKLS23], but further improves and generalizes them. On the decision complexity side, our improvement includes: the first $\epsilon^{-2}$ sample complexity bound for soft $Q$-learning under partial coverage that improves [UKLS23]'s $\epsilon^{-4}$ bound, the removal of the need for additional online interaction in the gap-dependent setting of [CJ22], and new learnable settings beyond the above two cases. On the value estimation side, we provide the first characterization of offline learnability for general low-Bellman-rank MDPs [JKA$^+$17, DKL$^+$21, JLM21], a canonical online RL setting that has remained unexplored in offline RL outside special cases. As a side contribution, our techniques give the first analysis of CQL in the function approximation setting.
OpenBrain: An Auditable Generated-Label Release for Whole-Brain MRI Parcellation
Qizhen Lan ⋅ Yu-Chun Hsu ⋅ YUXIANG WEI ⋅ Lijing Zhu ⋅ Zenan Sun ⋅ Liang He ⋅ Lishan Yu ⋅ Xiaoqian Jiang
Automatic tools can now generate whole-brain MRI parcellations at cohort scale, but generated-label releases often provide little evidence about which cases are reliable enough to reuse. We introduce OpenBrain, a confidence-aware release of 35{,}838 provenance-verified OpenNeuro T1w cases from 607 source datasets. OpenBrain is organized as an auditable case-record release rather than a directory of standalone segmentation files: each record links a primary parcellation, two committee parcellations, source/license provenance, raw QC-7 measurements, source-local percentile risks, a combined risk score R, and a confidence tier. QC-7 is a reference-free reliability panel over label geometry, image-label consistency, and committee disagreement, so users can filter, weight, audit, or re-threshold generated labels without rerunning inference. We evaluate this released evidence under a frozen protocol. Across external cohorts, lower QC-7 risk corresponds to higher generated-label quality; in fixed-budget training, lower-risk selections improve paired macro Dice over random selection by +$3.2$ to $+3.7$ percentage points and substantially outperform high-risk-tail selection. OpenBrain also exposes raw axes, committee outputs, provenance, and datasheet documentation, so confidence claims remain inspectable after download. It does not turn generated labels into manual annotations or clinical-grade segmentations. Its contribution is a large open generated-parcellation substrate, a reusable case-level risk-evidence layer, and an external validation protocol for release-time QC.
Traditional differential privacy assumes each training example affects only one user's privacy, but many real-world datasets contain examples attributed to multiple users. We study \emph{fixed-graph differential privacy}, a framework for learning from such multi-attribution data where the attribution structure is public but example contents are private. We establish fundamental limits and optimal algorithms for this setting. First, we develop approximation algorithms for the NP-hard contribution bounding problem: a sampling-based LP-rounding algorithm achieving $O(|V|^{1/(k+1)})$-approximation and a greedy algorithm achieving $O(r)$-approximation, where $r$ is the maximum number of users per example. We prove matching hardness results showing the greedy bound is tight up to $O(\log r)$ factors. Second, we introduce a \emph{network density parameter} $c$ that measures how concentrated the attribution network is, and establish information-theoretic error lower bounds scaling as $\tilde\Omega(c^2d/\varepsilon^2)$ for learning $d$-dimensional models from $n$ examples. We provide matching upper bounds using contribution bounding combined with DP-SGD, demonstrating our algorithms are optimal. We further characterize when contribution bounding introduces selection bias and provide conditions under which bias vanishes. Finally, we extend our analysis to the i.i.d. setting where examples are sampled from a distribution, obtaining improved bounds scaling as $\tilde{O}(\sqrt{c/n})$ for hypothesis testing and providing matching algorithm for clustered networks.
Optimizer-Induced Mode Connectivity: From AdamW to Muon
Fangzhao Zhang ⋅ Sungyoon Kim ⋅ Erica Zhang ⋅ Yiqi Jiang ⋅ Mert Pilanci
Mode connectivity has been widely studied, yet the role of the optimizer remains underexplored. We revisit it through optimizer-induced implicit regularization, asking how connectivity behaves when restricted to solutions constrained by a given optimizer. For two-layer ReLU networks, we show that solutions from a single optimizer - AdamW, Muon, or others in the Lion-$\mathcal{K}$ family - form a connected set at sufficiently large width, a result not implied by prior work. We then characterize how optimizer-induced regions interact: at large width two different regions can be disjoint or overlap depending on regularization, while in our small-width example AdamW and Muon converge to disconnected zero-loss components separated by a provable loss barrier. Empirically, in GPT-2 pretraining, we observe same-optimizer paths preserve each model’s spectrum while cross-optimizer paths traverse a smooth transition. Our results reveal optimizer-dependent structure beyond classical mode connectivity literature.
Pacing Branch Parallelism in LLM Serving
Swapnil Gandhi ⋅ Siva Kumar Sastry Hari ⋅ Bill Dally ⋅ Christos Kozyrakis
Recent methods expose intra-request parallelism in LLM outputs, allowing independent branches to decode concurrently. Existing serving systems execute these branches eagerly or under fixed caps. We show that both are brittle: eager admission inflates the shared decode step, degrading co-batched requests in serial stages, while conservative fixed caps forgo the throughput that motivated exposing branches in the first place. We call the excess step latency caused by admitted branches the \emph{branch externality} and show that the safe width depends on batch composition, context lengths, and accumulated slack, all of which change continuously over a workload trace. We introduce \textsc{Pace}, a per-step admission controller that treats extra branches as opportunistic work, admitted only when the predicted branch externality fits within the batch's current slack budget. Per-step regulation is practical because branch-level scheduling decouples compute from memory: branches share the request's prefix KV, so expanding or contracting width requires no memory reclamation. On Qwen3-32B, \textsc{Pace} improves goodput by $1.77\times$ over \textsc{IRP-Off} and by $1.48\times$ over \textsc{IRP-Eager}, while maintaining over 95\% SLO attainment.
Partition-Aware Unlearning for Removing Spurious Correlations in Large Vision-Language Models
Aditi Sarker ⋅ Nazreen Shah ⋅ Rafi Ibn Sultan ⋅ Rhongho Jang ⋅ Dongxiao Zhu ⋅ Prashant Khanduri
Large Vision-Language Models (LVLMs) achieve strong performance across many multimodal tasks; however, they often exploit spurious object-background correlations, resulting in predictions driven by contextual shortcuts rather than object-relevant visual evidence. Despite growing interest in hallucination and robustness evaluation, existing benchmarks provide limited control over whether model predictions are grounded in the target object or induced by correlated background cues. In this work, we introduce PURGE (Partition-aware Unlearning for Removing spurious-correlation Generated Errors), a framework for constructing, benchmarking, and mitigating spurious-correlation-induced failures in LVLMs. The framework consists of two components: (1) Structured dataset construction, wherein we develop three complementary structured data construction strategies that partition examples by object-relevant evidence and spurious background cues, enabling controlled diagnosis of shortcut reliance; and (2) Partition-aware unlearning, which uses these partitions to selectively remove spurious object-background associations while preserving object-based reasoning. We evaluate the PURGE framework across multiple LVLMs, including LLaVA-1.6-7B, Qwen3-VL-8B-Instruct, and Qwen3.5-9B, together with CLIP as a vision-language encoder, on a diverse suite of benchmarks, including CHAIR, POPE, Causal-HalBench, MM-SpuBench, AMBER, MMHal, and Waterbirds. Our results show that PURGE consistently reduces hallucinations and spurious-correlation-driven errors while maintaining or improving overall performance, providing both a reusable evaluation protocol and an effective mitigation framework for more reliable LVLMs.
pCoMole: Pareto-Constrained Molecule Editing with Discrete Flows
Tong Chen ⋅ Maximilian Holsman ⋅ Lin Zhao ⋅ Yinuo Zhang ⋅ Pranam Chatterjee
Biomolecular therapeutics often start from known sequences and require targeted editing to improve multiple properties while satisfying hard biochemical and manufacturability constraints. Existing generative methods do not jointly support multi-objective optimization, hard feasibility, and sequence editing in discrete, variable-length biological spaces. We introduce Pareto-Constrained Molecule editing (pCoMole), a framework built on discrete flow matching that steers a pre-trained Edit Flow toward user-specified preferences while enforcing terminal feasibility. pCoMole defines a feasibility-gated terminal distribution using an augmented Tchebycheff utility and realizes the resulting preference tilt through a Doob-h transform of the underlying edit process. To make this construction practical, we approximate the required harmonic function using short Monte Carlo rollouts over candidate edits, yielding an efficient guided editor with provable preference consistency. We validate pCoMole by shrinking GFP while retaining fluorescence-related properties, shortening diverse Cas9 orthologs while preserving PAM specificity, and compressing peptide binders into short peptidomimetics that optimize seven drug-related properties under hard constraints. Overall, pCoMole enables constraint-aware, Pareto-aligned editing of biomolecular sequences in discrete, variable-length spaces.
PermuQuant: Lowering Per-Group Quantization Error by Reordering Channels for Diffusion Models
Yongsen Cheng ⋅ Kai Liu ⋅ Kaiwen Tao ⋅ Junxian Li ⋅ Zhixin Wang ⋅ Zhikai Chen ⋅ Renjing Pei ⋅ Yulun Zhang
Large-scale visual generative models have achieved remarkable performance. However, their high computational and memory costs make deployment challenging in resource-constrained scenarios, such as interactive applications and personal single-GPU usage. Post-training quantization (PTQ) offers a practical solution by compressing pretrained models without expensive retraining. However, existing PTQ methods still suffer from severe quality degradation under extremely low-bit settings. In this paper, we identify channel ordering as an important but underexplored factor in per-group quantization. In this setting, each contiguous group shares one quantization scale. When channels with very different statistics are placed in the same group, the scale can be dominated by outliers and cause large quantization errors. Based on this observation, we propose PermuQuant, a simple and effective PTQ framework for low-bit diffusion models. PermuQuant sorts channels by a joint second-moment criterion before per-group quantization, placing channels with similar activation and weight statistics into the same group. It further uses a calibration-based acceptance rule to apply reordering only when the selected permutation reduces quantization error on calibration data. The selected permutations are absorbed into adjacent modules or applied to weights offline, avoiding explicit runtime permutation operations. Extensive experiments on multiple large diffusion models show that PermuQuant consistently reduces quantization error and outperforms existing PTQ baselines. On FLUX.1-dev with an NVIDIA RTX 5090, PermuQuant achieves up to a 1.8$\times$ single step speedup and reduces the DiT memory footprint by 3.5$\times$ under W4A4 NVFP4 quantization.
Personalized and Collaborative Online LQR via Thompson Sampling
Shivam Bajaj ⋅ Prateek Jaiswal ⋅ Vijay Gupta
Reinforcement learning (RL) is well known to be data-intensive, and recent works have proposed leveraging data from similar systems to improve sample efficiency. In this work, we focus on the collaborative Linear Quadratic Regulator (LQR) setting and study the problem of learning under heterogeneous system dynamics. Due to the presence of a heterogeneity-induced additive bias, most existing collaborative methods are suitable only for low heterogeneity regimes and exhibit suboptimal performance under large heterogeneity. Based on the principle of Thompson sampling (TS), we propose an algorithm that, by leveraging data from other agents, yields a \emph{personalized} controller for every agent without incurring any additive heterogeneity-induced bias, i.e., with sublinear Bayes regret even under large heterogeneity. Under high heterogeneity regimes, we establish that our algorithm incurs $\tilde{\mathcal{O}}( T^{1-0.5\epsilon}\sqrt{\Delta})$ cumulative regret, where $T$ denotes the time horizon, $\epsilon\in[0,1]$ is a user-defined personalization parameter, and $\Delta$ denotes an upper bound on the maximum dissimilarity among the agents' dynamics. Our algorithm and analysis also generalize the special case of no heterogeneity. In particular, under no heterogeneity, we establish that our algorithm incurs $\mathcal{O}(\sqrt{T/M})$ cumulative regret. From a distributed implementation perspective, our method incurs only logarithmic communication overhead. Additionally, our algorithm outperforms methods that do not personalize data from other agents and, in certain regimes, also outperforms methods that do not utilize any data from other agents.
Bayesian persuasion, a central model in information design, studies how a sender, who privately observes a state drawn from a prior distribution, strategically sends a signal to influence a receiver's action. A key assumption is that both sender and receiver share the precise knowledge of the prior. Although this prior can be estimated from past data, such assumptions break down in high-dimensional or infinite state spaces, where learning an accurate prior may require a prohibitive amount of data. In this paper, we study a learning-based variant of persuasion, which we term persuasive prediction. This setting mirrors Bayesian persuasion with large state spaces, but crucially does not assume a common prior: the sender observes covariates $X$, learns to predict a payoff-relevant outcome $Y$ from past data, and releases a prediction to influence a population of receivers. To model rational receiver behavior without a common prior, we adopt a learnable proxy: *decision calibration*, which requires the prediction to be unbiased conditioned on the receiver's best response to the prediction. This condition guarantees that myopically responding to the prediction yields no swap regret. Assuming the receivers best respond to decision-calibrated predictors, we design a provably efficient algorithm that learns a decision-calibrated predictor within a randomized predictor class that optimizes the sender's utility. In the commonly studied single-receiver case, our method matches the utility of a Bayesian sender who has full knowledge of the underlying prior distribution. Finally, we extend our algorithmic result to a setting where receivers respond stochastically to predictions and the sender may randomize over an infinite predictor class.
POME: Post Optimization Model Edit via Muon-Style Projection
Yong Liu ⋅ di fu ⋅ Yang Luo ⋅ Zirui Zhu ⋅ Minhao Cheng ⋅ Cho-Jui Hsieh ⋅ Yang You
We introduce Post-Optimization Model Edit (POME), a new algorithm that enhances the performance of fine-tuned large language models using only their pretrained and fine-tuned checkpoints, without requiring extra data or further optimization. The core idea is to apply a muon-style projection to $\Delta W$, the difference between the fine-tuned and pretrained weights. This projection uses truncated singular value decomposition (SVD) to equalize the influence of dominant update directions and prune small singular values, which often represent noise. As a simple post-processing step, POME is completely decoupled from the training pipeline. It requires zero modifications and imposes no overhead, making it universally compatible with any optimizer or distributed framework. POME delivers consistent gains, boosting average performance by +2.5\% on GSM8K and +1.0\% on code generation. Its broad applicability—from 7B foundation models to 72B RLHF-instructed models—establishes it as a practical, zero-cost enhancement for any fine-tuning pipeline.
Position: AI-Agent Pricing Should Become More Outcome-Dependent: An Economic Perspective
Yuheng Bu ⋅ Yueyuan Ma
AI agents have advanced rapidly and are increasingly sold as services, yet dominant pricing models still reward observable usage rather than the outcomes users actually value. This position paper argues that AI-agent pricing should become more outcome-dependent as markets mature, especially in domains where success can be measured objectively. Our position is motivated by three factors. First, pricing is a risk-sharing mechanism: when users are more risk-averse than AI-agent providers, outcome-dependent contracts can improve welfare by reallocating risk more efficiently. Second, token-based pricing under-incentivizes hidden effort, such as verification, tool use, and model selection, thereby creating moral hazard. Third, outcome-dependent pricing is often difficult to implement because performance measures may be noisy, delayed, or strategically manipulated. Using stylized principal-agent models from economics, we show how these forces shape the case for outcome-dependent pricing and why hybrid contracts that combine usage-based charges with outcome-dependent terms are often more practical than either token-only or pure pay-for-performance schemes. Overall, we argue that moving beyond token-only pricing is necessary for allocating risk more efficiently, aligning incentives, and building more trustworthy AI-agent markets.
Position: Reconciling Open Access with Owner Control in AI Model Distribution Deserves More Research Effort
Zerui Cheng ⋅ Edoardo Contente ⋅ Benjamin Finch ⋅ Oleg Golev ⋅ Jonathan Hayase ⋅ Andrew Miller ⋅ Niusha Moshrefi ⋅ Anshul Nasery ⋅ Sewoong Oh ⋅ Himanshu Tyagi ⋅ Pramod Viswanath
The rapid rise of AI has seen the coexistence of open-weight models and closed-source, API-based deployment, each with its own strengths and limitations. A growing share of deployment scenarios needs both local, customizable execution and owner-side accountability, yet neither extreme serves them well. Such scenarios include on-prem enterprise use with sensitive data, edge and offline robotics, and local fine-tuning or retrieval-augmented generation. This position paper argues that the middle regime between closed APIs and open-weight release deserves a principled deployment-level primitive of its own, and proposes OML—Open, Monetizable, Loyal—as a starting point for that primitive. An OML-formatted artifact aims to be simultaneously Open (open-weight and locally executable), Monetizable (usage is accountable to the owner), and Loyal (owner-declared use constraints are enforceable). Throughout, "open" refers to open-weight, locally executable artifacts rather than to fully open-source release, and "loyal" refers to owner-declared use constraints rather than to remote control over a running model. We articulate the desirable properties and threat model for OML, survey theoretical and practical constructions across software, hardware, and cryptographic primitives, and outline an end-to-end deployment protocol together with market-based and policy alternatives. We then describe OML 1.0, a low-overhead instantiation based on AI-native fingerprinting, and characterize the regime in which it provides meaningful guarantees. We close with a research agenda calling on the ML, cryptography, systems, and mechanism-design communities to refine the primitives needed to make OML deployable at scale.
Precise Debugging Benchmark: Is Your Model Debugging or Regenerating?
Miaosen Chai ⋅ Wang Bill Zhu ⋅ Shangshang Wang ⋅ Yejia Liu ⋅ Song Bian ⋅ Honghua Dong ⋅ Willie Neiswanger ⋅ Robin Jia
Unlike code completion, debugging requires localizing faults and applying targeted edits. We observe that frontier LLMs often hack unit tests by regenerating correct but over-edited solutions during debugging. To evaluate how far LLMs are from precise debugging, we introduce Precise Debugging Benchmarking (PDB), a general, dataset-agnostic framework that converts any coding dataset into a debugging benchmark with precision-aware evaluation. PDB generates buggy programs by synthesizing verified atomic bugs and composing them into multi-bug programs. We define two novel metrics, edit-level precision and bug-level recall, which measure how many necessary edits are made and how many bugs are resolved. We release two evaluation benchmarks: PDB-Single on single-line bugs and PDB-Wild on multi-line and repository-level bugs. Experiments show that frontier models, such as GPT-5.1-Codex and DeepSeek-V3.2-Thinking, achieve unit-test pass rates above 76% but exhibit precision below 45%, even when explicitly instructed to perform minimal debugging on single-line bugs. Iterative and agentic debugging strategies do not substantially improve precision or recall, highlighting the need to rethink post-training pipelines for coding models.
Predictive–Generative Drift Decomposition for Speech Enhancement and Separation
Julius Richter ⋅ Yoshiki Masuyama ⋅ Christoph Boeddeker ⋅ Takahiro Edo ⋅ Gordon Wichern ⋅ Jonathan Le Roux
We propose a plug-and-play framework for speech enhancement and separation that augments predictive methods with a generative speech prior. Our approach, termed Stochastic Interpolant Prior for Speech (SIPS), builds on stochastic interpolants and leverages their flexibility to bridge predictive and generative modeling. Specifically, we decompose the interpolation dynamics into a task-specific drift and a stochastic denoising component, allowing a predictive estimate to be integrated directly into the generative sampling process. This results in a mathematically grounded framework for combining strong pretrained predictors with the expressive power of generative models. To this end, we train a score model using only clean speech, yielding a degradation-agnostic prior that can be reused across tasks. During inference, the predictor provides a deterministic drift that steers the sampling process toward a task-consistent estimate, while the score model preserves perceptual naturalness. Unlike prior hybrid approaches, which typically rely on architecture-specific conditioning and are tied to particular predictors or degradation settings, SIPS provides a unified framework that generalizes across predictors and additive degradation tasks. We demonstrate its effectiveness for both speech enhancement and speech separation using recent predictors such as SEMamba and FlexIO. The proposed method consistently improves perceptual quality, achieving gains up +1.0 NISQA for speech separation.
Primal Generation, Dual Judgment: Self-Training from Test-Time Scaling
Yizhu Jiao ⋅ Ruixiang Zhang ⋅ Richard H Bai ⋅ Jiawei Han ⋅ Ronan Collobert ⋅ Yizhe Zhang
Code generation is typically trained in the \emph{primal} space of programs: a model produces a candidate solution and receives sparse execution feedback, often a single pass/fail bit. Test-time scaling enriches the inference procedure by sampling multiple candidates and judging among them, but the comparative information this process reveals is discarded after inference. We argue that this information defines a \emph{dual} judgment space that provides a far richer training signal: the model learns not from an isolated success or failure, but from the relative correctness structure across its own plausible attempts, identifying which succeed, which fail, and what distinguishes them. We introduce \textbf{DuST} (\textbf{Du}al \textbf{S}elf-\textbf{T}raining), a framework for self-training from the dual judgment space. DuST samples candidate programs from the model's own distribution, labels them through sandbox execution, retains groups containing both successes and failures, and trains the model to rank candidates by execution correctness using GRPO. The objective is purely discriminative: the model is never directly rewarded for generating correct programs. Dual self-training improves both judgment and generation. Across five models spanning two families and three scales (4B to 30B), DuST consistently improves Best-of-4 test-time scaling on LiveCodeBench. For Qwen3-30B-Thinking on LiveCodeBench v6, judgment quality improves by +6.2 NDCG, single-sample pass@1 improves by +3.1, and Best-of-4 accuracy improves by +4.1. The trained model's single rollout matches the base model's Best-of-4 performance. SFT on the same ranking data improves judgment without improving generation, confirming that on-policy RL is the mechanism that transfers dual-space learning back into primal generation.
Private Adaptive Covariance Estimation via Gaussian Graphical Models
Cecilia Ferrando ⋅ Miguel Fuentes ⋅ Brett Mullins ⋅ Cameron Musco ⋅ Daniel Sheldon
We propose PACE-GGM, a data-adaptive differentially private method for covariance estimation that concentrates its privacy budget on the most informative entries of the empirical covariance matrix, rather than perturbing all entries. This applies in the natural setting where the modeler supplies separate bounds for each variable, so that individual entries can be measured with less noise than the full matrix. In each round, our method selects a poorly approximated entry, measures it using the Gaussian mechanism, and then reconstructs a full covariance matrix using a maximum-entropy reconstruction objective, leading to a Gaussian graphical model structure. Experiments on diverse real-world datasets demonstrate consistent improvements in estimation error with respect to the Gaussian mechanism and other baselines, particularly in high-dimensional and low-to-moderate privacy regimes.
Progress-Aware Distillation for Mitigating Stagnation in Small Language Model Agents
Yuanpu Cao ⋅ Saket Sathe ⋅ Hanyu Wang ⋅ Ziyi Yin ⋅ Fenglong Ma ⋅ Jinghui Chen
While LLM-based agent systems have demonstrated remarkable proficiency in reasoning and solving complex real-world tasks, they also come with substantial token consumption and inference latency, limiting their practical deployment. To enhance the efficiency of agent systems, recent efforts have focused on transferring agentic capabilities from large-scale models to small language models (SLMs) via supervised fine-tuning-based distillation. Nevertheless, as interaction trajectories grow longer, involving extended reasoning-action chains and extensive environmental feedback, distilled student agents tend to experience progress stagnation: becoming trapped in unproductive loops characterized by persistent failed strategies and difficulty making meaningful progress. Our systematic analysis shows that this phenomenon consistently occurs across diverse SLMs and task domains. To address this issue, we propose Progress-Aware Distillation (ProD), which explicitly detects and penalizes stagnation in student-generated trajectories. ProD encodes the stagnation gap between student and teacher into an adaptive margin for dynamically penalizing possible stagnation. By iteratively applying this procedure, ProD enables student agents to progressively approximate teacher behavior. Extensive experiments involving 8 SLMs, ranging from 0.6B to 8B parameters, on both in-domain and out-of-domain benchmarks, demonstrate that ProD substantially mitigates progress stagnation while enhancing both the success rates and task-completion efficiency of distilled SLM agents.
Projection Learning: A Principled Way to Overcome Memorization in Distribution Learning
Lin Chen ⋅ Dejan Slepcev
We introduce a framework for learning distributions supported on manifolds based on estimating the projection onto the underlying data manifold. Specifically, we define an objective functional over a class of functions whose minimizer recovers this projection. The proposed framework automatically adapts to the intrinsic dimension and allows for data supported on unions of manifolds with varying dimensions. The resulting objective can be optimized using standard neural network architectures. We present population-level results establishing recovery of the manifold projection and prove finite-sample Wasserstein generalization bounds. Furthermore, we validate the approach empirically across a range of settings. In contrast to widely used generative models such as diffusion models, whose objectives can be minimized by memorizing training samples, our formulation penalizes such behavior. Thus, returning training data does not yield low loss. We also introduce a direct memorization metric to verify that the learned projection generates new samples rather than reproducing the training set.
ProjKAN: Model Compression via KAN Projections to Bridge the Hypothesis and Capacity Gaps
Ferhat Arslan ⋅ Weihong Guo ⋅ Shuo Li
Multilayer perceptron (MLP)-based model compression often overlooks two distinct sources of error: the hypothesis gap and the capacity gap. The hypothesis gap arises from approximation error induced by selecting a student hypothesis class that is mismatched to the teacher function, while the capacity gap captures the additional error introduced by enforcing a limited parameter budget within the chosen class. We show that Kolmogorov–Arnold Networks (KANs) can reduce the hypothesis gap for smooth low-dimensional target functions. Furthermore, width and depth constraints in KANs allow within-family compression to be formulated as a convex projection problem that directly targets the capacity gap. Building on this formulation, we derive projection-based algorithms for width and depth reduction, as well as a function transfer method that maps a trained MLP teacher into a compact KAN student. These are unified in the Gap-aware Projections via KANs (ProjKAN) framework, which integrates the error decomposition, theoretical guarantees, and compression algorithms into a single methodology. Empirically, in regimes where pruning and standard knowledge distillation degrade sharply, ProjKAN achieves improved accuracy–size tradeoffs, reduced train–test gaps, and greater robustness in data-scarce settings.
Proximal Difference-in-Differences for Long-Term Causal Learning under Confounding and Outcome Drift
Sihyung Park ⋅ Shu Yang ⋅ Mingyang Shan ⋅ Wenyu Ye ⋅ Ilya Lipkovich
Estimating long-term treatment effects is essential for scientific and industrial evaluation, yet the limited follow-up duration of randomized controlled trials (RCTs) poses a significant challenge. Even the growing use of open-label extensions fails to resolve this issue, as such designs systematically censor long-term control trajectories. While supplementing RCTs with real-world evidence is a common strategy, existing methods often rely on restrictive exchangeability assumptions that fail under latent confounding. We propose a novel proximal framework to integrate long-term real-world evidence into RCTs with open-label extensions. Our approach successfully identifies long-term effects even in the presence of time-varying latent confounding effects and inter-study outcome drift. We provide a doubly robust locally efficient estimator that provides further resilience to model misspecification. Empirical results demonstrate that our framework maintains validity in complex data-generating processes that compromise standard approaches.
Prune, Don’t Rebuild: Efficiently Tuning $\alpha$-Reachable Graphs for Nearest Neighbor Search
Zachary Ives ⋅ Jiaming Liang ⋅ Ashwin Padaki ⋅ Erik Waingarten ⋅ Tian Zhang
Over the past decade, graph-based approximate nearest neighbor (ANN) algorithms, such as DiskANN (Jayaram Subramanya et al., 2019) and HNSW (Malkov & Yashunin, 2018), have demonstrated state-of-the-art empirical performance. Recent theoretical works (Indyk & Xu, 2023; Gollapudi et al., 2025) introduce the framework of $\alpha$-reachability to obtain worst-case performance guarantees for DiskANN; here, the reachability parameter $\alpha$ gives a trade-off between construction time, query time, and accuracy. In this work, we propose RP-TUNING, an efficient and simple post-hoc algorithm, based on DiskANN's pruning step, and show that (1) Theoretically, efficiently adjusting the reachability of an $\alpha$-reachable graph is possible via pruning: RP-TUNING preserves worst-case reachability guarantees in general metrics and improved guarantees in Euclidean metrics. (2) Empirically, RP-TUNING accelerates DiskANN tuning on four datasets by up to 73$\times$ with varied performance trade-offs compared to fully rebuilt graphs.
Quest: Training Frontier Deep Research Agents with Fully Synthetic Tasks
Jian Xie ⋅ Tianhe Lin ⋅ Zilu Wang ⋅ Yuting Ning ⋅ Yuekun Yao ⋅ Tianci Xue ⋅ Zhehao Zhang ⋅ Zhongyang Li ⋅ Kai Zhang ⋅ Yufan Wu ⋅ Shijie Chen ⋅ Boyu Gou ⋅ Mingzhe Han ⋅ Yifei Wang ⋅ Vint Lee ⋅ Xinpeng Wei ⋅ XJ Wang ⋅ Yu Su ⋅ Huan Sun
Deep research agents extend the role of search engines from retrieving keyword-matched pages to synthesizing knowledge, fundamentally changing how humans interact with information. However, frontier systems remain proprietary, while existing open agents often generalize poorly across different task types, leaving unclear how to train a broadly capable deep research agent. We release Quest, a family of open models (ranging from 2B to 35B) that serve as general-purpose deep research agents designed to handle a wide range of search tasks, with strong capabilities in fact seeking, citation grounding, and report synthesis. To build Quest, we propose an effective training recipe combining mid-training, supervised fine-tuning, and reinforcement learning. Central to this recipe is a curated data synthesis pipeline based on unified rubric trees, which applies to different task types and enables synthesizing training data with verifiable rewards without human annotation. In addition, Quest incorporates a built-in context management mechanism that enables effective long-horizon reasoning and knowledge synthesis. Using only 8K synthesized tasks, Quest approaches or even surpasses frontier closed-source agents across eight deep research benchmarks spanning diverse task types, and achieves the best overall performance among recent open-weight agents. Notably, Quest-35B achieves 30.7\% on Mind2Web 2, outperforming OpenAI DeepResearch (28\%) and Gemini DeepResearch (18\%). We plan to release all the resources for further research.
RA$^2$: Retain-Anchored Attraction Preserves Forget-Adjacent Utility in LLM Unlearning
Zinan Ling ⋅ Yang Xiao ⋅ Ruimeng Ye ⋅ Sijia Liu ⋅ Bo Hui
Unlearning in Large Language Model (LLM) is often evaluated primarily by target suppression and clean retain utility. These metrics can miss a local failure mode: a model may perform well on standard retain prompts, yet degrade on benign reasoning when prompts lie near the forgotten domain. This phenomenon is termed **forget-adjacent utility** loss. A fundamental question is: where should forget representations go after they leave the removed behavior? Successful unlearning depends not only on whether forget-conditioned representations depart from the harmful computation, but also on the direction in which they are redirected afterward. We propose **RA$^{2}$ (Retain-Anchored Attraction)**, a latent-space unlearning method that redirects forget-token states toward nearby retain-supported representations while preserving higher-layer behavior on retain data. On WMDP and MUSE, RA$^2$ yields higher forget-adjacent utility than strong unlearning baselines at similar broad-utility levels. These results show that the migration direction of forget representations materially affects benign behavior near the forget boundary. Our code is available at https://anonymous.4open.science/r/eaxvwertdq.
Rate-Constrained Edge Metadata for Sender–Receiver Generative Video Super-Resolution
Jiaqi Guo ⋅ Mingzhen Li ⋅ Haohong Wang ⋅ Aggelos Katsaggelos
Real-world television and streaming pipelines often deliver compressed HD video to increasingly capable displays, making video super-resolution (VSR) both practically important and fundamentally ambiguous. Existing generative VSR methods are largely receiver-only, requiring the model to infer missing high-frequency structures from degraded pixels alone. We propose MetaVSR, a sender--receiver collaborative framework that transmits compact structural edge metadata as bitrate-constrained side information for generative VSR. MetaVSR builds on a one-step video diffusion transformer and encodes both the low-quality video and transmitted metadata through the native 3D VAE, enabling token-level fusion within the original DiT attention blocks without additional control branches. We further introduce a rate-aware Canny edge metadata selection strategy that allocates metadata bits to structurally challenging regions, and evaluate reconstruction quality under matched total transmission budgets that include both compressed video and metadata. Across five public VSR benchmarks, MetaVSR shows that budgeted sender-side structural metadata can improve reconstruction over the receiver-only DOVE-5B baseline, increasing PSNR by 1.03 dB and SSIM by 0.055 on average while using a smaller 2B backbone. On MetaSPS, our rate--distortion evaluation shows approximately 20\% rate saving under light-noise degradation and more than 50\% under heavy-noise degradation compared with a no-metadata generative baseline. These results demonstrate that compact sender-side edge metadata can reduce reconstruction ambiguity and improve bitrate-efficient VSR when its transmission cost is explicitly accounted for.
Understanding the reliability of large language models (LLMs) has recently garnered significant attention. Given LLMs' propensity to hallucinate, as well as their high sensitivity to prompt design, it is already challenging to predict the performance of an individual LLM. However, the problem becomes more complex for compound LLM systems such as cascades, where in addition to each model's standalone performance, we must understand how the error rates of different models interact. In this paper, we present a probabilistic model for the joint performance distribution of a sequence of LLMs, which enables a framework for rationally tuning the confidence thresholds of a LLM cascade using continuous optimization. Compared to selecting confidence thresholds using Bayesian optimization, our parametric Markov-copula model yields more favorable error-cost trade-offs, improving the area under the error-cost curve by 4.3% on average for cascades with k ≥ 3 models. In the low-sample regime with n ≤ 30 training examples, the performance improvement widens to 10.2%, suggesting that our framework's inductive assumptions about the interactions between the error rates of different LLMs enhance sample efficiency. Overall, our Markov-copula model provides a rational basis for tuning LLM cascade performance and points to the potential of probabilistic methods in analyzing systems of LLMs.
RATS! Patches Talk Through Registers: Emergent Parts in Register Attention Transformers
Timing Yang ⋅ Predrag Neskovic ⋅ Jansen Seheult ⋅ Wenchao Han ⋅ Anand Bhattad ⋅ Alan Yuille ⋅ Feng Wang
When humans see a bird, they recognize far more than just ``bird'' --- they see a head, wings, and talons, a structured assembly of reusable parts that can be identified across every bird they have ever seen. We ask whether a self-supervised visual model can discover the same compositional structure on its own. To this end, we propose $RATS$ ($R$egister $A$ttention $T$ransformer$s$), which decomposes the classification token into $N$ learnable register tokens that route patch information through an $L{\to}N{\to}N{\to}L$ bottleneck. The $N$ registers are hard-partitioned across $H$ attention heads, structurally isolating each subset in an independent projection subspace. Without auxiliary losses or part annotations, each register spontaneously specializes into a semantically coherent visual part. RATS surpasses all baselines by an average of +12 mIoU on five segmentation benchmarks, and demonstrates stronger dense prediction on ADE20K (+1.11 mIoU) and COCO (+0.2 AP$^{\text{m}}$). The visual dictionary extracted from the trained registers also shows signs of part-level consistency and semantic proximity across related categories. Our results suggest that RATS may provide a useful architectural prior for structured and interpretable visual representation learning.
Recreating Video Arenas via Automated Preference Scoring
Yue Zhao ⋅ Aniket Gupta ⋅ Juze Zhang ⋅ Tiange Xiang ⋅ Ryan Rong ⋅ Xuan Su ⋅ Fei-Fei Li ⋅ Ehsan Adeli
Evaluating video generation models is notoriously challenging; existing metrics either fail to align with human judgment or rely on costly, unscalable human ratings. In this work, we introduce \textbf{Video Preference Score} (VPS), a fully automated video preference score designed to directly model human judgment and accurately recreate large-scale, Elo-based video arenas. Trained on a newly collected dataset that augments generated videos with retrieved real-world footage, VPS evaluates paired videos against complex text prompts to predict human preference. Experiments demonstrate that VPS correlates highly with human consensus and generalizes zero-shot across unseen models and benchmarks. Furthermore, we showcase the utility beyond evaluation: as a plug-in reward model, VPS seamlessly integrates with Flow-GRPO to improve WAN-2.1's generative quality by 51 Elo points. Overall, VPS provides a scalable and generalizable solution for both evaluating and aligning modern video generation models.
RefineTok: Scale-Wise Tokenization for Progressive Visual Refinement
Yitian Zhang ⋅ Long Mai ⋅ Yizhou Wang ⋅ Yun Fu
Image tokenization aims to compress visual signals into latent codes that remain effective for reconstruction and generation. Driven by the multi-scale nature of images, organizing latent along a coarse-to-fine refinement process emerges as a promising direction for visual tokenization. Existing scale-wise tokenizers often introduce this structure through token ordering or latent prefixes, but each target scale is typically decoded directly from its prefix, making different prefixes behave like separate reconstruction codes. This can lead to redundant encoding of global structure across scales and limits the effectiveness of compact token budgets. We propose RefineTok, a scale-wise continuous tokenizer that makes decoding itself progressive. RefineTok carries a visual state across scales and uses each latent prefix to refine the previous state into the next scale, turning scale-wise latents into incremental refinement signals rather than independent reconstruction codes. This design yields a compact and structured latent interface for both reconstruction and downstream generation. Together with prefix-level training, a coarse-centric scale trajectory, and a semantic anchor, RefineTok achieves strong reconstruction fidelity among scale-wise tokenizers and competitive class-conditional generation on ImageNet-1K under compact latent budgets. Meanwhile, it preserves a progressive scale-wise interface that single-scale tokenizers do not provide.
RegimeVGGT: Layer-Wise Spatially Preserving Redundancy Removal for Visual Geometry Grounded Transformer
Shuo Lyu ⋅ Jinhao You ⋅ Zhuohang Lyu ⋅ Tanxuan Li ⋅ Zibo Zhao ⋅ Jiaxiang Hu ⋅ Kai Tang ⋅ Yichen Guo
Visual Geometry Grounded Transformer (VGGT) recovers dense 3D scene structure from multi-view images in one forward pass, but quadratic cross-frame attention limits its scalability. Existing training-free accelerators reduce computation uniformly along one axis, missing layer heterogeneity. Our spectral, probing, and causal analyses reveal three regimes: shallow layers lack cross-view structure, middle layers drive cross-view alignment, and deep layers are redundant for dense geometry yet their cross-frame attention remains essential for pose. RegimeVGGT applies layer-wise U-shaped compression along two axes: Saliency-Guided Banded Merging protects geometry- and edge-salient tokens, while Selectively Protected K/V Downsampling preserves cross-frame spatial coverage and the pose-critical path through a phase-shifted spatial grid, a reference-frame anchor, and uncompressed camera/register tokens. Training-free, RegimeVGGT achieves a $6.7\times$ speedup over VGGT* at matched reconstruction quality. Code: \url{https://anonymous.4open.science/status/RegimeVGGT-9477}
Reinforcement Learning for Diffusion LLMs with Entropy-Guided Step Selection and Stepwise Advantages
Vishnu Teja Kunde ⋅ Fatemeh Doudi ⋅ Mahdi Farahbakhsh ⋅ Dileep Kalathil ⋅ Krishna Narayanan ⋅ JF Chamberland
Reinforcement learning (RL) has been effective for post-training autoregressive (AR) language models, but extending these methods to diffusion language models (DLMs) is challenging due to intractable sequence-level likelihoods. Existing approaches therefore rely on surrogate likelihoods or heuristic approximations, which can introduce bias and obscure the sequential structure of denoising. We formulate diffusion-based sequence generation as a finite-horizon Markov decision process over the denoising trajectory and derive the policy gradient that decomposes over denoising steps in terms of stepwise advantages, without requiring explicit evaluation of the sequence likelihood. Grounded in this theorem, we develop tractable approximations for large-scale training: (i) denoising steps are selected for policy updates via an entropy-guided approximation bound, and (ii) stepwise advantages are estimated using a one-step denoising completion naturally provided by the diffusion model, avoiding costly multi-step rollouts or auxiliary value networks. Experiments demonstrate state-of-the-art results on nearly all benchmarks spanning coding, logical reasoning, and mathematical reasoning, outperforming existing RL post-training approaches for DLMs.
Reinforcing Multimodal Reasoning Against Visual Degradation
Rui Liu ⋅ Dian Yu ⋅ Haolin Liu ⋅ Yucheng Shi ⋅ Tong Zheng ⋅ Runpeng(Leo) Dai ⋅ Haitao Mi ⋅ Pratap Tokekar
Reinforcement Learning has significantly advanced the reasoning capabilities of Multimodal Large Language Models (MLLMs), yet the resulting policies remain brittle against real-world visual degradations such as blur, compression artifacts, and low-resolution scans. Prior robustness techniques from vision and deep RL rely on static data augmentation or value-based regularization, neither of which transfers cleanly to critic-free RL fine-tuning of autoregressive MLLMs. Reinforcing reasoning against such corruptions is non-trivial: naively injecting degraded views during rollout induces reward poisoning, where perceptual occlusions trigger hallucinated trajectories and destabilize optimization. We propose ROMA, an RL fine-tuning framework that modifies the optimization dynamics to reinforce reasoning against visual degradation while preserving clean-input performance. A dual-forward-pass strategy uses teacher forcing to evaluate corrupted views against clean-image trajectories, avoiding new rollouts on degraded inputs. For distributional consistency, we apply a token-level surrogate KL penalty against the worst-case augmentation; to prevent policy collapse under regularization, an auxiliary policy gradient loss anchored to clean-image advantages preserves a reliable reward signal; and to avoid systematically incorrect invariance, correctness-conditioned regularization restricts enforcement to successful trajectories. On Qwen3-VL 4B/8B across seven multimodal reasoning benchmarks, our method improves robustness by +2.4% on seen and +2.3% on unseen corruptions over GRPO while matching clean accuracy.
Reject, Resample, Repeat: Understanding Parallel Reasoning in Language Model Inference
Noah Golowich ⋅ Fan Chen ⋅ Dhruv Rohatgi ⋅ Raghav Singhal ⋅ Carles Domingo i Enrich ⋅ Dylan J Foster ⋅ Akshay Krishnamurthy
Inference-time methods that generate, aggregate, and prune multiple parallel reasoning traces have emerged as a powerful paradigm for steering large language models, yet we lack a principled understanding of their accuracy--cost tradeoffs. We develop such an understanding for multi-particle methods, which maintain multiple partial chains of thought and use a process reward model (PRM) to adaptively score, prune, and replicate them. We focus on Sequential Monte Carlo (SMC), the simplest and most canonical such method. Despite SMC's long history in statistics and recent adoption for steering language and diffusion models, non-asymptotic guarantees have remained elusive. We provide (1) a simple, user-friendly analysis identifying two natural criteria which suffice for non-asymptotic convergence of SMC; (2) a simple modification of SMC achieving stronger, horizon-free guarantees when the PRM is near-perfect; and (3) a fundamental limit faced by all myopic multi-particle methods in the presence of PRM approximation errors. Empirically, we find that our criteria effectively predict the sampling error of SMC though not necessarily its final accuracy, paving the way for future work incorporating theoretical perspectives beyond sampling.
Representation Fréchet Loss for Visual Generation
Jiawei Yang ⋅ Zhengyang Geng ⋅ Xuan Ju ⋅ Yonglong Tian ⋅ Yue Wang
We show that Fréchet Distance (FD), long considered impractical as a training objective, can in fact be effectively optimized in the representation space. Our idea is simple: decouple the population size for FD estimation (e.g., 50k) from the batch size for gradient computation (e.g., 1024). We term this approach FD-Loss. Optimizing FD-Loss reveals several surprising findings. First, post-training a base generator with FD-Loss in different representation spaces consistently improves visual quality. Under the Inception feature space, a one-step generator achieves 0.72 FID on ImageNet $256\times256$. Second, the same FD-Loss repurposes multi-step generators into strong one-step generators without teacher distillation, adversarial training or per-sample targets. Third, FID can misrank visual quality: modern representations can yield better samples despite worse Inception FID. This motivates FDr$^{k}$, a multi-representation metric. We hope this work will encourage further exploration of distributional distances in diverse representation spaces as both training objectives and evaluation metrics for generative models. Code and checkpoints will be open-sourced.
Low-Rank Adaptation (LoRA) is often highly sensitive to learning-rate (LR) choices. Recent empirical studies suggest that, once LRs are carefully tuned, vanilla LoRA can remain competitive with many proposed LoRA variants. This shifts the central practical question from designing ever more variants to reducing the cost and brittleness of LR selection. LoRA+ addresses this issue with asymmetric LRs, using a larger LR for the up-projection matrix $B$ than for the down-projection matrix $A$. However, the ratio $\eta_B / \eta_A$ itself becomes an additional hyperparameter: large ratios can improve adaptation, but under the standard LoRA initialization they can also cause unstable training and ratio-dependent performance collapse. We identify the source of this brittleness through a signal--noise decomposition of LoRA dynamics. Under standard \initA, the update contains an initialization-induced noise term whose magnitude can be affected by the $B$-learning rate $\eta_B$, the initialization scale $\beta$, and the adapter rank $r$. In practical LLM fine-tuning, this non-vanishing noise can limit the performance gains expected from LoRA+-style asymmetric learning rates. To suppress this effect, we propose \initAA, a simple initialization that scales the variance of $A$ as $\sigma_A^2 \propto n^{-2}$ while keeping $B_0=0$. This reduces the normalized initialization-noise contribution by an additional factor of $1/n$, stabilizing asymmetric LoRA training while preserving zero initial adapter output. Empirically, \initAA substantially widens the stable LR region across initialization scales, adapter ranks, and LoRA update multipliers. Across tasks and models, \initAA reduces best-ratio drift, prevents the high-ratio collapse observed with standard \initA, and makes the width-based guideline $\eta_B \approx n \eta_A$ a useful starting point for finite pretrained models.
Rethinking On-Policy Self-Distillation for Thinking Models
Simran Kaur ⋅ Narutatsu Ri ⋅ Yinghui He ⋅ Liam Fowl ⋅ Sanjeev Arora
Self-distillation has emerged as a promising recipe for self-improvement in language models \citep{zhao2026selfdistilledreasoneronpolicyselfdistillation,shenfeld2026self,hubotter2026reinforcement}. In this setting, a model can be used as its \textit{own} teacher when augmented with privileged information (e.g. a solution to a math problem). This seems like an especially appealing approach for thinking models that can leverage test-time reasoning to integrate learnings from privileged information. However, we show that privileged self-distillation degrades the long-budget test-time compute behavior of thinking models: across five Qwen3 and OLMo thinking models evaluated on AIME24, AIME25, and HMMT25, privileged-context distillation causes a relative drop of up to 17\% in avg@16 accuracy. The degradation scales with the amount of privileged context withheld from the student and is most pronounced at long rollout budgets, where thinking models otherwise obtain their largest gains. This failure mode is not specific to self-distillation: on-policy distillation (OPD) improves thinking models, but privileged on-policy distillation reverses these gains. Our diagnostics suggest that this failure mode is linked to how privileged teacher context reshapes learning at high-entropy forking positions \citep{bigelow2024forking, zhang2026embarrassingly}, i.e., rollout positions where multiple continuations remain plausible and may lead to different reasoning paths. Privileged context lowers fork rates in thinking-model rollouts but not in instruction model rollouts. This leads to an interesting dichotomy wherein privileged context can help instruction-tuned models but hurts more performant thinking models that depend heavily on exploration and rollout quality. This effect is especially visible when the student begins a self-correction branch, where privileged OPD penalizes sampled reconsideration tokens that vanilla OPD supports. Thinking models trained with a privileged teacher produce fewer verification, backtracking, and hedging markers, even after length normalization. These findings indicate that applying self-distillation methods to strong thinking models requires further consideration of token-level signal---especially around tokens related to correction and crucial reasoning steps.
Rethinking Structured Generation: Can Graph-Based Reasoning Resolve Ambiguity?
Ratun Rahman ⋅ Atit Pokharel
Structured generation is typically formulated as a deterministic mapping from input to a single structured output. This assumption is fundamentally misaligned with natural language, which often admits multiple structurally distinct yet semantically valid interpretations. As a result, existing methods rely on single-reference supervision that collapses ambiguity into one prediction, leading to unstable and inconsistent outputs under underspecified inputs. We reformulate structured generation as an \textit{ambiguity-aware inference problem}, where the objective is to reason over a set of plausible structured outputs rather than predict a single solution. We show that standard training inherently suppresses valid alternatives, and instead adopt a multi-valid learning framework that preserves ambiguity during optimization. To operationalize this formulation, we construct a candidate space of structured outputs, represent each candidate as a graph capturing entities and their relationships, and perform selection via graph-based reasoning over semantic alignment and relational consistency. This enables principled comparison across competing interpretations beyond token-level likelihoods. Experiments on structured generation benchmarks demonstrate consistent improvements in accuracy, stability, and robustness under varying levels of ambiguity. These results highlight the importance of modeling ambiguity explicitly and suggest a shift from single-output prediction to set-level reasoning in structured generation.
Revealing the Gap in Human and VLM Scene Perception through Counterfactual Semantic Saliency
Ziqi Wen ⋅ Parsa Madinei ⋅ Miguel Eckstein
Evaluating whether large vision-language models (VLMs) align with human perception for high-level semantic scene comprehension remains a challenge. Traditional white-box interpretability methods are inapplicable to closed-source architectures and passive metrics fail to isolate causal features. We introduce Counterfactual Semantic Saliency (CSS). This black-box, model-agnostic framework quantifies the importance of objects by measuring the semantic shift induced by their causal ablation from a scene. To evaluate AI-human semantic alignment, we tested prominent VLMs against a human psychophysics baseline comprising 16,289 valid responses across 307 complex natural scenes and 1,306 high-fidelity counterfactual variants. Our analysis reveals a pervasive scene comprehension gap: models exhibit an overreliance (relative to humans) on large objects (size bias), objects at the center of the image (center bias), and high saliency objects. In contrast, models rely less on people in the scenes than our human participants to describe the images. A model’s size bias is a primary driver explaining variations in model-human semantic divergence.
Reviving Stale Updates: Data-Free Knowledge Distillation for Asynchronous Federated Learning
Baris Askin ⋅ Holger Roth ⋅ Zhenyu Sun ⋅ Carlee Joe-Wong ⋅ Gauri Joshi ⋅ Ziyue Xu
Federated learning (FL) enables collaborative model training across distributed clients without sharing raw data, yet its scalability is limited by synchronization overhead. Asynchronous federated learning (AFL) alleviates this issue by allowing clients to communicate independently, thereby improving wall-clock efficiency in large-scale, hardware-heterogeneous environments. However, asynchrony introduces updates computed on outdated global models (staleness) that can destabilize optimization and hinder convergence. We propose FedRevive, an AFL framework that revives stale updates through data-free knowledge distillation (DFKD). FedRevive integrates parameter-space aggregation with a server-side DFKD process that transfers knowledge from stale client updates to the current global model without access to data. A meta-learned generator synthesizes pseudo-samples for multi-teacher distillation. A hybrid aggregation scheme combining raw with DFKD updates effectively mitigates staleness while retaining AFL scalability. Experiments on vision and text benchmarks show that FedRevive achieves faster training by up to 29.7\% and higher final accuracy by up to 11.4\% percentage points than baselines.
RL-Inf: Tracking Non-local Training Data Influence for Online Reinforcement Learning
Shixuan Liu ⋅ Cheng Tang ⋅ Yuzheng Hu ⋅ Fan Wu ⋅ Han Zhao ⋅ Jiaqi Ma
Online reinforcement learning (RL) has achieved significant success in decision-making tasks, but modern online RL remains highly sensitive to the quality of training experience. Understanding the role of training data in online RL is challenging because the training distribution evolves together with the policy, causing the influence of the training data to propagate across future optimization and future data collection. Existing data-attribution methods for online RL primarily focus on local influence within a single training round, overlooking the non-local data influence across multiple training rounds. In this work, we formalize data attribution in online RL through a trajectory-level leave-one-out quantity, RL-LOO, which measures how one training sample influences a downstream target after subsequent online updates have taken place. We then derive RL-Inf, a first-order estimator that propagates data influence through both optimization effects and policy-induced sampling effects, and provide theoretical guarantees on its approximation accuracy under smoothness assumptions. Our analysis further disentangles these two effects and shows both theoretically and empirically that the full RL-Inf estimator can often be well approximated using the optimization effect alone. Building on this observation, we develop RINSE, a practical data filtering method for online RL. Experiments on standard control benchmarks and an RLHF-style toxicity-mitigation setting show that RINSE improves training efficiency and final performance over standard PPO and local attribution baselines. These results suggest that RL-Inf provides a practical and principled framework for understanding and improving online RL.
Robust and Efficient Finetuning of Vision Foundation Models via Implicit Ensembling
Masih Aminbeidokhti ⋅ Heitor Medeiros ⋅ Eric Granger ⋅ Marco Pedersoli
Robust finetuning of foundation models seeks to improve out-of-distribution (OOD) generalization during in-distribution (ID) adaptation. We revisit Mixout, a stochastic regularizer that intermittently replaces finetuned parameters with a reference anchor, and study its effectiveness for robust finetuning of vision foundation models. We reinterpret Mixout as a single-run, weight-sharing implicit ensemble and analyze its expected OOD error through a bias–variance–covariance–locality (BVCL) lens. This perspective reveals three key factors that govern the ID–OOD trade-off: the choice of masking anchor, the mask resampling frequency, and mask sparsity. Guided by this analysis, we propose GMixout, which generalizes Mixout in three ways. First, it explicitly controls the masking period through a resampling-frequency hyperparameter. Second, it replaces the fixed pretrained anchor with an exponential moving average snapshot that adapts throughout training. Third, it uses sparse kernels to update only a small subset of parameters at each iteration, introducing no inference-time overhead and enabling large-model finetuning on consumer-grade GPUs. Experiments across five vision benchmarks show that GMixout consistently outperforms Mixout, Model Soups, and strong parameter-efficient finetuning baselines under both covariate shift and class imbalance.
We show that replacing the standard MSE denoising loss in diffusion models with a nonlinear transformation induced by an f-divergence yields a simple robust training surrogate that empirically improves performance under data contamination, with small additional computational overhead. The theoretical foundation rests on a local divergence construction: under the Gaussian reverse-kernel structure of DDPM, each per-step likelihood ratio follows a lognormal distribution parameterized by a scalar mismatch, so the conditional f-divergence at each step reduces to a one-dimensional function of the denoising error. Summing these local divergences yields a training objective that unifies diffusion training as divergence-induced weighted denoising, where the derivative of the induced divergence acts as a residual-space influence weight that controls the contribution of each sample. Bounded-influence divergences (Hellinger, negative exponential) suppress large-error samples, with Hellinger yielding an explicit exponential weight, connecting the framework to robust M-estimation. Empirically, on CIFAR-10 under 30% contamination, NED reduces FID from 93.0 (KL) to 77.5, while also outperforming standard robust losses such as Huber and clipped MSE.
Diffusion models represent a powerful class of generative models known for their solid theoretical foundations and remarkable performance across diverse tasks and domains. While diffusion models have been extensively utilized for generating entire graphs or small-scale graphs, no diffusion-based approaches have been developed to synthesize graph structures within an existing graph, including synthetic nodes and their associated edges. In this study, we introduce the Robust Graph Diffusion Model (RGDM), designed to generate labeled synthetic graph structures consisting of nodes and edges that integrate seamlessly into a given graph. The RGDM consists of a Robust Graph Autoencoder (RGAE) and a Latent Diffusion Model (LDM). Leveraging an edge selection mechanism and an innovative low-rank regularization on the latent feature, the RGDM produces clean and high-quality synthetic graph structures, even when trained on graphs subject to adversarial attacks. Comprehensive experimental evaluations reveal that Graph Neural Networks (GNNs) trained on the augmented graph, which is formed by merging the original attacked graph with the synthetic graph structures, exhibit significantly improved robustness against various graph adversarial attacks in the context of semi-supervised node classification. The code of the RGDM is available at \url{https://anonymous.4open.science/r/RGDM}.
Robust Nash Alignment under Preference Uncertainty
Shihab Ahmed ⋅ Debamita Ghosh ⋅ David Tang ⋅ Yudan Wang ⋅ Alvaro Velasquez ⋅ Yue Wang
Preference-based alignment methods typically optimize against a single preference model, and can therefore be brittle when pairwise preferences are uncertain: noisy, heterogeneous, or shift after deployment. We study alignment under uncertain preferences through the lens of general-preference games. Specifically, we formulate Robust Nash Learning from Human Feedback, where the learner seeks a policy with a large worst-case win rate against both an adversarial competitor and any preference kernel lying in an ambiguity set around a nominal preference. When the ambiguity set captures the uncertainty in preferences, the resulting hard-constrained robust objective directly yields a certified lower bound on worst-case performance. However, we note this problem is computationally challenging to optimize, and to address this, we introduce a four-player primal-dual proxy game involving the leader policy, follower policy, adversarial kernel, and dual variable, and develop a single-loop optimistic mirror descent-ascent algorithm for this game. We show that the proxy always lower-bounds the truncated hard-constrained objective, quantify the proxy-to-hard gap, and characterize an exactness condition under which the proxy recovers the robust objective. We then prove an $O(1/\sqrt{T})$ convergence rate for the proxy-game duality gap, which implies a near-optimal robust policy for the original robust objective. Experiments on controlled tabular games and LLM alignment with uncertain preference further validate the convergence theory and show improved performance over nominal baselines.
ROCKET: Residual-Oriented Multi-Layer Alignment for Spatially-Aware Vision-Language-Action Models
Guoheng Sun ⋅ Tingting Du ⋅ Kaixi Feng ⋅ Chenxiang Luo ⋅ Xingguo Ding ⋅ Zheyu Shen ⋅ Ziyao Wang ⋅ Yexiao He ⋅ Ang Li
Vision-Language-Action (VLA) models enable instruction-following robotic manipulation, but they are typically pretrained on 2D data and lack 3D spatial understanding. An effective approach is representation alignment, where a strong vision foundation model is used to guide a 2D VLA model. However, existing methods usually apply supervision at only a single layer, failing to fully exploit the rich information distributed across depth; meanwhile, naïve multi-layer alignment can cause gradient interference. We introduce ROCKET, a residual-oriented multi-layer representation alignment framework that formulates multi-layer alignment as aligning one residual stream to another. Concretely, ROCKET employs a shared projector to align multiple layers of the VLA backbone with multiple layers of a powerful 3D vision foundation model via a layer-invariant mapping, which reduces gradient conflicts. We provide both theoretical justification and empirical analyses showing that a shared projector is sufficient and outperforms prior designs, and further propose a Matryoshka-style sparse activation scheme for the shared projector to balance multiple alignment losses. Our experiments show that, combined with a training-free layer selection strategy, ROCKET requires \textit{only about 4% of the compute budget while achieving 98.5% state-of-the-art success rate on LIBERO}. We further demonstrate the superior performance of ROCKET across LIBERO-Plus, RoboTwin, multiple VLA models, and a real-world industrial warehouse picking task. The code and model weights will be released upon acceptance of the paper.
RustMizan: A Compilable, Contamination-Aware Benchmarking Framework for Rust Vulnerabilities
Tarek Elsayed ⋅ Shiping Yang ⋅ Eunsong Koh ⋅ Sanika Goyal ⋅ Vincent Huang ⋅ Paul Ngo ⋅ Nathan Young ⋅ Mohammad Omidvar Tehrani ⋅ Alvyn Kang ⋅ Arnell Kang ⋅ Zeyu Chen ⋅ Angelica Moreira ⋅ Xuan Feng ⋅ Angel Chang ⋅ Nick Sumner ⋅ Steve Ko
LLM agents are increasingly applied to vulnerability analysis, but existing benchmarks have not kept pace. They typically rely on small non-compilable snippets, focus on binary classification (vulnerable or not), and do not account for the risk that publicly-released datasets are part of model training corpora. We introduce RustMizan, a benchmarking framework for Rust vulnerability analysis that addresses these gaps. RustMizan contains compilable code variants at the crate, file, and function levels, with annotations for binary vulnerability detection, CWE classification, and function- and line-level localization. A paired mutation framework produces semantics-preserving code mutants for contamination testing and robustness probing. Across four frontier models in an agentic setup with command-line access, binary classification sits in the 56--65\% range, but line localization F1 stays near 20\%, and adversarial cues drop line F1 by about 27\%.
Uncertainty quantification (UQ) for random partial differential equations (PDEs) is ubiquitous in computational science and engineering. However, classical spectral solvers for this class of problems face the curse of dimensionality, and existing neural solvers often ignore the stochastic structure that makes moments and calibration tractable. We introduce a stochastic separable physics-informed neural network, dubbed S$^{2}$-PINN, that represents the solution $u(t,\mathbf{x},\mathbf{Z})$ of a random PDE with a learnable Gaussian spatial dictionary, Fourier temporal features, and a generalized polynomial chaos (gPC) stochastic bases, coupled by a low-rank Canonical Polyadic (CP) tensor decomposition core. The method is trained with a hybrid strong-form and gPC-projected residual loss. Our theoretical analysis establishes that the separable class is dense in $L^2$ under mild conditions, and the projected residual corresponds exactly to a stochastic Galerkin constraint. Furthermore, we show that mini-batch projection coefficients are logarithmically dependent on the number of gPC modes, and that orthogonality penalty controls the conditioning of the learned spatial dictionary. Using four manufactured random PDE benchmarks, we show that S$^{2}$-PINN outperforms six baselines in terms of mean and variance accuracy, as well as calibration, while using significantly fewer parameters. Further evaluations on non-manufactured Poisson and Darcy problems, a diffusion scaling study of higher random dimensions, and two stochastic inverse problems reveal the generalization capabilities of the proposed structure. Together, these results support stochastic separability as an effective design principle for physics-informed neural UQ. The code for the experiments can be found in \href{https://anonymous.4open.science/status/neurips2026-0424}{https://anonymous.4open.science/status/neurips2026-0424}.
SAFTAC: Simulation-Augmented Fine-Tuning of Open-Source LLMs for Analog Circuit Design
Junsheng Huang ⋅ Yifan Sun ⋅ Zhuoer Zhang ⋅ Ning Wei ⋅ Yening Liu ⋅ Michael Molter ⋅ Pavan Kumar Hanumolu ⋅ Elyse Rosenbaum ⋅ Bin Hu ⋅ Huan Zhang
Circuit design for analog integrated circuits (ICs) is challenging because circuit topology, device sizing, and circuit performance are tightly coupled. Existing large language model (LLM)-based methods either rely on inference-time correction around frozen models or train on limited circuit types without directly using simulation outcomes as training signals. A key bottleneck is that existing datasets do not provide sufficient task information for training LLMs on end-to-end specification-conditioned design. To fill this gap, we first construct a large-scale simulation-grounded dataset with 8,626 design tasks across 10 different types of analog circuits, where each task includes a textual description, labeled I/O ports, loading condition, target specifications, a testbench, and a reference netlist. Using this dataset, we present SAFTAC, a simulation-augmented fine-tuning framework that trains LLMs to generate and revise analog circuit design. SAFTAC combines three-stage supervised fine-tuning, which progressively builds the capabilities required for analog circuit design and feedback-guided correction, with simulation feedback-augmented reinforcement fine-tuning, which further optimizes models using simulation-grounded rewards. We evaluate SAFTAC under single-pass generation and two-pass generation with simulation feedback, showing improvements over the strongest closed-source LLM by 15.9\% and 7.8\%, respectively.
SAGE: Mitigating Long-Horizon Reasoning Biases via Topological Guidance
Xinyue Zeng ⋅ Jiawei zhang ⋅ Yujun Yan ⋅ Dawei Zhou
Long-horizon reasoning remains a central challenge for large language models (LLMs) under sparse-reward regimes. We argue that this brittleness arises from two biases induced by complex reasoning spaces: an exploration bias, where models are drawn toward locally plausible but structurally unstable branches, and a compounding bias, where small local deviations accumulate across depth and suppress rare rewards. We introduce Symbolic Closure Analysis (SCA) as a theoretical lens characterizing how branching structures and sparse rewards induce these biases in long-horizon reasoning with local admissibility, and as a design principle for structural priors in less formal reasoning tasks. Motivated by this analysis, we propose \model{} (\textbf{S}tructural \textbf{A}dmissibility-\textbf{G}uided \textbf{E}xploration), a unified framework that injects structural guidance to alleviate exploration bias and compounding bias in long-horizon reasoning. \model{} combines two complementary structural dimensions: algebraic sparsification, which projects locally admissible candidates onto operator-indexed algebraic subspaces to suppress spurious branching and mitigate exploration bias, and hyperbolic structural guidance, which embeds reasoning states into a negatively curved space to provide dense depth-wise signals and mitigate compounding bias. Across 12 benchmarks and 7 model families, \model{} outperforms competitive baselines. In particular, \model{} achieves up to an 8-fold improvement on the Andrews-Curtis problem, an open real-world long-horizon task. Code is available at: \url{https://anonymous.4open.science/r/SAGE-Long-Horizon-Reasoning-AD70}.
Sample complexity of stochastic optimization with integer variables
Hongyu Cheng ⋅ Yinghao Zheng ⋅ Marco Molinaro ⋅ Amitabh Basu
We establish sample complexity results for stochastic optimization over the integers, especially with a view to understand the complexity with respect to the corresponding continuous optimization problem. We show that integer optimization can sometimes require strictly more samples and sometimes strictly smaller number of samples, depending on the structure of the objective and constraints. 1. For Lipschitz objectives over subsets of the $\ell_\infty$ ball, the statistical complexity of general stochastic mixed-integer, nonlinear, nonconvex optimization is exactly the same as stochastic linear optimization with just bound constraints. 2. For Lipschitz objectives over subsets of the $\ell_2$ ball, we show that integer optimization can require strictly *smaller* sample size compared to the continuous setting in a certain regime. To get to this result, we also establish tight sample complexity results for nonconvex continuous stochastic optimization which, to the best of our knowledge, do not appear in prior work. 3. For strongly convex, smooth objectives, integer optimization has high statistical complexity compared to the continuous setting. In particular, we show that integer optimization requires $\Omega(1/\epsilon^2)$ samples to report an $\epsilon$-approximate solution, compared to the well-known $O(1/\epsilon)$ sample complexity from the continuous optimization literature.
Scalable Derivative Gaussian Processes via Exact Gradient Reduction
Hyunseok Seung ⋅ Matthias Katzfuss
Gradient observations can substantially improve Gaussian process (GP) surrogates, particularly in high-dimensional settings where function evaluations are expensive. However, exact inference with $n$ function values and $n$ full gradients in $d$ dimensions scales cubically in the joint state size, imposing an intractable $\mathcal{O}(n^3 d^3)$ computational bottleneck. We introduce TERA, a highly scalable derivative GP method based on target-specific exact gradient reduction. We prove that for stationary kernels, the gradient components orthogonal to the directions connecting the target and conditioning points are conditionally independent of the target function value; consequently, the exact conditional density is fully characterized by at most $m^2$ directional derivatives once a conditioning set of size $m$ is specified. By using these reduced, dimension-free conditionals as local factors in a Vecchia approximation, TERA effectively decouples $n$ and $d$ from the dense matrix inversion. This reduces the per-target evaluation cost to $\mathcal{O}(dm^2 + m^6)$ time and $\mathcal{O}(dm^2 + m^4)$ memory, leaving the underlying derivative GP model mathematically unchanged. Empirical evaluations demonstrate that TERA achieves state-of-the-art predictive accuracy while operating orders of magnitude faster than standard derivative GPs. Crucially, both computation time and peak GPU memory remain essentially flat with respect to $d$, enabling highly scalable inference in high-dimensional spaces.
SCULPT: Advancing Masked Discrete Diffusion for High-Resolution Image Synthesis.
Shufan Li ⋅ Greg Heinrich ⋅ Hanrong Ye ⋅ Yonggan Fu ⋅ Aditya Grover ⋅ Jan Kautz ⋅ Pavlo Molchanov
We propose SCULPT, a state-of-the Art masked discrete diffusion model (MDMs) for high resolution text-to-image synthesis. Compared with prior works on masked image generation, SCULPT addresses two key challenges. First, unlike continuously diffusion models which progressively refines image latent across the entire image, vanilla MDMs do not have self-correcting capability because discrete tokens cannot be changed once it's unmasked. Second, while scaling the vocabulary size of discrete image tokenizers can improve reconstruction quality, it also introduces optimization challenges for training generative models as per-token training signal becomes more spares. To address the first challenge, SCULPT incroprates a token-editing mechanism where the model can dynamically correct already-unmasked output tokens during inference. To address the second challenge. we proposed a Goruped Corss Entrophy (GCE) objective that assigns positive learning signal to adjacent tokens of the ground truth in the embedding space. To improve the training efficiency, we further implemented a custom fused operator that greatly reduce the VRAM requirements during training in large-vocabulary setting. Experiment results show that these innovations significant improves the training efficiency and image fidelity of masked discrete image generators.
SEISMOS: A Statistical Signal Detection Framework for Semantic Chunking
Ishtiak M Saad ⋅ Mominul Islam ⋅ Shahriyar Z Ridoy ⋅ Md Manjurul Ahsan ⋅ Azmine Toushik Wasi
Chunking is a hidden bottleneck in dense retrieval and retrieval-augmented generation: it determines the units that can be indexed, retrieved, and ultimately used as evidence. Yet most systems still segment documents using fixed token windows or globally thresholded semantic similarity drops, treating chunking as an engineering heuristic rather than a statistical decision. We propose SEISMOS, a statistical signal detection framework for semantic chunking. SEISMOS models consecutive sentence-embedding cosine similarities as a document-level signal and derives boundary decisions from the null hypothesis of no semantic transition. Across four development BEIR corpora, we establish three corpus-invariant properties: bimodal document structure, rapid survival decay of shallow local minima, and positive lag-1 autocorrelation. These properties show that semantic boundaries should be detected by variance-normalized deviations, not by document means or global similarity thresholds. Accounting for autocorrelation leads to a normalized discrete Laplacian detector that identifies significant semantic valleys through a single interpretable decision rule. Evaluated on five BEIR benchmarks, SEISMOS consistently improves over fixed-length, recursive, and production semantic chunking baselines under one fixed operating configuration. Without corpus-specific retuning, the same detector transfers to a held-out TREC-COVID corpus. Our results suggest that the boundaries needed for effective retrieval are already encoded in embedding-similarity signals, and that principled, efficient, LLM-free chunking can be obtained by detecting them statistically.
Understanding the loss-landscape geometry near a minimum is key to explaining the implicit bias of gradient-based methods in non-convex optimization problems such as deep neural network training and deep matrix factorization. A central quantity to characterize this geometry is the maximum eigenvalue of the Hessian of the loss. Currently, its precise role has been obfuscated because no exact expressions for this sharpness measure were known in general settings. In this paper, we present the first exact expression for the maximum eigenvalue of the Hessian of the squared-error loss at *any* minimizer in deep matrix factorization/deep linear neural network training problems, resolving an open question posed by Mulayoff & Michaeli [2020]. This expression reveals a fundamental property of the loss landscape in deep matrix factorization: *Having a constant product of the spectral norms of the left and right intermediate factors across layers is a sufficient condition for flatness*. Most notably, in both depth-$2$ matrix and deep overparameterized scalar factorization, we show that this condition is both necessary and sufficient for flatness, which implies that *flat minima are spectral-norm balanced and not necessarily Frobenius-norm balanced*. To complement our theory, we provide an empirical verification of an escape phenomenon during gradient-based training near a minimizer of a deep matrix factorization problem which relies on our exact expression.
SHRED: Retain-Set-Free Unlearning via Self-Distillation with Logit Demotion
Zizhao Hu ⋅ Ameya Godbole ⋅ Johnny Wei ⋅ Mohammad Rostami ⋅ Jesse Thomason ⋅ Robin Jia
Machine unlearning for large language models (LLMs) aims to selectively remove memorized content such as private data, copyrighted text, or hazardous knowledge, without costly full retraining. Most existing methods require a retain set of curated examples to prevent catastrophic degradation of general model utility, creating an extra data dependency that complicates deployment. We propose SHRED (Self-distillation via High-surprisal-only Retain-set-free Entropy Demotion), a retain-set-free unlearning method built on a key insight: not all tokens within a forget set instance carry memorized information equally. High-information tokens concentrate the model's memorized knowledge, while low-information tokens reflect general language competence. SHRED operates in two stages. (1) Selection: We perform a forward pass on a forget set instance, collect per-token autoregressive probabilities, and select the bottom-$P$ (lowest probability, highest Shannon information) as forget positions; the remaining positions are retained as benign anchors. (2) Training: We construct modified KL targets that demote the memorized token's logit at forget positions while preserving the original distribution at benign positions. The model is then trained via a single top-$K$ KL self-distillation objective that simultaneously drives forgetting and utility preservation. We evaluate SHRED across four standard unlearning benchmarks and demonstrate that it establishes a new Pareto-optimal trade-off between forget efficacy and model utility, outperforming retain-set-dependent methods. Our analysis shows that SHRED is robust against relearning attacks and membership-inference attacks, and it maintains stable utility even after many sequential unlearning runs.
SiliciclasticReservoirs: A Million-Reservoir Dataset and Flow-Matching Foundation Model for 3D Siliciclastic Reservoir Generation
Ilgar Baghishov ⋅ Elnara Rustamzade ⋅ Graeme Henkelman ⋅ John Foster ⋅ Michael J Pyrcz
3D subsurface geological models underpin hydrocarbon exploration, geothermal energy, underground gas storage, and geological carbon storage. A decade of deep generative facies modeling has yet to yield a model that generalizes across geological settings, scales to realistic reservoir extents, and conditions naturally on well data, bottlenecked by the absence of a large-scale, multi-environment, property-rich dataset. We release SiliciclasticReservoirs, the largest and most diverse public 3D dataset of siliciclastic (sandstone-bearing) subsurface reservoirs to date: $10^6$ voxelized reservoirs at $64{\times}64{\times}32$ resolution spanning eight depositional settings (deep-water turbidite lobes, deltas, and six fluvial channel architectures from the Alluvsim family), each annotated with binary and six-class facies labels, per-voxel porosity and permeability, and a natural-language caption describing the reservoir's geological setting and petrophysical attributes. To our knowledge, it is the first siliciclastic dataset to pair 3D geological models with petrophysical properties at this scale, the first to span this breadth of settings in a unified release, and the first to ship text captions, supporting future multimodal and language-conditioned training for text-to-reservoir generation and retrieval. Building on SiliciclasticReservoirs, we train ResFlow, a flow-matching foundation model that, from a single set of weights, generates any environment under continuous parametric control, conditions on arbitrary well configurations via classifier-free guidance, and assembles reservoirs at arbitrary spatial extent through overlapping-tile MultiDiffusion, with no retraining. SiliciclasticReservoirs (CC-BY 4.0), ResFlow (MIT), and the data-generation engine ResMill (MIT) are publicly released.
SiliconBench: Speed, Memory, and Fidelity for LLM Inference on Apple Silicon
Ranran H Zhang ⋅ Aysa Fan ⋅ David M Correia ⋅ Alex Cheema ⋅ Rui Zhang
Apple Silicon is a major consumer platform for local LLM inference, with at least ten serving engines competing for users. Speed-only leaderboards on this platform mislead: the fastest stack often claims memory the rest of the machine needs, or silently produces wrong output. We introduce \ourbench, a benchmark that evaluates ten Apple Silicon inference stacks through three lenses: throughput and latency at concurrency 1, 8, and 16; peak memory under contention with the operating system; and fidelity as weighted F1 on a classification task against an NVIDIA reference run on identical weights. The benchmark covers three model releases and two workload types (short chat and multi-turn agent prompts averaging ${\sim}$4K input tokens). A maintainer agent re-runs the full benchmark weekly; in its first five runs it caught a single upstream library bump that broke three of ten stacks through three distinct failure modes and diagnosed a chat-template error that corrupted one stack's fidelity scores. No audited stack performs well across all three lenses, and the stack rankings shift when memory and fidelity are read alongside speed. The candidate set, stacks without disqualifying gaps under any lens, reduces from ten to four. A separate multi-node comparison shows that tensor parallelism over RDMA scales decode $1.3\times$ on two nodes, while pipeline parallelism over TCP regresses $16$--$19\%$. In every case the gaps are in the engines, not the hardware: Apple Silicon provides sufficient memory, compute, and interconnect; the engines have not yet exploited it. We release the harness, per-run results, and weekly journals.
SimplexUQ: An Evaluation Framework and Benchmark for Conformal Uncertainty on Simplex-Valued Predictions
Liang You ⋅ Hengyu Shi ⋅ Dongwen Ou
Conformal prediction can be marginally valid on simplex-valued outputs while still allocating coverage unevenly across prediction space, over-protecting easy regions and leaving hard regions under-covered. This matters because many modern predictors output compositions, including class-probability vectors, topic mixtures, spectral abundances, cell-type fractions, age-label distributions, and emotion mixtures. We argue that allocation quality must be evaluated in its own right, and introduce $\textbf{SimplexUQ}$ to make this possible. SimplexUQ contributes a diagnostic protocol for measuring coverage-allocation failures, $\textbf{SimplexTasks-12}$ (a benchmark with six controlled synthetic regimes and six fixed-predictor real tasks), and a systematic comparison of global, group-wise, normalization-based, exact, and leave-one-out conformal wrappers. Across the benchmark, no wrapper dominates under all stratifications and tasks, though group-wise calibration is competitive across many settings. Global calibration can satisfy nominal marginal coverage while producing severe worst-stratum failures; for example, on CIFAR-10, global calibration attains 0.900 marginal coverage but leaves the worst entropy stratum at 0.542 coverage, whereas group-wise calibration reduces the max disparity from 0.358 to 0.022. Group-wise calibration is strongest when heterogeneity is coarse and aligned with a partition, whereas normalization and leave-one-out-style methods are more competitive under smooth heterogeneity. On several tasks, even the best wrapper fails to recover acceptable worst-stratum coverage. The benchmark standardizes tasks, stratifications, metrics, compute reporting, and artifact packaging, with code and rebuild instructions for restricted assets. Marginal validity alone is therefore insufficient for simplex-valued uncertainty quantification: wrapper choice should be matched to the heterogeneity structure of the task, with allocation, efficiency, and compute considered jointly.
SlackBench: Benchmarking Agents on Collaborative Projects Grounded in Real Code Repositories
Mingxuan Li ⋅ Huanzhi Mao ⋅ Ruitao Zheng ⋅ Jarod Stanbury James ⋅ Yunze Li ⋅ Natanya Anderson ⋅ Joseph Gonzalez ⋅ Alex Dimakis
AI Agents are becoming digital coworkers that can browse the web, write code, run experiments, and assist humans over extended horizons. Yet existing benchmarks fall short of real knowledge work: many rely on synthetic data or isolated tasks, missing the complex, multi-party dynamics of collaborative projects, where critical information is scattered across conversations, code, and evolving decisions. Even simple workplace questions may require locating relevant channels and direct messages, recovering context from long discussions, inspecting repository state, reconciling stale or conflicting evidence, and synthesizing across sources. We introduce SlackBench, a benchmark for evaluating agents on realistic research and engineering workflows that require joint reasoning over workplace communication and evolving repository state. Grounded in privacy-preserving reenactments of real academic research projects, SlackBench provides reproducible environments with realistic multi-party dialogue, evolving decisions, and corresponding code changes grounded in Github repositories and Google Docs. It contains 140 queries spanning heterogeneous-source agentic search, abstention on unanswerable or false-premise questions, goal-directed summarization, and circumstance inference over long conversations. These tasks are not reducible to static corpus question answering: agents must determine which conversations matter, traverse threads, inspect repository state, and synthesize evidence across communication and code artifacts. Across 20 frontier models and agent harnesses, the best systems score under 60\%, highlighting substantial headroom for improvement. SlackBench thus provides an extensible framework for evaluating agents in collaborative work environments.
SlopCodeBench: Benchmarking How Coding Agents Degrade Over Long-Horizon Iterative Tasks
Gabriel Orlanski ⋅ Devjeet R Roy ⋅ Alexander Yun ⋅ Changho Shin ⋅ Alex Gu ⋅ Albert Ge ⋅ Dyah Adila ⋅ Nicholas Roberts ⋅ Frederic Sala ⋅ Aws Albarghouthi
Software development is iterative, yet agentic coding benchmarks hide design issues through their single-shot setup. Recent iterative benchmarks attempt to remedy this but heavily constrain an agent's design decision space, making it impossible to faithfully measure how their decisions shape future extensions. We introduce SlopCodeBench, a benchmark comprising 36 problems and 196 checkpoints in which agents repeatedly extend their own solutions. Unlike prior iterative benchmarks, our evolving specifications demand architectural decisions but leave internal structure to the agent. We measure two forms of degradation: structural erosion (concentrated complexity) and verbosity (redundant code). Evaluating 15 coding agents across open and closed models, we find that no agent fully solves any problem end-to-end, and the best agent passes 14.8% of checkpoints. Quality degrades across checkpoints, with structural erosion rising in 77% of trajectories and verbosity in 75.5%. Compared to 473 open-source Python repositories, agent code is 2.3x more verbose and 2.0x more eroded, and the human repositories degrade less often and by smaller margins across their git histories. Explicit quality guidance reduces initial verbosity and erosion by up to a third, without affecting degradation rates. SlopCodeBench identifies a failure mode that single-shot benchmarks cannot detect: agents that pass checkpoints while producing code that erodes and bloats with each extension.
SLVR: Structured Latent Visual Reasoning via Human-like Reasoning Flows
Albert Gao ⋅ Bing Xue ⋅ Andrea Zanette
Multimodal large language models (MLLMs) often answer visual reasoning questions by relying on linguistic priors rather than task-relevant visual evidence. Textual chain-of-thought reasoning can partially mitigate this issue by encouraging models to decompose visual questions into intermediate evidence-seeking steps, but generating these steps autoregressively increases inference cost. Latent reasoning avoids explicit rationale generation, but existing approaches provide limited control over what intermediate states encode, making it difficult to impose separate supervision for planning, grounding, and evidence selection. We propose Structured Latent Visual Reasoning (SLVR), a training framework that bridges explicit chain-of-thought and latent reasoning by organizing multimodal reasoning into typed latent stages for planning, grounding, evidence selection, and reasoning integration. SLVR first trains the model to rely on the image by masking answer-revealing text and contrasting the correct answer with visually plausible distractors. It then organizes reasoning into latent stages for planning, grounding, evidence selection, and integration, supervising each stage with the corresponding signal: plans, boxes, visual evidence, and final rationales. This gives latent reasoning an explicit functional structure while avoiding generated textual chains at inference time. Built on Qwen2.5-VL-7B, SLVR improves consistently across multimodal reasoning benchmarks, with absolute gains of +9.4 on MMVP and +14.2 on BLINK Relation, as well as improvements on V*, MathVista, and ChartQA. These results suggest that structured latent supervision can improve fine-grained visual reasoning without the decoding overhead of textual CoT. Code is available \href{https://anonymous.4open.science/r/SLVR-681F/README.md}{here}.
Functional data, i.e., random functions observed over a continuous domain, are increasingly available in areas such as biomedical research, health informatics, and epidemiology. However, effective statistical analysis for functional data is often hindered by challenges such as privacy constraints, sparse and irregular sampling, infinite-dimensionality, and non-Gaussian structures. To address these challenges, we introduce a novel framework named Smooth Flow Matching (SFM), tailored for generative modeling of functional data that enables statistical analysis without exposing sensitive real data. Under a copula framework, SFM constructs a semiparametric smooth flow to generate infinite-dimensional functional data, free of Gaussianity and low-rank assumptions. It is computationally efficient, handles irregular observations, and guarantees the smoothness of the generated functions, offering a practical and flexible solution in scenarios where existing deep generative methods are not applicable. Through extensive simulation studies, we demonstrate the advantages of SFM in terms of both synthetic data quality and computational efficiency. We then apply SFM to generate clinical trajectory data from the MIMIC-IV patient electronic health records (EHR) longitudinal database. Our analysis showcases the ability of SFM to produce high-quality surrogate data for downstream tasks, highlighting its potential to boost the utility of EHR data for clinical applications.
Sort, Partition, Randomize: Optimal Binary Hypothesis Testing under Local Differential Privacy
Elena Ghazi ⋅ Jawad Nasser ⋅ Flavio Calmon ⋅ Ibrahim Issa
We study optimal design of $\varepsilon$-locally differentially private mechanisms for binary hypothesis testing. Each observation is drawn from one of two known distributions $P_0,P_1$ on a finite alphabet of size $k$, privatized by a mechanism $Q$, and then used to infer which distribution generated the data. We measure testing utility using an $f$-divergence—including total variation, KL, and hockey-stick divergences—between the two induced output distributions. Previous work established structural properties of optimal mechanisms, but only yielded exponential-time algorithms. We prove a sharp structure: for every $\varepsilon$ and every $f$-divergence objective, after sorting the alphabet by likelihood ratio, there exists an optimal mechanism that partitions the sorted alphabet into contiguous blocks and applies randomized response to the block label. We call this class Sort–Partition–Randomize (SPR). This characterization yields an exact dynamic program that computes an optimal mechanism in $O(k^3)$ time, and more generally in $O(\ell k^2)$ time with an $\ell$-output budget. Our results make it possible to efficiently compute and characterize the exact optimum across the full privacy range, beyond asymptotic privacy regimes.
SparDA: Sparse Decoupled Attention for Efficient Long-Context LLM Inference
Yaosheng Fu ⋅ Guangxuan Xiao ⋅ Xin Dong ⋅ Song Han ⋅ Oreste Villa
Sparse attention reduces compute and memory bandwidth for long-context LLM inference. However, two key challenges remain: (1) KV cache capacity still grows with sequence length, and offloading to CPU memory introduces a PCIe transfer bottleneck; (2) the sparse selection step itself retains $O(T^2)$ complexity and can dominate attention cost at long contexts. We propose SparDA, a decoupled sparse attention architecture that introduces a fourth per-layer projection, the Forecast, alongside Query, Key, and Value. The Forecast predicts the KV blocks needed by the next layer, enabling lookahead selection that overlaps CPU-to-GPU prefetch with current-layer execution. Because Forecast is decoupled from the attention query, our GQA implementation uses one Forecast head per GQA group, reducing selection overhead versus the original multi-head selector. SparDA adds $<$0.5\% parameters and trains only the Forecast projections by matching the original selector's attention distribution. On two sparse-pretrained 8B models, SparDA matches or slightly improves accuracy and delivers up to 1.25$\times$ prefill speedup and 1.7$\times$ decode speedup over the sparse-attention offload baseline. By enabling larger feasible batch sizes on a single GPU, SparDA further reaches up to 5.3$\times$ higher decode throughput than the non-offload sparse baseline.
Hyper-Connections (HC) extend residual connections into multiple streams, employing residual matrices for cross-stream mixing to enrich model expressivity. However, unconstrained mixing disrupts the identity mapping property intrinsic to the residual connection, causing unstable training. To address this, Manifold-Constrained Hyper-Connections (mHC) and its variants restrict these matrices to be doubly stochastic via Sinkhorn-Knopp (SK) algorithm or permutation-based parameterizations. We reveal three limitations of this doubly stochastic constraint: (1) identity degeneration, where learned matrices collapse around the identity initialization and diminish cross-stream interactions, (2) an expressivity bottleneck via spectral collapse, where the doubly stochastic constraint induces feature homogenization, and (3) parameterization inefficiencies, manifesting as unstable SK iterations or the factorial-scaling overhead of permutation-based parameterizations. To overcome these flaws, we propose Spectral-Sphere-Constrained Hyper-Connections (sHC). By confining residual matrices to a spectral norm sphere, sHC prevents spectral collapse and enables selective feature diversification. This shift eliminates unstable SK iterations and factorial parameterization, enabling expressive, non-degenerate residual matrices while preserving training stability.
Spectral Stratification of Semantic Abstraction in Vision-Language Models
Jeonghwan Cheon ⋅ Marin Vogelsang ⋅ Lukas Vogelsang ⋅ Pawan Sinha
Vision-language models now serve as general-purpose semantic embedding spaces, but how conceptual abstraction is organized within such spaces remains poorly understood. Here, we show that abstraction in these embeddings is spectrally stratified. Specifically, low-rank principal-component subspaces encode broad conceptual structure, while higher-rank components carry progressively finer-grained distinctions. This pattern holds across multiple contrastive vision-language models and taxonomic datasets. Consistent with this stratification, rank-based modulation produces predictable behavioral shifts: retaining only the leading components preserves coarse retrieval but degrades fine-grained retrieval, while removing them selectively disrupts abstract category structure. Furthermore, rank-selective routing improves retrieval when the selected subspace matches the target level of abstraction. Notably, compact spectral subspaces, which preserve taxonomic structure while truncating high-rank residuals, exhibit substantially better alignment with human abstraction behavior than the full-rank model. Together, these results reveal that vision-language embeddings are not semantically homogeneous. Instead, hierarchical abstraction is stratified along the spectral geometry, and the structure most aligned with human cognition is concentrated in a compact subspace, suggesting that human-aligned semantics are a recoverable substructure of, rather than a property of, the full embedding.
Speed Predictions for Online Energy-Efficient Scheduling
Eric Balkanski ⋅ Jingwei Li ⋅ Clifford Stein ⋅ Cherlin Zhu
We consider the scheduling problem of online speed scaling where the goal is to minimize the energy consumption of a machine that controls the speed at which jobs are processed. Recent work has leveraged the learning-augmented framework, where the algorithm is provided with predictions about jobs that will arrive in the future, to manage power usage more efficiently. This paper proposes a novel prediction model for speed scaling where the predictions are about the machine speed (the output), instead of the jobs (the input). Machine speed predictions have multiple advantages: they are succinct, admit strong PAC-learnability guarantees, can be provided dynamically, and lead to a natural definition of smoothness. We give an algorithm for dynamic machine speed predictions that is $(1+\epsilon)$-consistent and $O(1)$-robust. For offline machine speed predictions and job speed predictions, we provide an algorithm that achieves the stronger guarantee of $(1+\epsilon)$-smoothness, while maintaining $O(1)$-robustness. These guarantees are comparable to previous work, but do not require predicting the entire input.
Spend Only What You Need: Defect-Aware Residual Coverage for Efficient Multi-Agent Reasoning
Maisha Maliha ⋅ Dean F Hougen
Multi-agent orchestration over large language models is increasingly used to improve reasoning accuracy, especially on problems that benefit from critique, verification, specialization, or consensus, but these gains often come with inference costs that are not explicitly controlled. Many systems spend similar compute on straightforward queries and genuinely ambiguous or expert-level ones. Existing methods typically follow fixed collaboration protocols, compile task-level workflows offline, route queries among models or collaboration modes, or use learned controllers whose state does not explicitly identify which reasoning defects remain unresolved. As a result, they do not directly decide during inference whether the current multi-agent trajectory still justifies another agent call. We introduce Defect-Aware Residual Coverage (DARC), a training-free inference-time controller for adaptive multi-agent reasoning that represents the current trajectory using four residual defect dimensions: answer uncertainty, claim-level contradiction, verification failure, and aspect under-coverage. DARC selects the next agent by maximizing cost-normalized submodular marginal coverage over the remaining residuals. Each candidate agent receives a role-induced capability profile from frozen embeddings of its natural-language role description, enabling DARC to operate without task-specific supervision, learned routing parameters, or fine-tuning. Across five reasoning and multimodal suites, MMLU-Pro, GPQA-Diamond, LiveBench, MMMU-Pro, and HLE, DARC achieves the strongest accuracy under the main shared heterogeneous six-agent pool while using substantially fewer tokens and agent calls than recent workflow, adaptive orchestration, and cost-aware routing baselines, with additional large-pool experiments showing consistent scaling behavior. It also outperforms the single-call frontier reasoning models tested, showing that residual-aware selective invocation can improve both answer quality and inference efficiency.
StarCraft Motion: A Dataset for Agent Simulation in Adversarial and Partially Observable Scenarios
Yi-Chung Chen ⋅ Mingyu Kim ⋅ Ruqi Bai ⋅ James Z Hare ⋅ Jing Gao ⋅ David Inouye
Agent simulation aims to model the future behavior of interacting agents, but existing benchmarks have largely focused on structured domains such as autonomous driving. Adversarial and partially observable settings remain less explored, despite their importance for modeling strategic multi-agent behavior. To address this gap, we introduce StarCraft Motion, a large-scale dataset for agent simulation built from human StarCraft~II replays. Our processing pipeline converts raw replays into standardized simulation scenarios by extracting continuous unit trajectories, deriving command-based unit-level intent labels, and aligning game states with player-specific fog-of-war observations. This enables direct study of behavior, intent, and opponent responses under competitive partial observability. As an initial study, we evaluate autoregressive simulation methods on StarCraft Motion and introduce HMART, a hierarchical baseline that extends SMART with learnable player-level query aggregation for efficient global-context modeling in large-agent-count scenarios. Experiments show that global context improves observer-unit simulation and intent prediction, while closed-loop fine-tuning further improves rollout quality. However, accurately capturing intent initiation and transitions remains difficult. We also find that opponent modeling from partial observations is substantially more challenging, and that additional global information can be misleading when it does not match the opponent's perspective. These results highlight StarCraft Motion as a useful dataset for studying scalable agent simulation in adversarial, partially observable environments.
StaRPO: Stability-Augmented Reinforcement Policy Optimization
Jinghan Zhang ⋅ Fengran Mo ⋅ Tharindu Cyril Weerasooriya ⋅ Ruimin Dai ⋅ Xiaoyan Han ⋅ Yanjie Fu ⋅ Dakuo Wang ⋅ Kunpeng Liu
Reinforcement learning (RL) is effective in enhancing the accuracy of large language models in complex reasoning tasks. Existing RL policy optimization frameworks rely on final-answer correctness as feedback signals and rarely capture the internal logical structure of the reasoning process. Consequently, the models would generate fluent and semantically relevant responses but logically inconsistent, structurally erratic, or redundant. To this end, we propose StaRPO, a stability-augmented reinforcement learning framework that explicitly incorporates reasoning stability into the optimization objective. Our StaRPO decomposes stability into two computable lightweight metrics: the Autocorrelation Function (ACF) to evaluate local step-to-step coherence, and Path Efficiency (PE) to evaluate global goal-directedness of the reasoning trajectory. These stability rewards are combined with task rewards to provide complementary and process-aware feedback. We validate the effectiveness of using ACF and PE rewards by showing their correlation with logic errors on two backbone models. Experiments on four reasoning benchmarks show that StaRPO consistently outperforms compared baselines and can enhance both final-answer accuracy and logical stability.
We study the complexity of smoothed agnostic learning, in which the learner competes with the best classifier in a target class under slight Gaussian perturbations of the inputs. Specifically, we focus on the prototypical task of agnostically learning halfspaces under subgaussian distributions in this model. The best known upper bound for this problem is based on $L_1$-polynomial regression and has complexity $d^{\tilde O(1/\sigma^2)\log(1/\epsilon)}$, where $\sigma$ is the smoothing parameter and $\epsilon$ is the excess error. Our main result is a Statistical Query (SQ) lower bound showing that this upper bound is close to best possible. In particular, we prove that, even for Gaussian marginals, any SQ algorithm for smoothed agnostic learning of halfspaces requires complexity $d^{\Omega(1/\sigma^2+\log(1/\epsilon))}$. This is the first non-trivial computational lower bound for this task, and it nearly matches the known upper bound. At a conceptual level, we show that the complexity of the problem is governed by the low-degree $L_1$ approximation of the smoothed target $T_\sigma f$, so that applying $L_1$-polynomial regression to the smoothed function is essentially optimal in the SQ model. Our proof proceeds by constructing a moment-matching hard distribution via linear programming duality; the dual program corresponds exactly to finding a low-degree approximating polynomial for $T_\sigma f$, which is the same approximation-theoretic condition underlying the upper bound. To instantiate this framework for halfspaces, we prove explicit lower bounds on the approximation degree of the smoothed sign function. A key ingredient is a new structural result: we construct a distribution that matches moments with a Gaussian while exhibiting periodic structure. This result underlies our $1/\sigma^2$-degree lower bound and may be of independent interest.
Steering Vectors as a Training Signal in LLM Post-Training
Tiejin Chen ⋅ Maunil R Vyas ⋅ Huaiyuan Yao ⋅ Hua Wei
Steering vectors (SVs) are residual-stream directions that shift the behavior of LLMs when added to hidden states at inference time. While prior work has mainly used SVs as post-hoc controls, we ask whether the same directions can also guide parameter updates during post-training. We study this question across supervised learning, including SFT and distillation, and reinforcement learning with verifiable rewards (RLVR). Our framework considers two intervention regimes: a hidden-state hook during teacher-forced supervised training, and an advantage-repair mechanism for zero-variance groups in GRPO. For each regime, we analyze three design axes, which are the steering direction, its placement, and the operation used to combine it with training. In supervised settings, SV injection improves over plain SFT and distillation, with gains scaling with the off-policy gap and reaching up to a $12\%$ improvement when distilling from thinking-mode teachers. In RL settings, applying a correctness-contrast direction as advantage repair on all-wrong groups recovers a learning signal that transfers to held-out math benchmarks. We further identify three failure boundaries. In detail, code generation can break the direction, cross-family layer transfer can break the placement, and inference-time application on an SV-trained checkpoint can break the intervention regime. Together, these results establish steering vectors as a conditional but effective training signal for LLM post-training. Our code can be found in Appendix Section A.
StereoPep: Do Molecular Models Understand Stereochemistry? A Benchmark on Synthetic Diastereomeric Peptides
Michael Desgagné ⋅ Amirabbas Kazeminia ⋅ Kübra Kaygisiz ⋅ Bradley Pentelute ⋅ Marinka Zitnik
Existing peptide models saturate natural-sequence proteomics benchmarks, but whether they capture the underlying physicochemical dynamics or merely pattern-match on sequence statistics remains unclear. Public peptide datasets offer no axis along which to test this: non-canonical residues and stereochemical variation are essentially absent. We introduce StereoPep, a benchmark of 48,788 chemically synthesized peptides spanning 11 libraries, produced in the laboratory via high-throughput flow synthesis and characterized experimentally by reverse-phase liquid chromatography retention time. Unlike model-generated synthetic data, every peptide in StereoPep is a real molecule with a real chromatographic measurement. The dataset is constructed around matched diastereomeric pairs (sequences identical in primary structure but differing at a single stereocenter), providing a direct test of whether models capture three-dimensional stereochemical information. StereoPep enables progress across multiple fields: it serves as a benchmark for stereochemistry-aware molecular representations and geometric deep learning, supports adapting protein language models to non-canonical residues, and underpins emerging proteomics multiplexing strategies that encode samples through retention-time shifts. Across specialized retention-time models, graph-based architectures, and protein language models, all approaches predict overall retention reasonably well (Pearson $r \approx 0.80$) but collapse on diastereomer pair discrimination (AUC $\approx 0.55$), revealing that current representations encode atomic composition far better than 3D structure.
StomataBench: Measuring Taxonomic Generalization in Stomatal Detection
Sainath Reddy Gummi ⋅ Hankui K Zhang ⋅ Chulwoo Pack ⋅ Shyam Solanki ⋅ Young Chang
Accelerating stomata measurement is essential for developing drought-resilient plants. However, most automated stomata detectors are tested under narrow imaging and species conditions. Their behavior under broader ecological distribution shift remains unclear. We introduce StomataBench, a benchmark for stomatal object detection across species, acquisition protocols, and biological density regimes. The benchmark uses a curated multispecies training set of 3,154 images with 134,802 annotated stomata from 21 woody species. It is evaluated on four test datasets totaling 19,657 images, covering diverse woody taxa and heterogeneous public crop sources. Unlike standard detection benchmarks that report only AP, StomataBench evaluates measurement reliability. We measure COCO AP, F1, score-threshold sensitivity, image-level count error, and stomatal density agreement. We benchmark sixteen detectors spanning two-stage, one-stage, transformer, open-vocabulary, and promptable foundation models. The results show that model rankings change with the biological objective. GDINO-SB provides the strongest average AP generalization, while SAM3-OD gives reliable operating point for count and density estimation. Conventional detectors remain competitive on near-domain woody plants, but foundation models are robust under harder ecological shifts. Failure analysis shows that far-OOD detection is often limited by missing stomata. These results identify cross-lineage proposal generation as a key unsolved problem for reliable stomatal phenotyping under ecological distribution shift.
Stop Using Plausibility as the Criterion for Explainable AI
Weina Jin ⋅ Xiaoxiao Li ⋅ Ghassan Hamarneh
Explainable artificial intelligence (XAI) is motivated by the problem of making AI predictions understandable, transparent, and responsible, as AI becomes increasingly impactful in society and high-stakes domains. The evaluation and optimization criteria of XAI are gatekeepers for XAI algorithms to achieve their expected goals and should withstand rigorous inspection. To improve the scientific rigor of XAI, we conduct the first comprehensive and critical examination of a common XAI criterion: plausibility. Plausibility assesses how convincing the AI explanation is to humans, and is usually quantified by metrics of feature localization or feature correlation. Our examination shows that plausibility is invalid to measure explainability, and human explanations are not the ground truth for XAI, because doing so ignores the necessary assumptions underpinning an explanation. One fundamental assumption is that AI explanation is supposed to behave adversarially, analogous to auditors' or doctors' roles of identifying potential problems. Evaluating or optimizing XAI to generate more plausible explanations is analogous to incentivizing (i.e., bribing) auditors/doctors to generate more positive reports, which is different from encouraging AI models to learn more plausible features (analogous to encouraging companies/patients to improve their conduct/health). Our examination further reveals the consequences of using plausibility as the XAI criterion, including increasing misleading explanations that manipulate users, deteriorating users' trust in the AI system, undermining human autonomy, being unable to achieve complementary human-AI task performance, and abandoning other possible approaches of enhancing understandability. Due to the invalidity of measurements and the unethical issues, this position paper argues that the AI community should stop using plausibility as the criterion to evaluate and optimize XAI algorithms. We also delineate new research approaches to improve XAI in trustworthiness, understandability, and utility to users including complementary human-AI task performance.
Machine learning (ML) predictions are increasingly being used to guide decision-making, giving rise to the problem of decision-focused learning (DFL) where predictors are optimized for downstream decision quality rather than accuracy alone. However, existing work assumes a single decision-maker optimizing in isolation. This paper formalizes strategic decision-focused learning, where an ML system predicts an exogenous state that some agents observe before playing a game. For example, a park ranger may predict wildlife locations to allocate anti-poaching patrols against strategic poachers. While the exogenous state is unaffected by agent actions, predictions influence agents' strategies and the resulting equilibrium. We find that strategic considerations fundamentally change the learning problem. In particular, we show the prediction accuracy–equilibrium payoff landscape can be non-monotonic---i.e., better predictions can degrade performance. We propose algorithmic approaches to address these challenges and validate them across benchmarks in wildlife conservation and infrastructure protection. Our theory and experiments highlight the importance of accounting for strategic interactions when designing predictors.
Causal representation learning aims to discover robust features by exploiting the causal structure underlying data generation. Existing methods require specifying the causal structure a priori, yet different structures demand fundamentally incompatible invariance constraints, and misspecification leads to representations that discard predictive information. We introduce SaCRL, a framework that jointly identifies the causal structure and learns the corresponding invariant representation without prior structural knowledge. Our approach formulates structure selection as a soft optimization over candidate invariances using HSIC-based violation metrics, with adaptive weights that automatically concentrate on the achievable structure. We provide theoretical guarantees for structure identification, invariance satisfaction, and out-of-distribution generalization. Empirically, SaCRL matches structure-specific oracles on synthetic and Colored MNIST benchmarks, achieves state-of-the-art accuracy on three DomainBed benchmarks (PACS, VLCS, OfficeHome), and degrades gracefully under structural misspecification and limited environment diversity. {Code is available at: \url{https://github.com/ax1375/sarl}}.
SyncWorld: Visual Calibration Enables World Models as Zero-Shot Simulators
Yuncong Yang ⋅ Zhengtao Han ⋅ Furkan Ozyurt ⋅ Zeyuan Yang ⋅ Han Yang ⋅ Junyi Cao ⋅ Haoyu Zhen ⋅ Yilun Du ⋅ Chuang Gan
World models are increasingly used as policy-in-the-loop imagination environments, where reliable rollouts require fine-grained controllability with respect to low-level robot actions. A key obstacle to scaling such models in robotics is that actions are not a universal language in pixel space: changes in visual environment, camera view, robot placement, or embodiment alter how the same numerical action manifests visually, leading to conflicting supervision under mixed training and brittle generalization at deployment. We introduce SyncWorld, an action-conditioned world model that serves as a zero-shot simulator across unseen environments without any additional training. SyncWorld leverages a visual calibration episode---paired frames and actions that showcase all the controllable degrees of freedom---to specify the setup-specific Action--Visual Mapping in context. Training with visual calibration contexts teaches the model to interpret actions through visual evidence and to leverage interaction history when explicit calibration is unavailable. Experiments show that SyncWorld can accurately simulate action outcomes in previously unseen settings, and that its capability of simulating rollouts enables test-time policy improvement without training.
TEMPO: Temporal Enforcement via Mode-Separated Policy Optimization for Trustworthy LLM Backtesting
Zeyu Zhang ⋅ Bradly Stadie
Backtesting large language models on historical events requires reasoning exclusively from information available before a specified cutoff date. Yet models routinely leak post-cutoff knowledge from pre-training into their reasoning, inflating apparent accuracy and undermining evaluation validity. Prompt-based constraints fail when suppressed content is causally related to the prediction, and knowledge unlearning cannot address this problem because temporal compliance is instance-specific: the same fact may be legitimate evidence for one cutoff date and a violation for another. Rather than erasing knowledge, the model must learn **temporal discipline**: selecting evidence conditioned on each instance's cutoff date. We propose **TEMPO** (**T**emporal **E**nforcement via **M**ode-separated **P**olicy **O**ptimization), which trains this discipline via two contributions: (1) a two-mode reward where a leakage mode drives post-cutoff claims to zero as a hard prerequisite before a performance mode optimizes task performance; and (2) a GRPO-based training pipeline that enables the model to discover temporally valid reasoning strategies. We prove that training monotonically decreases leakage, converges to the leak-free optimum, and improves task performance once compliance is achieved. On three prediction tasks and two models, TEMPO reduces leakage from 2$\sim$13\% to 0.6$\sim$3.7\% across all conditions, with task performance improving 6$\sim$13\% where strong pre-cutoff signals exist and maintained where the prediction task is inherently difficult from valid information alone.
Testable Learning of General Halfspaces under Massart Noise
Ilias Diakonikolas ⋅ Giannis Iakovidis ⋅ Daniel Kane ⋅ Sihan Liu
We study the algorithmic task of testably learning general Massart halfspaces under the Gaussian distribution. In the testable learning setting, the aim is the design of a tester-learner pair satisfying the following properties: (1) if the tester accepts, the learner outputs a hypothesis and a certificate that it achieves near-optimal error, and (2) it is highly unlikely that the tester rejects if the data satisfies the underlying assumptions. Our main result is the first testable learning algorithm for general halfspaces with Massart noise and Gaussian marginals. The complexity of our algorithm is $d^{\mathrm{polylog}(\min\{1/\gamma, 1/\epsilon \})}$, where $\epsilon$ is the excess error and $\gamma$ is the bias of the target halfspace, which qualitatively matches the known quasi-polynomial Statistical Query lower bound for the non-testable setting. The analysis of our algorithm hinges on a novel sandwiching polynomial approximation to the sign function with multiplicative error that may be of broader interest.
Test-time Risk Adaptation with Mixture of Agents
Mohamad Chehade ⋅ Amrit Singh Bedi ⋅ Souradip Chakraborty ⋅ Amy Zhang ⋅ Hao Zhu
Deployed reinforcement learning agents often face safety requirements that are specified only after training: new hazard maps, revised risk thresholds, or behavioral alignment constraints. We study zero-update deployment-time adaptation in which a fixed library of risk-neutral source policies must be reused under a newly specified reward–risk tradeoff. We propose TRAM (Test-time Risk Adaptation via Mixture of Agents), a source-scored composition rule that evaluates each source under the target reward and an occupancy-based deployment risk, then selects actions using risk-adjusted source scores. Unlike training-time risk-sensitive methods tied to a fixed surrogate such as return variance, TRAM supports spatial barrier exposure, divergence to a reference behavior, and local volatility risks specified at test time. We make the surrogate nature of the method explicit: TRAM is not claimed to solve the full occupancy-control problem of the stitched policy, but it admits a measurable source-hull mismatch term connecting source-scored risk to realized risk. Experiments in gridworlds, MuJoCo Reacher, Safety-Gymnasium, and an LLM alignment setting show that TRAM improves deployment risk while preserving reward and requires no parameter updates at test time.
The Master Key Hypothesis: Unlocking Cross-Model Capability Transfer via Linear Subspace Alignment
Rishab Balasubramanian ⋅ Pin-Jie Lin ⋅ Rituraj Sharma ⋅ Mohit Bansal ⋅ Tu Vu
We investigate whether post-trained capabilities can be transferred across model scales without retraining, and propose the Master Key Hypothesis, which states that model capabilities correspond to directions in a low-dimensional latent subspace that induce specific behaviors and are transferable across models through linear alignment. Based on the hypothesis, we introduce UNLOCK, a training-free and label-free framework that extracts a capability direction by contrasting activations between capability-present and capability-absent Source variants, aligns it with a Target model through a low-rank linear transformation, and applies it at inference time to elicit the behavior. Experiments on reasoning behaviors, including Chain-of-Thought (CoT) and mathematical reasoning, demonstrate substantial improvements across model scales without training. For example, transferring CoT reasoning from Qwen1.5-14B to Qwen1.5-7B yields an accuracy gain of 12.1% on MATH, and transferring a mathematical reasoning direction from Qwen3-4B-Base to Qwen3-14B-Base improves AGIEval Math accuracy from 61.1% to 71.3%, surpassing the 67.8% achieved by the 14B post-trained model. Our analysis shows that the success of transfer depends on the capabilities learned during pre-training, and that our intervention amplifies latent capabilities by sharpening the output distribution toward successful reasoning trajectories.
The Missing Positional Story in LLMs: A Case Study of Shift-Invariant Attention
Benjamin Huh ⋅ Hak Hyun Kim ⋅ Yuting Tian ⋅ Jason Peng ⋅ Christopher Kang ⋅ Soroush Vosoughi
Rotary positional embeddings (RoPE) are now the dominant positional mechanism in modern large language models. By construction, RoPE encodes a shift-invariant (SI) channel in attention: head logits can depend purely on token offset rather than absolute position. We show that trained models do not just inherit this SI channel; they actively learn to exploit it. This exploitation is load-bearing: SI ablations produce systematic degradation that tracks per-head SI amplitude under converging specificity controls, and SI structure appears even in models trained with absolute positional encodings, indicating that this is learned computation rather than a purely architectural artifact. This SI exploitation is also functionally meaningful: SI ablation preferentially disrupts offset-structured retrieval, most robustly in Llama and Mistral, with directional extension to naturalistic long-context settings. At the same time, our results surface a deeper question: is the SI channel currently underutilized? Many computations are position-invariant by nature --- recognizing that a pattern holds regardless of where it appears in context --- yet our evidence suggests current models allocate SI channels mostly to narrow positional and surface routing rather than these richer invariances. Strikingly, SI exploitation amplitude varies more than sixfold, a spread that holds across eleven models spanning seven architecture families, indicating that degree of SI use is a trainable property rather than an architectural given. This points to a practical direction: pretraining pressure toward semantic invariance tasks may push models to exploit SI channels for richer computation than what we observe today.
There are Levels to It: Red Teaming LLMs with Hierarchical Reinforcement Learning
Roman Belaire ⋅ Arunesh Sinha ⋅ Pradeep Varakantham
Red teaming is essential for securing Large Language Models, yet current automated methods remain limited by templates and single-turn attacks. To simulate the complex, interactive nature of real-world adversarial attacks, we introduce a novel red teaming paradigm designed to maximize expected cumulative harm through strategic interaction. By formalizing red teaming as a Markov Decision Process in a hierarchical reinforcement learning framework, we navigate the challenges of sparse rewards and long-horizon planning. Our generative agent learns diverse, multi-turn attacks using a token-level harm reward, consistently uncovering vulnerabilities that bypass baselines. This approach achieves a new state of the art and reframes LLM red teaming as a principled, trajectory-based process.
A central obstacle in nonlinear Bayesian filtering is representing the belief distribution. Moment-based filters address this by propagating polynomial moments and reconstructing a density from them. Recent work completes the predict-update loop via the maximum-entropy (MaxEnt) principle, but each step requires the partition function and its gradient, both $n$-dimensional integrals whose cost scales exponentially, restricting the demonstrated MaxEnt moment filtering to $n \le 4$. We avoid the partition function entirely by combining score matching with Stein's identity. In our setting, score matching reduces the density fit to a single linear solve whose coefficients are assembled directly from the propagated moments. The same parameters then drive Stein's identity to close the moment hierarchy during prediction and to recover posterior moments after each Bayesian update, keeping the full predict-update loop free of partition function evaluation. The resulting $\textbf{Score Kalman Filter}$ (SKF) reduces to the classical information-form Kalman filter as a special case and performs every step through linear algebra. On nonlinear coupled-oscillator networks, the SKF runs through $n=20$ and reports lower RMSE than the EKF, UKF, EnKF, and particle-filter baselines on the tested synthetic benchmarks.
The use of algorithmic predictions in decision-making leads to a feedback loop where the models we deploy actively influence the data distributions we see, and later use to retrain on. This dynamic was formalized by Perdomo et al. 2020 in their work on performative prediction. Our main result is an unconditional reduction showing that any no-regret algorithm deployed in performative settings converges to a (mixed) performatively stable equilibrium: a solution in which models actively shape data distributions in ways that their own predictions look optimal in hindsight. Prior to our work, all positive results in this area imposed strong restrictions on how models influenced distributions. By using a martingale argument and allowing randomization, we avoid any assumption on how populations respond to predictions and sidestep recent hardness results showing that deterministic stable models are in general PPAD-hard to compute. Lastly, on a more conceptual note, our connection sheds light on why common algorithms, like gradient descent, are naturally stabilizing and prevent runaway feedback loops. We hope our work enables future technical transfer of ideas between online optimization and performativity.
Topology-Reinforced Swin Transformer for Medical Image Analysis
Pengfei Gu ⋅ Huimin Li ⋅ Guangyu Meng ⋅ Hao Zheng ⋅ Haoteng Tang ⋅ Bin Fu ⋅ Danny Z Chen
Topological patterns in medical images, such as connected components and loops, across multiple spatial scales carry critical structural information, from microaneurysm-scale lesions to organ-level boundaries. Despite the success of hierarchical Vision Transformers (e.g., Swin Transformer) in medical image analysis, existing methods lack an explicit architectural scheme to represent and incorporate multi-scale topological structures through the Transformer hierarchy. In this paper, we propose \emph{Topology-Reinforced Swin Transformer (TRiST)}, a new Swin Transformer model family for medical image analysis, which reinforces multi-scale hierarchical topology into the hierarchical Transformer architecture. Instead of treating topology as an auxiliary descriptor or post hoc fusion cues, TRiST takes topology as a native part of representation construction, refinement, and token interaction. First, because topology does not compose hierarchically through pooling or interpolation, we develop a Hierarchical Multi-Scale Topology Representation algorithm that computes 2D persistent homology ($H_0$ and $H_1$ on image patches) at each native scale of Swin Transformer, constructing four topological representations aligned 1-to-1 with the Swin token grid. Second, since the persistence axis has an intrinsic semantic structure (i.e., short-lifetime features mainly capture noise and fine texture, whereas long-lifetime features capture stable anatomical structures), we design a Band-Aware $H_0/H_1$ Residual Refinement module that independently adapts six persistence sub-bands using dedicated gated residual MLPs. Third, to make topology take part in token interaction inside the Transformer, we introduce a Persistence-Band Progressive Attention Bias that injects stage-corresponding topology as an additive key-highlighting prior into shifted-window self-attention. Based on these strategies, we instantiate two task-specific models: Topo-SwinV2-B for classification and Topo-Swin-UNet for segmentation. Both models retain the original Swin-based backbone structure while equipping it with native multi-scale topological features. Experiments on five medical image datasets show consistent improvements over strong Swin-based baselines and competitive performance as existing topology-augmented methods.
TorchUMM: A Unified Multimodal Model Codebase for Evaluation, Analysis, and Post-training
Yinyi Luo ⋅ Wenwen Wang ⋅ Haoyue Bai ⋅ Hongyu Zhu ⋅ Hao Chen ⋅ Pan He ⋅ Marios Savvides ⋅ Sharon Li ⋅ Jindong Wang
Recent advances in unified multimodal models (UMMs) have led to a proliferation of architectures capable of understanding, generating, and editing across visual and textual modalities. However, developing a unified framework for UMMs remains challenging due to the diversity of model architectures and the heterogeneity of training paradigms and implementation details. In this paper, we present TorchUMM, the first unified codebase for comprehensive evaluation, analysis, and post-training across diverse UMM backbones, tasks, and datasets. TorchUMM supports a broad spectrum of models covering a wide range of scales and design paradigms. Our benchmark encompasses three core task dimensions: multimodal understanding, generation, and editing, and integrates both established and novel datasets to evaluate perception, reasoning, compositionality, and instruction-following abilities. By providing a unified interface and standardized evaluation protocols, TorchUMM enables fair and reproducible comparisons across heterogeneous models and fosters deeper insights into their strengths and limitations, facilitating the development of more capable unified multimodal systems. Code is available at: https://anonymous.4open.science/r/TorchUmm-1E7E.
To See Far, Look Close: Evolutionary Forecasting for Long-term Time Series
Jiaming Ma ⋅ Siyuan Mu ⋅ Ruilin Tang ⋅ Haofeng Ma ⋅ Qihe Huang ⋅ Zhengyang Zhou ⋅ Pengkun Wang ⋅ Binwu Wang ⋅ Yang Wang
The prevailing Direct Forecasting (DF) paradigm dominates Long-term Time Series Forecasting (LTSF) by forcing models to predict the entire future horizon in a single forward pass. While efficient, this rigid coupling of output and evaluation horizons necessitates computationally prohibitive re-training for every target horizon. In this work, we uncover a counter-intuitive optimization anomaly: models trained on short horizons—when coupled with our proposed Evolutionary Forecasting (EF) paradigm—significantly outperform those trained directly on long horizons. We attribute this success to the mitigation of a fundamental optimization pathology inherent in DF, where conflicting gradients from distant futures cripple the learning of local dynamics. We establish EF as a unified generative framework, proving that DF is merely a degenerate special case of EF. Extensive experiments demonstrate that a singular EF model surpasses task-specific DF ensembles across standard benchmarks and exhibits robust asymptotic stability in extreme extrapolation. This work propels a paradigm shift in LTSF: moving from passive Static Mapping' to autonomous Evolutionary Reasoning.
Towards Hyperparameter Transfer for Differentially Private Optimization
Tianze Wang ⋅ Zhiqi Bu ⋅ Linjun Zhang
Scaling laws and hyperparameter tuning remain central challenges in training large-scale models, particularly under differential privacy (DP), where optimization is further complicated by noise injection and per-sample gradient clipping. While Maximal Update Parametrization ($\mu$P) allows for zero-shot hyperparameter transfer in standard training, we show that it fails under DP constraints due to the distinct spectral properties of high-dimensional noise versus low-rank gradients. In this work, we introduce DP-$\mu$P, a theoretically grounded framework that extends $\mu$P to the privacy-preserving setting. By analyzing the interaction between gradient clipping, noise injection, and feature learning, we derive a Signal-to-Noise Ratio (SNR) condition that governs layer-wise learning rate scaling. Combining this with our proposed spectral scaling formulation, we provide specific scaling rules for DP-SGD, DP-Adam, and DP-Muon. Empirically, we demonstrate that DP-$\mu$P enables effective zero-shot transfer of learning rates across model widths on diverse architectures (MLP, ViT, GPT-2), matching or exceeding the performance of individually tuned baselines while significantly reducing computational costs.
Towards Reliable LLM Evaluation: Correcting the Winner’s Curse in Adaptive Benchmarking
Yang Xu ⋅ Jiefu Zhang ⋅ Haixiang Sun ⋅ Zihan Zhou ⋅ Tianyu Cao ⋅ Vaneet Aggarwal
Adaptive prompt and program search makes LLM evaluation selection-sensitive. Once benchmark items are reused inside tuning, the observed winner's score need not estimate the fresh-data performance of the full tune-then-deploy procedure. We study inference for this procedure-level target under explicit tuning budgets. We propose SIREN, a selection-aware repeated-split reporting protocol that freezes the post-search shortlist, separates splitwise selection from held-out evaluation, and uses an item-level Gaussian multiplier bootstrap for uncertainty quantification. In a fixed-shortlist regime with smooth stabilized selection, the estimator admits a first-order item-level representation, and the bootstrap yields valid simultaneous inference on a finite budget grid. This supports confidence intervals for procedure-performance curves and pre-specified equal-budget and cross-budget comparisons. Controlled simulations and MMLU-Pro tuning experiments show that winner-based reporting can be optimistic and can change deployment conclusions, while SIREN remains close to the finite-sample reporting target.
Tracing Agentic Failure from the Flow of Success
Samuel (Min-Hsuan) Yeh ⋅ Yiwen Zhu ⋅ Shaleen Deep ⋅ Sharon Li
Failure attribution for LLM-based agentic systems, i.e., identifying which steps in a failure trajectory caused the task to fail, is critical for debugging and improving these systems. Existing approaches either rely on prompting-based pipelines, which are computationally expensive, or require post-training on failure trajectories with step-level error annotations, which are costly to collect and difficult to scale. We argue that a practical failure attribution model should be lightweight and trainable without step-level supervision on failure data. To this end, we address unsupervised failure attribution, i.e., training exclusively on successful trajectories and identifying error steps at inference time given a failure trajectory. We propose OAT, which casts this problem as one-class learning with neural controlled differential equations, modeling the dynamical pattern of successful trajectories in latent space. At inference time, each step in a failure trajectory is assigned an anomaly score based on its deviation from the dynamics learned on successful trajectories, which is then used to form a set of error steps. With training on only 100 successful trajectories, experiments show that OAT is 200--5000$\times$ faster than prompting-based baselines, and, at the same time, consistently outperforms them in both in-domain and out-of-distribution datasets with +20% and +7% F1 scores, respectively, demonstrating that OAT is a promising and efficient direction for diagnosing agentic system failures.
TrajWiki: Source-Grounded Memory Trajectories for Long-Horizon Dialogue Agents
Jingyu Sun ⋅ Yuyang Xue ⋅ Mingyang Li ⋅ Zhengtao Yao ⋅ Jiachen Li ⋅ Yang Cui ⋅ Wenhao Cai ⋅ Haozhe Liu ⋅ Fangying Wang ⋅ Magdalene K Montgomery ⋅ Syed M Baker ⋅ Hongpeng Zhou
Large language model agents have shown strong capabilities in generating coherent and contextually appropriate responses, yet robust long-horizon dialogue remains limited by the lack of external memory that is traceable, updatable, and diagnostically transparent. Existing memory-augmented agents often store memories as isolated records or overwritable states, making it difficult to preserve how information originates, evolves, conflicts, or becomes obsolete over time. We propose TrajWiki, a trajectory-based memory framework for long-horizon conversational agents. Instead of treating memory as static entries, TrajWiki represents each memory as a source-grounded evolution trajectory, maintained through immutable episodic snapshots and claim-level operations such as ADD, REVISE, and DEPRECATE. To reduce fragmentation and retrieval cost, TrajWiki further introduces Memory Wiki, a persistent intermediate layer that incrementally compiles dialogue history into structured and interlinked wiki pages capturing salient entities, events, quantities, topics, and conflicts. At inference time, queries are routed hierarchically from relevant wiki pages to linked memory trajectories, then to corresponding snapshots and source messages for evidence-grounded answer synthesis. Experiments on LoCoMo and MedMT show that TrajWiki improves long-horizon dialogue performance across both open-source and closed-source LLM backbones, while providing greater interpretability and diagnostic visibility into memory evolution, retrieval failures, and answer generation. Code is available at https://anonymous.4open.science/r/TrajWiki-F0EC/.
Transforming Image Editors into Video Editors
Feng Wang ⋅ Zijie Li ⋅ Ceyuan Yang ⋅ Alan Yuille ⋅ Peng Wang
Recent image editing systems have achieved impressive semantic understanding, visual fidelity, and instruction-following ability, while video editing remains substantially more difficult and costly. In this paper, we present a simple alternative to end-to-end video editing: instead of training a monolithic video editor, we transform a strong image editor into a video editor through anchor-based generation. Our key insight is that video editing can be decomposed into two subproblems: editing a sparse set of keyframes and propagating those edits across time. Based on this observation, we propose Anchor-based Video Editing (AVE), a two-stage framework in which a powerful image editor first performs composed editing on selected keyframes, and a motion-guided image-to-video diffusion model then generates the final video by treating the edited keyframes as fixed anchors. This design directly inherits the strengths of modern image editors while avoiding expensive end-to-end video editing training. Experiments on IVEBench and VIE-Bench show that AVE achieves strong performance in instruction following, temporal consistency, and content fidelity. Further ablations reveal that final video editing quality is strongly correlated with the quality of the image editor, suggesting that future progress in video editing may come from stronger image editing foundations and lightweight transfer to video.
Tri-Prompting: Controllable Video Generation with Scene, Subject, and Motion Prompts
Zhenghong Zhou ⋅ Xiaohang Zhan ⋅ Zhiqin Chen ⋅ Soo Ye Kim ⋅ Nanxuan Zhao ⋅ Haitian Zheng ⋅ Qing Liu ⋅ HE Zhang ⋅ Zhe Lin ⋅ Yuqian Zhou ⋅ Jiebo Luo
Recent video diffusion models achieve strong visual quality and temporal coherence, but still lack coordinated control over scene layout, customized subject identity, and camera/subject motion. We study controllable video generation from three prompts: a first-frame scene image, 3D-aware multi-view subject references, and a motion-driving signal. This setting is challenging because background regions are often trackable under camera motion, while foreground subjects can rotate, self-occlude, and reveal new regions that require identity-consistent appearance. We introduce Tri-Prompting, a video diffusion framework that combines multi-view subject conditioning with dual-conditioned motion control. Tri-Prompting uses XYZ tracking points for visible background motion and low-resolution RGB proxies for foreground subject pose, allowing the model to recover fine appearance from multi-view references while retaining flexibility for plausible subject-scene interactions. An inference-time ControlNet scale schedule further balances motion controllability and visual realism. We evaluate Tri-Prompting against specialized baselines: DaS for motion reconstruction and Phantom for subject-driven generation. Tri-Prompting achieves competitive or improved reconstruction quality, stronger multi-view identity preservation, and better 3D consistency, while enabling 3D-aware subject insertion and in-scene manipulation.
TritonTune: LLM-Guided Multi-Agent Optimization of GPU Kernel Configurations
Shukai Duan ⋅ Mihai Capotă ⋅ Guixiang Ma ⋅ Hou-Jen Ko ⋅ Rafael Wang ⋅ Steve Cho ⋅ Shahin Nazarian ⋅ Paul Bogdan
Tuning Triton GPU kernel launch configurations is a critical but labor-intensive step in production ML system deployment. Existing approaches rely on exhaustive autotuning, which requires manually defined search spaces and becomes prohibitively slow for the long tail of operator shapes. We present TritonTune, a multi-agent system that combines LLM-guided search with closed-loop empirical validation to optimize Triton kernel configurations safely and efficiently. TritonTune pairs two domain-specialized LLM agents with complementary expertise in data movement and compute resource allocation, resolves their proposals through a lightweight orchestration layer, and refines the best candidate through a phased benchmark search on real hardware. Per-agent feedback drives targeted corrections when regressions occur, and a hardware-validated fallback provides a worst-case guarantee absent from prior LLM-based approaches: the system can only improve performance or leave it unchanged. On 19 TritonBench kernels and 393 input shapes spanning hand-written, torch.compile-generated, and quantized operators, TritonTune achieves a 2.24× per-shape geometric-mean speedup on an NVIDIA V100 with 80% of shapes improved, under a closed-loop fallback that guarantees no accepted shape regresses below the original. Cross-GPU runs on L40S, A40, and A100 further confirm that our design generalizes beyond V100. These results show that LLM-guided multi-agent optimization, when grounded in hardware measurement, can serve as a practical, safe complement to exhaustive autotuning.
UMAS: System-Level Uncertainty Quantification for Multi-Agent LLM Systems
Hanwen Li ⋅ Jinhao Duan ⋅ Xiaoshuang Shi ⋅ Yue Zhang ⋅ Tianlong Chen ⋅ Kaidi Xu ⋅ Chenxi Yuan
Multi-Agent Systems (MAS) are a promising paradigm for improving the reasoning capabilities of large language models, yet they remain prone to hallucinations and erroneous outputs. Uncertainty Quantification (UQ) is crucial for assessing system reliability, but existing methods are largely designed for single-agent settings; how to exploit MAS structure for UQ while keeping inference cost-neutral remains underexplored. We propose UMAS, a parameter-free, cost-neutral, system-level UQ framework that estimates the credibility of inter-agent influence from each generation’s intrinsic confidence. UMAS uses these credibility signals to modulate how uncertainty is updated at each node, and then aggregates node-level uncertainty into a system-level estimate. Extensive evaluations on Debate and DyLAN across diverse benchmarks show that UMAS consistently outperforms state-of-the-art baselines by an average of 10.49 AUROC points. Beyond uncertainty estimation, UMAS enables hallucination detection and uncertainty-aware answer selection, improving MAS accuracy by up to 12.6 points on specific tasks while enhancing reliability.
Uncertainty Aware SURE Transfer Learning for Classification Problems
Haoyue Li ⋅ Shubo Li ⋅ Runze Li
Transfer learning is a powerful approach for improving classification performance when the target dataset contains limited observations. However, individual-level source data are often unavailable due to privacy or access constraints. We propose GSURE-Trans, an uncertainty-aware summary-level transfer learning framework for logistic classification that uses target individual-level data together with only source coefficient estimates and standard errors. By introducing and profiling out an auxiliary bridge parameter, GSURE-Trans induces a coordinatewise Huber penalty that accounts for both source uncertainty and source-target coefficient discrepancies. To further prevent negative transfer at study level, we develop a new criterion, generalized Stein unbiased risk estimate (GSURE), that adaptively selects the scale of source borrowing. Theoretically, we establish uniform consistency of GSURE and an oracle inequality for the selected transfer weight. Simulations and real data application show that GSURE-Trans improves prediction when sources are compatible and down-weights heterogeneous sources when transfer is harmful.
Uncertainty-Guided Reward Labeling for Reinforcement Learning under Limited Feedback
Renhao Zhang ⋅ Shreyas Chaudhari ⋅ Bruno Silva
In reinforcement learning from limited feedback (RLLF), only a small fraction of an offline dataset can be labeled with rewards, and the central question is which samples should be labeled to learn a strong policy from the resulting partially labeled dataset. Prior work formalized this as a reward-selection problem by focusing on the selection stage while treating downstream policy learning as a black box, in a regime where queried rewards are not retained for reward-model training. We instead study the retained-label setting, where queried rewards can be stored and used to fit a reward model before policy learning. We bound the suboptimality of the learned policy by two sources of error: one from offline RL on an offline dataset, and one from reward-model uncertainty. Since reward selection cannot change the offline dataset, the limited labeling budget must be used to strategically reduce reward uncertainty. Motivated by RLLF's observation that useful rewards tend to keep the agent on high-return trajectories, we propose successor-guided uncertainty reduction (SURE), which uses successor features to select rewards that are both reachable to high-valued states and uncertainty-reducing. Theoretically, we derive SURE from a bound-induced design objective and characterize its exact one-step marginal gain. Empirically, SURE reaches near full-feedback performance with few reward labels across a variety of domains, yielding a strong method for feedback-efficient reinforcement learning.
Many deep learning models exhibit a double-descent phenomenon, where test loss exhibits a sharp peak near the interpolation threshold and then descends a second time as model size grows further, contrary to the U-shape predicted by the classical bias–variance tradeoff. The double-descent phenomenon has been found and explained in toy classical models, but is not well-understood in modern deep learning despite extensive empirical study. We interpret double descent through the novel lens of universal compression. Specifically, we upper bound the maximum-likelihood test loss as a sum of three terms: an approximation error, a minimax batch regret, and an MLE-vs-Bayes gap. We show that the minimax Bayes predictor, unlike the MLE, does not exhibit the double-descent peak. Furthermore, we isolate each term through experiments with uniform random labels, and show that double descent is primarily caused by the MLE-vs-Bayes gap in this setting; here, the MLE cross-entropy grows to be roughly five times larger at the double-descent peak, while the minimax Bayes predictor cross-entropy remains flat. Additionally, we show the possibility of a second ascent in test loss at very large model sizes, and motivate this theoretically through the minimax batch regret term of our decomposition.
Understanding Graph Self-Supervised Pre-training under Distribution Shifts: A Scaling Law Perspective
Bingheng Li ⋅ Shikun Liu ⋅ Yu Song ⋅ Jay Revolinsky ⋅ Haoyu Han ⋅ Jiayuan Ding ⋅ Hua Liu ⋅ Jiliang Tang
Scaling laws have played a fundamental role in the development of foundation models for NLP and vision, but their applicability to large-scale pretrained graph-based models remains unclear, particularly under distribution shifts intrinsic to graph data. In this work, we systematically investigate how model capacity and data scale affect downstream performance in graph pre-training under distribution shifts. To disentangle how distribution shifts impact the scaling, we construct synthetic benchmarks based on contextual stochastic block models, with precise control over both structural and feature-level shifts across the pre-training and testing graphs. Our initial experiments on GCN, a standard Graph Neural Network (GNN) baseline, reveal a striking asymmetry: increasing model capacity consistently improves performance, while increasing data size often degrades it, even under mild shift. We show that this degradation is not inevitable; properly configuring the pretraining model with deeper, wider, and transformer-based architectures enables favorable data scaling, even when distribution shifts. As data scales, graph transformer models achieve up to +9\% gains over GCN across synthetic and real-world graph domain-adaptation tasks. To explain this phenomenon, we develop a theoretical framework based on Fisher separability and Wasserstein domain divergence, which formally characterizes how distribution shifts affect representation transferability. Our results highlight architecture- and shift-aware strategies as the key to unlock scalable graph-based model pre-training.
UniPath: Adaptive Coordination of Understanding and Generation for Unified Multimodal Reasoning
Haoyue Bai ⋅ Yinyi Luo ⋅ Wenwen Wang ⋅ Qingsong Wen ⋅ Jindong Wang
Unified multimodal models (UMMs) aim to integrate understanding and generation within a single architecture. However, it remains underexplored how to effectively coordinate these two capabilities for more effective and efficient reasoning. Existing coordination approaches either perform coupling during training, without explicit inference-time coordination, or impose a fixed coordination pattern for all inputs. In this work, we show that multimodal tasks exhibit substantial coordination-path diversity: different inputs favor different coordination paths. This suggests that exploiting such diversity is key to improving performance. We propose UniPath, a framework for adaptively modeling and exploiting coordination-path diversity. Instead of enforcing a single coordination pattern, we represent task solving as the selection and execution of a path, ranging from direct answering to textual inference, visual-thought construction, and hypothesis-based exploration. We construct role-aligned trajectories to train a path-conditioned executor and introduce a lightweight planner mechanism to enable input-dependent path selection. Experiments show that leveraging coordination-path diversity improves performance over fixed coordination strategies while providing interpretable intermediate behaviors. The code is available at: https://anonymous.4open.science/r/UniPath.
UniReFP: Robust Unified Fingerprinting for Vision Models against Cross-Task Repurposing Attacks
Ziye Geng ⋅ Guang Yang ⋅ Yihang Chen ⋅ Lingfeng Yao ⋅ Xing Shi ⋅ Miao Pan ⋅ Xin Fu ⋅ Changqing Luo
We identify, for the first time, a new model modification attack—the cross-task model repurposing attack—that can render fingerprints generated by existing model fingerprinting approaches inapplicable. To address this challenge, we propose UniReFP—a novel unified model fingerprinting framework applicable to diverse vision models across different tasks—that utilizes ownership evidence in a shared class-level semantic space rather than original task-specific output space, enabling effective ownership verification when a protected model is repurposed across tasks with heterogeneous output formats. Specifically, UniReFP constructs a surrogate classifier by repurposing the protected model, enabling fingerprints to be generated independently of the original task-dependent output space of the protected model. Moreover, it optimizes grouped fingerprints to encode ownership evidence: fingerprints within the same group are encouraged to induce consistent semantic responses and intermediate representations on the surrogate classifier, while producing dispersed responses on independently trained reference classifiers. During verification, UniReFP uses a task-aware semantic projection mechanism to map heterogeneous suspect-model outputs into unified semantic-presence vectors, and determines ownership by measuring inner-group consistency. Extensive experimental results validate the effectiveness of UniReFP, consistently showing superior performance under cross-task repurposing attacks, commonly studied model modification attacks, and even their combinations.
Useful Memories Become Faulty When Continuously Updated by LLMs
Dylan Zhang ⋅ Yanshan Lin ⋅ Zhengkun Wu ⋅ Yihang Sun ⋅ Bingxuan Li ⋅ Dianqi Li ⋅ Hao Peng
Learning from past experience requires forming abstractions that can be reused in future problems. Recent work on agentic-memory systems has explored a practical route to continuously improving LLM agents after deployment without parameter updates: a textual abstraction is derived from each history and stored in memory, then continuously updated with more interactions. Yet we show that such textual abstractions produced by today's LLMs are often faulty, even when derived from useful experiences. Over time, the memory becomes less useful and even harmful. More surprisingly, even when abstracting from ground-truth solutions, GPT-5.4 fails on 54% of a set of ARC-AGI problems it had previously solved without memory. We attribute this to the iterative update process: the same trajectories yield qualitatively different memories under different update schedules, while an episodic-only control over those trajectories remains competitive with the consolidators we test---pinning the failure on the consolidation step, not the underlying experience. In our ARC-AGI Stream environment designed to trace memory consolidation behavior, when agents are given additional actions, they tend to keep episodic memory and double the accuracy of their forced-consolidation counterparts; removing consolidation entirely (episodic management only) matches this auto mode. These results suggest that current LLMs should not recursively rewrite their own experience into stable long-term knowledge. Robust agent memory should treat raw episodes as first-class evidence and make abstraction selective, delayed, and explicitly gated rather than mandatory after every interaction.
Value-Aware Stochastic KV Cache Eviction for Reasoning Models
Ting-Yun Chang ⋅ Harvey Yiyun Fu ⋅ Deqing Fu ⋅ Chenghao Yang ⋅ Jesse Thomason ⋅ Robin Jia
Reasoning models improve accuracy through extended chains of thought, but their long outputs create a memory and compute bottleneck. KV cache eviction methods reduce this cost by evicting unimportant key-value pairs from the cache, yet they suffer larger accuracy degradation than selection-based sparse attention alternatives, which keep the full KV cache. We identify key factors crucial to KV cache eviction accuracy. First, a small fraction of value states have abnormally large magnitudes, and evicting them causes catastrophic failure where models enter repetitive reasoning loops. Second, introducing stochasticity during eviction improves accuracy by increasing cache diversity. Based on these findings, we propose Value-aware Stochastic KV Cache Eviction (VaSE), a training-free recipe that protects large-magnitude value states and promotes diverse eviction decisions. Across six reasoning tasks, Qwen3 models using VaSE with 4x KV cache compression achieve comparable or better average accuracies to the SOTA selection method under the same level of sparsity, while enabling a static memory footprint that selection methods cannot offer. Our method also generalizes as a recipe, with its key factors improving strong eviction methods by 5 points on average.
Value Entanglement: Conflation Between Different Kinds of Good In (Some) Large Language Models
Seong Hah Cho ⋅ Junyi Li ⋅ Anna Leshinskaya
Value alignment of Large Language Models (LLMs) requires us to empirically measure these models' actual, acquired representation of value. Among the characteristics of value representation in humans is that they distinguish among value of different kinds. We investigate whether LLMs likewise distinguish three different kinds of good: moral, grammatical, and economic. By probing model behavior, embeddings, and residual stream activations, we report pervasive cases of value entanglement: a conflation between these distinct representations of value. Specifically, both grammatical and economic valuation was found to be overly influenced by moral value, relative to human norms. This conflation was repaired by selective ablation of the activation vectors associated with morality.
Variational Wasserstein Model on Riemannian Manifolds for Image Segmentation
Jisui Huang ⋅ Yue Wu ⋅ Ke Chen ⋅ Na Lei
The data fidelity term plays a crucial role in variational image segmentation. Recently, optimal transport (OT)-based variational models have improved segmentation by globally matching predicted feature distributions with reference distributions. However, existing OT-based methods usually rely on color or intensity similarity, which can be insufficient when foreground and background regions share similar appearance. We address this limitation by incorporating geodesic distance into the OT cost on a Riemannian feature manifold, allowing the transport cost to jointly encode spatial proximity, appearance similarity, and boundary information. The proposed model is well-defined: we prove existence of minimizers and convexity of the energy functional. It is also tractable: the OT terms admit differentiable transport-map representations, avoiding storage of the full pairwise transport matrix and enabling efficient gradient-based optimization. Experiments on BraTS and RESECT show that our method consistently outperforms traditional variational models, OT-based baselines, and prompt-based deep segmentation models, particularly when foreground and background have overlapping intensity or color patterns.
Verifiers in the Loop: Decoding Time Verification for Code Translation
Tianyang Zhou ⋅ Somesh Jha ⋅ Mihai Christodorescu ⋅ Kirill Levchenko ⋅ Varun Chandrasekaran
Test-time scaling is an important mechanism for improving large language models, especially on tasks with deterministic verifiers. Code translation is a canonical example: the source program constrains valid outputs, while compilers, type check- ers, and behavioral checks provide exact pass/fail feedback. Existing approaches typically apply these verifiers only after generation, which is inefficient because early errors corrupt the autoregressive context and are rarely corrected later. We introduce Decoding Time Verification (DTV), a framework that integrates deter- ministic program verification directly into the decoding loop. DTV interleaves generation with verifier calls under a state-machine controller that enforces valid prefixes, using structural-boundary checks and structure-aware rollback to prevent error propagation while reducing wasted tokens. We evaluate DTV on C-to-Rust and JavaScript-to-TypeScript translation. Using Qwen3-4B as the primary genera- tor under matched token budgets, DTV improves pass rates from 72.3% to 82.0% on C-to-Rust and from 33.3% to 46.0% on JavaScript-to-TypeScript relative to matched self-refinement baselines, while using fewer tokens per case; the same trend largely transfers to Gemma-4-E4B. In the evaluated cost-matched grid, DTV achieves a more favorable pass-rate-cost tradeoff than post-hoc verification or sampling-based scaling. These results show that verifier-guided decoding is an effective use of inference-time compute for code translation.
ViT-AdaLA: Adapting Vision Transformers with Linear Attention
Yifan Li ⋅ Seunghyun Yoon ⋅ Viet Lai ⋅ Franck Dernoncourt ⋅ Jason Kuen ⋅ Yu Kong ⋅ Trung Bui
Vision Transformers (ViTs) based vision foundation models (VFMs) have achieved remarkable performance across diverse vision tasks, but suffer from quadratic complexity that limits scalability to long sequences. Existing linear attention approaches for ViTs are typically trained from scratch, requiring substantial computational resources, while linearization-based methods developed for large language model decoders do not transfer well to ViTs. To address these challenges, we propose ViT-AdaLA, a novel framework for effectively adapting and transferring prior knowledge from VFMs to linear attention ViTs. ViT-AdaLA consists of three stages: attention alignment, feature alignment, and supervised fine-tuning. In the attention alignment stage, we align vanilla linear attention with the original softmax-based attention in each block to approximate the behavior of softmax attention. However, residual approximation errors inevitably accumulate across layers. We mitigate this by fine-tuning the linearized ViT to align its final-layer features with a frozen softmax VFM teacher. Finally, the adapted prior knowledge is transferred to downstream tasks through supervised fine-tuning. Extensive experiments on classification and segmentation tasks demonstrate the effectiveness and generality of ViT-AdaLA over various state-of-the-art linear attention counterpart.
What should post-training optimize? A test-time scaling law perspective
Muheng Li ⋅ Jian Qian ⋅ Wenlong Mou
Large language models are increasingly deployed with test-time strategies: sample $N$ responses, score them with a reward model or verifier, and return the best. This deployment rule exposes a mismatch in post-training: standard objectives optimize the mean reward of a single response, whereas best-of-$N$ performance is governed by the upper tail of the reward distribution. Recent test-time-aware objectives partly address this mismatch, but typically assume that training can use the same per-prompt rollout budget as deployment, which is impractical when post-training must cover many prompts while deployment can allocate much larger per-prompt test-time compute. We study this budget-mismatch regime, where only $m\ll N$ per-prompt rollouts are available during training but the target objective is best-of-$N$ deployment. Under structural assumptions on the reward tails, we show that the policy gradient of the best-of-$N$ objective can be approximated from a much smaller rollout group by extrapolating upper-tail statistics. This yields a family of Tail-Extrapolated estimators for best-of-$N$-oriented post-training: a simple direct estimator, Tail-Extrapolated Advantage (TEA), and a fixed-order debiased Prefix-TEA estimator based on moment cancellation. Experiments on instruction-following tasks show that TEA and Prefix-TEA improve best-of-$N$ performance across different language models, reward models and datasets under various training and test-time budget settings.
When Are Teacher Tokens Reliable? Position-Weighted On-Policy Self-Distillation for Reasoning
Xiaogeng Liu ⋅ Xinyan Wang ⋅ Yingzi Ma ⋅ Yechao Zhang ⋅ Chaowei Xiao
On-policy self-distillation (OPSD) trains a student on its own rollouts using a privileged teacher, but its standard objective weights all generated tokens equally, implicitly treating the privileged teacher target as equally reliable at every student-visited prefix. Existing entropy-based OPD methods relax this uniformity by modulating token-level supervision with teacher entropy, but high teacher entropy in reasoning has an ambiguous reliability meaning: it can reflect either non-viable uncertainty or benign solution diversity. To identify this phenomenon, we introduce a branch-viability diagnostic. Specifically, we record next-token alternatives from the privileged-answer teacher prompt, force each alternative after the student prompt plus its on-policy spine prefix, and test whether the resulting student-template continuation recovers the correct answer. On Qwen3-4B, we find that an oriented within-sequence position score is the strongest tested predictor of teacher-token reliability, reaching an area-under-ROC-curve (AUROC) of 0.83 with a 95% cluster-bootstrap interval of [0.68, 0.96]; local uncertainty scores are at most 0.58. Motivated by this trajectory-level structure, we propose Position-Weighted On-Policy Self-Distillation (PW-OPSD), which applies an increasing position weight while keeping the same student rollout, privileged teacher pass, and clipped forward-KL target as OPSD. In our comprehensive evaluations with different random seeds, the diagnostic-derived PW-OPSD improves AIME 2024 and AIME 2025 Avg@12 by +1.0 and +1.1 points, and a generalization evaluation on the larger-scale model DeepSeek-R1-Distill-Llama-8B also demonstrates consistent improvements. These results show that teacher-token reliability in reasoning distillation is trajectory-structured and can be utilized without additional teacher computation.
When Dynamics Shift, Robust Task Inference Wins: Offline Imitation Learning with Behavior Foundation Models Revisited
Rishabh Agrawal ⋅ Rahul Jain ⋅ Ashutosh Nayyar
Behavior Foundation Models (BFMs) enable scalable imitation learning (IL) by pretraining task-agnostic representations that can be rapidly adapted to new tasks. However, existing BFMs assume fixed environment dynamics, limiting their robustness under real-world shifts such as changes in friction, actuation, or sensor noise. We address this by formulating BFM task-inference as a robust minimax optimization problem, enabling adaptation to worst-case dynamics perturbations without modifying pretraining. To the best of our knowledge, this is the first BFM-based framework that achieves robustness to dynamics shifts while relying solely on offline data from a single nominal environment. Our approach significantly outperforms standard BFM and robust offline IL baselines under dynamics shifts. These results demonstrate that robust policy can be achieved entirely at task-inference time, improving the practicality of BFMs in dynamic settings.
When Policies Cannot Be Retrained: A Unified Closed-Form View of Post-Training Steering in Offline Reinforcement Learning
Elias Hossain ⋅ Mohammad J Basher ⋅ Ivan Garibay ⋅ Ozlem Garibay ⋅ Niloofar Yousefi
Offline RL can learn effective policies from fixed datasets, but deployment objectives often shift after training, while the trained actor may be frozen due to data, cost, or governance constraints. We study deployment-time adaptation of frozen offline actors using Product-of-Experts (PoE) composition with a goal-conditioned prior. Our main practical finding is graceful degradation rather than universal improvement: with degraded or random priors, precision-weighted PoE remains anchored to the frozen actor, whereas additive and prior-only adaptation often collapse, and a KL-budget selector typically reaches a near-oracle operating point. We also clarify that, for diagonal-Gaussian actors and priors, PoE with coefficient $\alpha$ induces the same deterministic policy as KL-regularized adaptation with $\beta=\alpha/(1-\alpha)$, with posterior covariance differences cancelling under deterministic action selection. Across D4RL MuJoCo and AntMaze diagnostics, results reveal an actor-competence ceiling: composition helps or preserves performance when the frozen actor is sufficiently competent, but cannot recover when the actor itself fails. Swept CQL/IQL-guided and SF/GPI baselines are competitive in some settings, but do not eliminate this regime boundary. Thus, PoE/KL-Reg is best viewed as an actor-anchored safety layer for deployment-time objective shift, not as a general return-maximization method, with effectiveness governed by actor competence rather than knob choice.
Where You Backpropagate Matters: Token Hypothesis for Memory-Efficient Fine-Tuning
Md Kowsher ⋅ Chen Chen
Fine-tuning large transformers routes gradients through every token position, paying the cost in activation memory that scales linearly with sequence length and dominates the GPU budget. Existing efficient methods reduce the parameter side---low-rank adapters, prefix tuning, weight-decomposed updates---but leave the activation footprint untouched. We present the Token Hypothesis, a memory-efficient fine-tuning procedure motivated by a Neural Tangent Kernel analysis of how fine-tuning signal is distributed across token positions. We prove that every position is a low-dimensional capacity bottleneck whose width does not grow with the model, that positions with aligned hidden-state geometry are interchangeable in bidirectional models, and that causal positions form a monotone capacity chain in which later positions strictly dominate earlier ones. The analysis pins down how many positions are needed and which ones, both computable from forward passes alone: any subset suffices in bidirectional models, while the last few positions suffice in causal ones. We translate this into a procedure that backpropagates through only a small subset of positions while running the full forward pass over the rest. Empirically, the procedure matches or exceeds full-sequence fine-tuning across six task families---commonsense reasoning, mathematical reasoning, visual question answering, video question answering, GLUE, and image classification---and five backbones spanning bidirectional and causal architectures. It reduces activation memory substantially, translating to up to ∼ 20% lower total GPU memory (∼ 33GB) on long-context tasks, and composes cleanly with parameter-efficient methods such as LoRA and DoRA.
Why Cancer cfDNA Models Fail on Chronic Disease: A Geometric Information-Theoretic Bound and Its Architectural Implications
Fereshteh Abedini ⋅ Soheil Damangir
Cell-free DNA (cfDNA) liquid biopsy has been clinically routine for cancer detection and monitoring for years but has yet to produce applications in chronic diseases of parenchymal organs such as fibrotic liver, kidney, and lung disease, despite diseased organs shedding orders of magnitude more cfDNA into the bloodstream than tumors do. This gap is structural: methods developed for cancer have been adapted for chronic disease without a theoretical framework establishing when this should work or where it should break down. We formalize cfDNA classification as recovering a disease-induced shift on a low-dimensional submanifold of the simplex over molecular configurations, observed through sparse genomic windows. The formalization reveals that cancer and chronic disease occupy structurally distinct regimes parameterized by one dimensionless quantity: the inverse participation ratio $c(v)$ of the disease perturbation across windows. Cancer is small-$c(v)$: signal on a few genomic hotspots. Chronic disease is large-$c(v)$: signal spread across many co-regulated regulatory programs. We prove an information-theoretic lower bound: any classifier observing $k$ windows recovers at most a $\sqrt{k/c(v)}$ fraction of the available information in the local-asymptotic-normality regime, regardless of per-cfDNA model complexity. The bound applies architecture-agnostically to classifiers that focus deep computation on a small number of pre-selected genomic regions, i.e. the architectural shape that has succeeded in cancer detection. Such classifiers degrade sharply rather than gradually as $c(v)$ grows, with the transition provable from the geometry of the problem. Chronic-disease classification requires an architecture matched to its regime: compute allocated across a very large set of windows rather than into deeper per-cfDNA models, with $k \gtrsim c(v)$. We propose a concrete architecture and verify on synthetic experiments that the regime transition predicted by the theorem is observed, and the architecture outperforms cancer-style baselines on chronic-like signal. We then validate on real patient data, where the architecture exceeds both cancer-tuned methods and standard-of-care clinical tests.
World Action Verifier: Self-Improving World Models via Forward-Inverse Asymmetry
Yuejiang Liu ⋅ Fan Feng ⋅ Lingjing Kong ⋅ Weifeng Lu ⋅ Jinzhou Tang ⋅ Kun Zhang ⋅ Kevin Murphy ⋅ Chelsea Finn ⋅ Yilun Du
General-purpose world models promise scalable policy evaluation, optimization, and planning, yet achieving the required level of robustness remains challenging. Unlike policy learning which primarily focuses on optimal actions, a world model needs to be reliable over a vast space of suboptimal actions, which are often underrepresented in action-labeled robot interactions. To address this challenge, we propose World Action Verifier (WAV), a framework that enables world models to identify their own prediction errors and self-improve. The key idea is to decompose action-conditioned state prediction into two independently verifiable factors: state plausibility and action reachability. We show that verifying these factors is significantly more tractable than direct forward prediction due to two underlying asymmetries: the broader availability of action-free data and the lower dimensionality of action-relevant features. Leveraging these asymmetries, we augment a world model with (i) a diverse subgoal generator obtained from video corpora and (ii) a sparse inverse model that infers actions from a subset of state features. By enforcing cycle consistency among proposed subgoals, inferred actions, and forward rollouts, WAV provides an effective verification mechanism in under-explored regimes, where existing methods often fail. Across nine tasks spanning MiniGrid, RoboMimic, and ManiSkill, our method achieves 2$\times$ higher sample efficiency while improving downstream policy performance by over 22\%.